-
Creating Preferred IUPAC names
Language models model languages. The simpler the language, the simpler the model. Large language models (LLMs) do more: they do not merely capture a language, but also model what you can say with them. And you can map one model to another, and use that to translate things between langauges. Have a numerical representation, and you can have your LLM run on a processing unit (CPU, or more likely, GPU). More and more models are available (mostly proprietary, commercial) to use this. Chat bots, translation tools, grammar checkers, generative models. And because of the numerical representation, it is also easy enough to combine language with numerical data. -
Programming in the Life Sciences #24: past research questions
Fourteen years ago we started the Programming in the Life Sciences (PRA3006). The course is designed as a practical, because there surely is theory, but programming is also skills. Originally it was zooming in on pharmacology and the Open PHACTS webservices (see this, this, and this post). By now, the focus is on life sciences SPARQL endpoints. -
Peer reviewed articles about biological processes in WikiPathways
Earlier this year I blogged about a few collaborations where WikiPathways content has been created and/or curated. I mentioned that there are pathways in WikiPathways supported by a full paper, but I will leave that for a later moment. -
Open Science and Recognition & Rewards
In the past 10~ish years there has been a national push towards two themes aimed to improve things at our (academic) research institutes: Open Science and Recognition & Rewards. The first addresses the needs to allow (more) people to do research, while the second addresses the conditions under which we do research. The two Maastricht University pages about how my university looks at these topics are; -
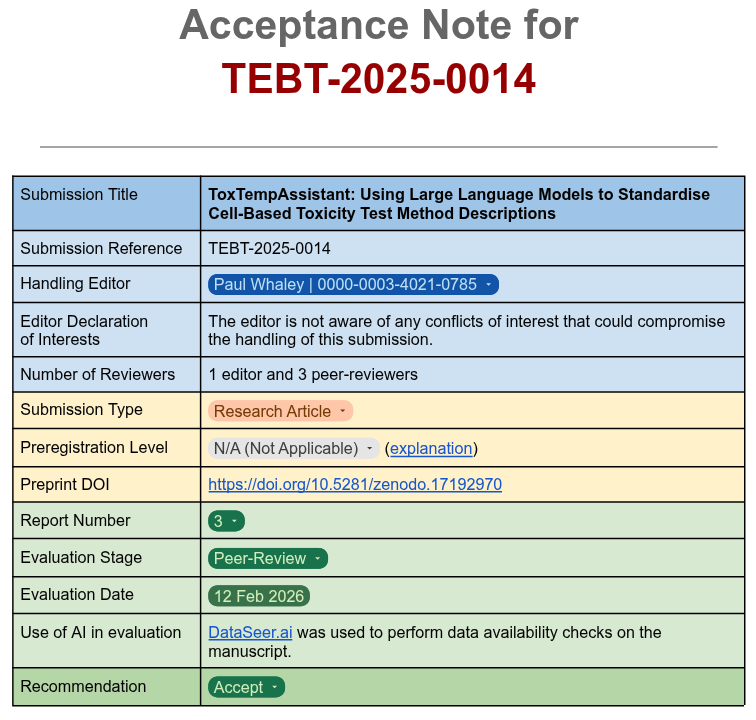
New paper: "ToxTempAssistant: using large language models to standardise cell-based toxicological test method descriptions"
Jente Houweling published her first PhD thesis chapter earlier this year: “ToxTempAssistant: using large language models to standardise cell-based toxicological test method descriptions” (doi:10.1080/2833373X.2026.2638036). So far, I have been blogging about many of the articles on which I am (co-)author. To put it in context. To reflect on the work. I have been postponing writing about this paper because there is a lot to reflect on. I will pick out two things. First, I look at the use of AI. The second is the unique, innovative publishing model of the journal where the article was published. If you want to just see it in action, ToxTempAssistant is running on the Virtual Human Platform for safety assessment. -
Retracting datasets?
A bit over half a year ago, Markus Englund wrote about copy/paste errors in scientific datasets. I believe that many of them are just because spreadsheets make these things easy, but when you look at the examples, and realize that routinely datasets are found with particularly non-random distributions if data, we know that some of this is fraud. Markus’ post is a must read. -
Green Open Access: where is the index?
Gold Open Access is literature that has an explicit open license, like CC-BY. It optionally has an article processing charge (APC). It optionally charges APC to make profit or to fund other activities, like some societies do. Green Open Access is literature that has been made available by repositories. It optionally has an open license. It optionally has a standardized license, like CC-BY. But it can also be that no clear license is given or the “license” refers to some (local) law.