<?xml version="1.0" encoding="UTF-8"?>
<feed xmlns="http://www.w3.org/2005/Atom">
  <generator uri="https://jekyllrb.com/" version="4.3.4">Jekyll</generator>
  <link href="https://chem-bla-ics.linkedchemistry.info/feed.xml" rel="self" type="application/atom+xml"/>
  <link href="https://chem-bla-ics.linkedchemistry.info" rel="alternate" type="text/html"/>
  <updated>2026-10-07T12:46:55+00:00</updated>
  <id>https://chem-bla-ics.linkedchemistry.info/archive.xml</id>
  <title type="html">chem-bla-ics</title>
  <subtitle>Chemblaics (pronounced chem-bla-ics) is the science that uses open science and computers to solve problems in chemistry, biochemistry and related fields.</subtitle>
  <author>
    <name>Egon Willighagen</name>
    <uri>https://orcid.org/0000-0001-7542-0286</uri>
  </author>

  
  <entry>
    <title type="html">Open Science and Recognition &amp; Rewards</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/10/05/open-science-recognition-and-rewards.html" rel="alternate" type="text/html" title="Open Science and Recognition &amp; Rewards"/>
    <published>2026-10-05T00:00:00+00:00</published>
    <updated>2026-10-05T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/gt194-05b24</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/10/05/open-science-recognition-and-rewards.html">
      <![CDATA[ <p>In the past 10~ish years there has been a national push towards two themes aimed to improve things
at our (academic) research institutes: Open Science and Recognition &amp; Rewards. The first addresses
the needs to allow (more) people to do research, while the second addresses the conditions under
which we do research. The two Maastricht University pages about how my university looks at these
topics are;</p>

<ul>
  <li><a href="https://www.maastrichtuniversity.nl/about-um/what-we-stand-for/recognition-rewards">Open Science</a></li>
  <li><a href="https://www.maastrichtuniversity.nl/about-um/what-we-stand-for/recognition-rewards">Recognition &amp; Rewards</a></li>
</ul>

<p>The provide a good number of additional pointers for important context.</p>

<p>Recognition &amp; Rewards generally is a very complex question. Just thinking about how people reply
to the <a href="https://en.wikipedia.org/wiki/2024_Cornell_University_rape_allegations">Cornell University rape allegations</a>.
Not every researchers is evaluated in the same way.</p>

<p>And then there is the highly complex approach how to compare researchers when the question of
promotion comes up: qualification or quantification. They both measure certain aspects of our
performance, but not all metrics (qualitative or quantitative) actually measure the performance
of the researcher. The journal impact factor is a clear example of that. The H-index is more
personal but also does not really measure what you want to use it for.
These things too return with <a href="https://open-science-monitoring.org/">Open science monitoring</a>.
We have to monitor such efforts critically (like we do with everything, the researchers we are).</p>

<p>The dynamics are fascinating. But they are also essential to my work. I am line manager of
multiple researchers, each with their own career paths. Under to modern HR, any Maastricht
University researcher can opt to use <a href="https://www.maastrichtuniversity.nl/over-de-um/waar-we-voor-staan/erkennen-waarderen/um-career-policy-compass">career compass</a>
option. This career policy gives our employees more freedom how to be evaluated. For example,
it gives more room for recognition for teaching and for patient care. But all routes have
four obligatory topics:</p>

<ul>
  <li>Academic citizenship</li>
  <li>Personal and professional leadership</li>
  <li>Team performance</li>
  <li>Impact &amp; Open Science</li>
</ul>

<p>In the evaluation meetings with your <em>development board</em> you will discuss how you
did on the activities related to your personal career compass. And then again the
qualifications and quantification come up. And that opens the can of worms.</p>

<p>Now, because open science and team science are used a lot in the
<a href="https://www.maastrichtuniversity.nl/research/translational-genomics/research/themes">Theme Bioinformatics</a>
of our <a href="https://www.maastrichtuniversity.nl/research/translational-genomics">Department of Translational Genomics</a>,
I like to know what options I have to recognize and reward that.</p>

<p>That is why I signed up for the <a href="https://library.maastrichtuniversity.nl/course/recognising-rewarding-open-science/">Recognising and Rewarding Open Science</a>
programme that started last week.</p>

      
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="openscience"/><category term="rnr"/><category term="maastricht"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/10/05/open-science-recognition-and-rewards.html">
      <![CDATA[ In the past 10~ish years there has been a national push towards two themes aimed to improve things at our (academic) research institutes: Open Science and Recognition &amp; Rewards. The first addresses the needs to allow (more) people to do research, while the second addresses the conditions under which we do research. The two Maastricht University pages about how my university looks at these topics are; ]]>
    </summary></entry>
  
  <entry>
    <title type="html">New paper: &quot;ToxTempAssistant: using large language models to standardise cell-based toxicological test method descriptions&quot;</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/10/03/new-paper-toxtempassistant-using-large-language-models-to-standardise-cell-based-toxicological-test-method-descriptions.html" rel="alternate" type="text/html" title="New paper: &quot;ToxTempAssistant: using large language models to standardise cell-based toxicological test method descriptions&quot;"/>
    <published>2026-10-03T00:00:00+00:00</published>
    <updated>2026-10-03T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/v5ehk-42y77</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/10/03/new-paper-toxtempassistant-using-large-language-models-to-standardise-cell-based-toxicological-test-method-descriptions.html">
      <![CDATA[ <p><a href="https://orcid.org/0009-0005-3680-0645">Jente Houweling</a> published her first PhD thesis chapter earlier this year:
“ToxTempAssistant: using large language models to standardise cell-based toxicological test method descriptions”
(doi:<a href="https://doi.org/10.1080/2833373X.2026.2638036">10.1080/2833373X.2026.2638036</a>). So far, I have been blogging about
many of the articles on which I am (co-)author. To put it in context. To reflect on the work. I have been postponing
writing about this paper because there is a lot to reflect on. I will pick out two things. First, I look at the use
of AI. The second is the unique, innovative publishing model of the journal where the article was published.
If you want to just see it in action, ToxTempAssistant is <a href="https://toxtempassistant.vhp4safety.nl/">running</a>
on the Virtual Human Platform for safety assessment.</p>

<p>Before we go there, just a quick note on what ToxTemps are and ToxTempAssistent actually is:</p>

<blockquote>
  <p>The ToxTemp template, based on OECD Guidance Document 211, standardises reporting for cell-based NAMs. However,
completing its 77 questions constitutes a substantial bottleneck. The aim of this study is to introduce ToxTempAssistant,
a Large Language Model (LLM)-assisted web tool that supports toxicologists in drafting ToxTemp documents based on
user-supplied context documents. This study quantifies the tool’s baseline performance under controlled conditions.
ToxTempAssistant uses grounded, per-question prompting with mandatory source attribution.</p>
</blockquote>

<h2 id="the-llm-aspects">The LLM aspects</h2>

<p>AI is very old. Arguably, <a href="https://chem-bla-ics.linkedchemistry.info/2009/05/04/thesis-and-copyright-transfer.html">my PhD thesis</a>
had this as key topic, though I preferred to use to term chemometric or machine learning.
Critical thinking has been essential to this field for a long time, and much of the PhD thesis is actually
about critically assessing the performance of the methods used in the thesis. There is decades of research
how you do this. Sadly, when it comes to Large Language Models (LLMs), these are not routinely used.</p>

<p>LLMs are indeed something new. I have seen <a href="https://en.wikipedia.org/wiki/Natural_language_processing">natural language processing</a>
research when I was Cambridge with Peter Murray-Rust. The current LLMs are different, less deterministic, more probabilistic.
From a chemometrics perspective, that makes sense. Language is complex, and not so deterministic in itself. Moreover,
when representing words, sentences as numbers, you can integrate any resource (think data tables, images, etc). Even more,
digital representation was even more the central theme of my PhD thesis.</p>

<p>But because of the nature of the method, the nature of how the commercial, better known models are trained (and the
impact on the notion of copyright), the impact on the <a href="https://en.wikipedia.org/wiki/Climate_crisis">climate emergency</a>,
the black box that these LLMs often are, there are so many technical, scientific, and ethical reasons to stay away from them.</p>

<p>You can write books about that. Literally (I did not read them yet):</p>

<ul>
  <li><a href="https://en.wikipedia.org/wiki/The_Nerd_Reich">The Nerd Reich</a></li>
  <li><a href="https://en.wikipedia.org/wiki/The_AI_Con">The AI Con</a></li>
</ul>

<p>(I have the feeling I am missing one title I wanted to highlight. If I remember, I will add it.)</p>

<p>And more <a href="https://www.goodreads.com/shelf/show/ai-critique">here</a> and <a href="https://womeninaiethics.org/ai-ethics-book-list-for-2024/">here</a>.
And I am looking forward to reading <em>Deep Unlearning: The Rise of AI and the Radicalization of a Tech Idealist</em>.
Also, I recommend at least following <a href="http://dair-community.social/@timnitGebru">Timnit Gebru</a> and
<a href="https://dair-community.social/@emilymbender">Emily Bender</a>.</p>

<p>A year ago, I signed the <a href="https://chem-bla-ics.linkedchemistry.info/2025/08/18/ai-technologies-in-academia.html">Open Letter: Stop the Uncritical Adoption of AI Technologies in Academia</a>,
now signed by more than 2,000 people (it is <a href="https://openletter.earth/open-letter-stop-the-uncritical-adoption-of-ai-technologies-in-academia-b65bba1e">not too late</a>).</p>

<p>So, with all these things mind, I am happy that Jente did critically adopt LLMs in her work. The paper includes
various experiments to explore the impact of various model parameters on generating nonsense. She also explored
to use of alternative LLMs platforms, opening the option that some day it runs on other, more ethical platforms.
ToxTempAssistant, moreover, limits the material it takes information from, from a limited set of sources, provided
by the users. Of course, the model itself is still training on resources with questionable provenance.</p>

<p>Jente’s paper describes the use of positive and negative controls to put the performance in perspective.
In doing so, the paper formalizes how to evaluate the use of LLMs in situations where the LLM is used
to summarize other reports, a common thing to do. This allows us to monitor the impact of, for example,
new LLM releases.</p>

<p>The results are promising and various independent projects have shown interest in adoption. The ToxTemp
reports are important for safety assessment: they provide essential context to experimental results and
as such essential to the FAIR-ness of toxicology data.</p>

<h2 id="open-peer-review">Open Peer Review</h2>

<p>The ToxTempAssistant paper is published in the relatively new journal <a href="https://www.tandfonline.com/journals/tebt20">Evidence-Based Toxicology</a> (EBT):</p>

<blockquote>
  <p>Evidence-Based Toxicology is a broad-focus, gold open-access journal, created to support the use of open science practices and
evidence-based methods in toxicology and environmental health.</p>
</blockquote>

<p>So, CC-BY license (gold open access) and support for Open Science. And Open Peer Review, as we will see. Also,
I understand it is not a diamond open access journal, so expect APCs.</p>

<p>The journal has <a href="https://zenodo.org/communities/ebt/records">a community on Zenodo</a> for preprints and peer-reviews.
I think this is a really nice choice. Of course, a journal specific preprint server has downsides too. For example,
if it gets rejected from EBT, do you use the EBT preprint server when submitting to another journal? Do you upload
a new version (after all, you should address some of the comments why it was rejected) to another preprint server?</p>

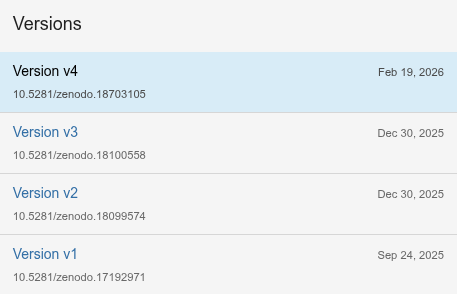
<p>The EBT preprint gets a record and revisions are uploaded as new versions to the same Zenodo record
(doi<a href="https://doi.org/10.5281/zenodo.17192970">10.5281/zenodo.17192970</a>):</p>

<p><img src="/assets/images/ebt_preprint_tta.png" alt="" /></p>

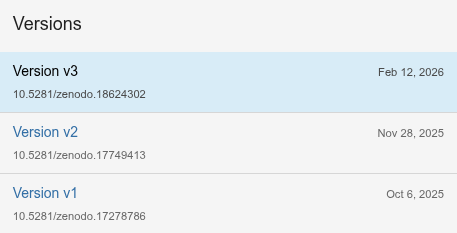
<p>But because EBT uses open peer review, there is a parallel Zenodo entry with the reviews
(doi<a href="https://doi.org/10.5281/zenodo.17278785">10.5281/zenodo.17278785</a>):</p>

<p><img src="/assets/images/ebt_preprint_tta_reviews.png" alt="" /></p>

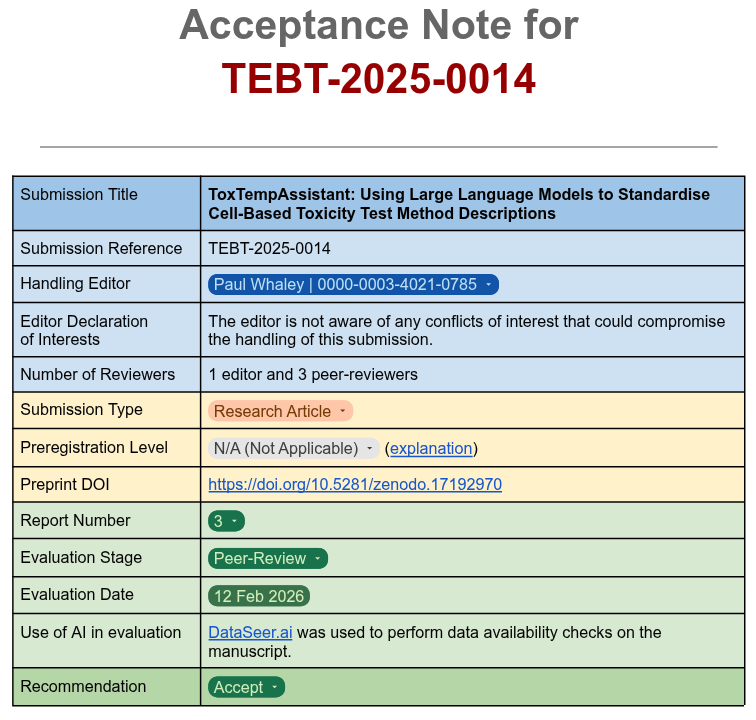
<p>The last version here is the acceptance notice:</p>

<p><img src="/assets/images/ebt_preprint_tta_acceptance.png" alt="" /></p>

<p>One of the reviewer suggestions was to use the TRIPOD-LLM template
(doi:<a href="https://doi.org/10.1038/s41591-024-03425-5">10.1038/s41591-024-03425-5</a>), which was included in a
later revision. That made a lot of sense and is a nice example how the journal actively works
on applying open science ideas. The journal webpage writes:</p>

<blockquote>
  <p>We define “open science” as the set of practices aimed at improving the transparency, validity,
reproducibility, and accessibility of scientific research, while promoting equality of
opportunity to participate in and benefit from the products of said research.</p>
</blockquote>

<p>One comment here is that the template asks on what page that point of the checklist is discussed
in the article. That is nice, but links it directly to the revision of the manuscript that
form applies too, but that is not reported in the template. Not ideal. Then again, the point
is the checking, so maybe not a big deal.</p>

<p>Another comment is that it seems the journal website’s page for the article does not seem to actually
link to the preprints nor the peer-review reports (or acceptance note). So, in time, these
open science aspects of this article will likely get lost in time. Who will find those reports
if the article does not cite them? This will require Taylor&amp;Francis to modernize the publishing
model, and I sincerely doubt that that will ever happen.</p>

<p>Prof. <a href="https://orcid.org/0000-0002-6465-4498">Anne Kienhuis</a>, one of the co-authors, suggested
this journal lead by Prof. <a href="https://orcid.org/0000-0003-4021-0785">Paul Whaley</a>.
And I am happy to have seen this new approach in action and like to thank Paul for pushing for
these innovations. I recommend trying it yourself for your next toxicology work.</p>

      
<h4>References</h4>
<div class="csl-bib-body">
    <div class="csl-entry">Gallifant, J., Afshar, M., Ameen, S., Aphinyanaphongs, Y., Chen, S., Cacciamani, G., Demner-Fushman, D., Dligach, D., Daneshjou, R., Fernandes, C., Hansen, L. H., Landman, A., Lehmann, L., McCoy, L. G., Miller, T., Moreno, A., Munch, N., Restrepo, D., Savova, G., … Bitterman, D. S. (2025). The TRIPOD-LLM reporting guideline for studies using large language models. <i>Nature Medicine</i>, <i>31</i>(1), 60–69. https://doi.org/10.1038/s41591-024-03425-5 <b>[cito:discusses]</b> <a href="https://doi.org/10.1038/s41591-024-03425-5">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1038/s41591-024-03425-5">Scholia</a></div>
    <div class="csl-entry">Houweling, J. (Johanne) M., Arras, M. M., Willighagen, E., Kienhuis, A., Jennen, D., &#38; Evelo, C. (2026). ToxTempAssistant: Using Large Language Models to Standardise Cell-Based Toxicity Test Method Descriptions. <i>Zenodo</i>. https://doi.org/10.5281/ZENODO.17192970 <b>[cito:citesAsEvidence]</b> <a href="https://doi.org/10.5281/zenodo.17192970">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.5281/zenodo.17192970">Scholia</a></div>
    <div class="csl-entry">Houweling, J. M., Arras, M. M. L., Willighagen, E. L., Jennen, D. G. J., Evelo, C. T., &#38; Kienhuis, A. S. (2026). <i>ToxTempAssistant</i>                     : using large language models to standardise cell-based toxicological test method descriptions. <i>Evidence-Based Toxicology</i>, <i>4</i>(1). https://doi.org/10.1080/2833373x.2026.2638036 <b>[cito:discusses]</b> <a href="https://doi.org/10.1080/2833373X.2026.2638036">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1080/2833373X.2026.2638036">Scholia</a></div>
    <div class="csl-entry">Krebs, A., Waldmann, T., Wilks, M. F., van Vugt-Lussenburg, B. M. A., van der Burg, B., Terron, A., Steger-Hartmann, T., Ruegg, J., Rovida, C., Pedersen, E., Pallocca, G., Luijten, M., Leite, S. B., Kustermann, S., Kamp, H., Hoeng, J., Hewitt, P., Herzler, M., Hengstler, J. G., … Leist, M. (2019). https://www.altex.org/index.php/altex/article/view/1339. <i>ALTEX</i>, 682–699. https://doi.org/10.14573/altex.1909271 <b>[cito:citesForInformation]</b> <a href="https://doi.org/10.14573/altex.1909271">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.14573/altex.1909271">Scholia</a></div>
    <div class="csl-entry">Whaley, P. (2026). <i>Evaluation Reports for TEBT-2025-0014 | Houweling et al.</i> Zenodo. https://doi.org/10.5281/ZENODO.17278785 <b>[cito:citesAsEvidence]</b> <a href="https://doi.org/10.5281/zenodo.17278785">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.5281/zenodo.17278785">Scholia</a></div>
  </div>
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="fair"/><category term="llm"/><category term="vhp4safety"/><category term="mycito:discusses:10.1080/2833373X.2026.2638036"/><category term="cito:citesForInformation:10.14573/altex.1909271"/><category term="openscience"/><category term="cito:citesAsEvidence:10.5281/zenodo.17278785"/><category term="cito:citesAsEvidence:10.5281/zenodo.17192970"/><category term="cito:discusses:10.1038/s41591-024-03425-5"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/10/03/new-paper-toxtempassistant-using-large-language-models-to-standardise-cell-based-toxicological-test-method-descriptions.html">
      <![CDATA[ Jente Houweling published her first PhD thesis chapter earlier this year: “ToxTempAssistant: using large language models to standardise cell-based toxicological test method descriptions” (doi:10.1080/2833373X.2026.2638036). So far, I have been blogging about many of the articles on which I am (co-)author. To put it in context. To reflect on the work. I have been postponing writing about this paper because there is a lot to reflect on. I will pick out two things. First, I look at the use of AI. The second is the unique, innovative publishing model of the journal where the article was published. If you want to just see it in action, ToxTempAssistant is running on the Virtual Human Platform for safety assessment. ]]>
    </summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/ebt_preprint_tta_acceptance.png"/>
    <media:content xmlns:media="http://search.yahoo.com/mrss/" medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/ebt_preprint_tta_acceptance.png"/></entry>
  
  <entry>
    <title type="html">Retracting datasets?</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/09/27/retracting-datasets.html" rel="alternate" type="text/html" title="Retracting datasets?"/>
    <published>2026-09-27T00:00:00+00:00</published>
    <updated>2026-09-27T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/x7zsv-0c792</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/09/27/retracting-datasets.html">
      <![CDATA[ <p>A bit over half a year ago, <a href="https://www.sciencedetective.org/scientific-datasets-are-riddled-with-copy-paste-errors/">Markus Englund wrote about copy/paste errors in scientific datasets</a>.
I believe that many of them are just because spreadsheets make these things easy, but when you look at
the examples, and realize that routinely datasets are found with particularly non-random distributions
if data, we know that some of this is fraud. Markus’ post is a must read.</p>

<p>It me also made me realize something else. We have <a href="https://chem-bla-ics.linkedchemistry.info/2015/03/22/what-youre-doing-is-rather-desperate.html">by now</a>
a good practise of tracking retracted articles, and platforms to discuss articles openly,
like <a href="https://pubpeer.com/">PubPeer</a>. The second can be used for datasets too,
when they are deposited in DOI-providing resources, like Zenodo or Figshare.</p>

<p>Fraudulent data can certainly result in papers that describe the data to be
retracted. But retracting the publication does not mean the paper does not get
cited anymore, see doi:<a href="https://link.springer.com/article/10.1007/s11192-020-03631-1">10.1007/s11192-020-03631-1</a>
or <a href="https://qlever.scholia.wiki/retraction/Q28264479#citations-per-year">Scholia for retraction data</a>.
But data that starts having a live on its own after the deposit in some archive
may worsen this problem. After all, our practises for sharing retraction flags
and concerns are even without this substandard.</p>

<p>Should we not also start taking more care about the data we publish? Track concerns
about them? Maybe even a way to retract datasets, when fraud was in play?</p>

      
<h4>References</h4>
<div class="csl-bib-body">
    <div class="csl-entry">Schneider, J., Ye, D., Hill, A. M., &#38; Whitehorn, A. S. (2020). Continued post-retraction citation of a fraudulent clinical trial report, 11 years after it was retracted for falsifying data. <i>Scientometrics</i>, <i>125</i>(3), 2877–2913. https://doi.org/10.1007/s11192-020-03631-1 <b>[cito:citesAsEvidence]</b> <a href="https://doi.org/10.1007/s11192-020-03631-1">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1007/s11192-020-03631-1">Scholia</a></div>
  </div>
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="data"/><category term="cito:citesAsEvidence:10.1007/s11192-020-03631-1"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/09/27/retracting-datasets.html">
      <![CDATA[ A bit over half a year ago, Markus Englund wrote about copy/paste errors in scientific datasets. I believe that many of them are just because spreadsheets make these things easy, but when you look at the examples, and realize that routinely datasets are found with particularly non-random distributions if data, we know that some of this is fraud. Markus’ post is a must read. ]]>
    </summary></entry>
  
  <entry>
    <title type="html">Green Open Access: where is the index?</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/09/24/green-open-access-where-is-the-index.html" rel="alternate" type="text/html" title="Green Open Access: where is the index?"/>
    <published>2026-09-24T00:00:00+00:00</published>
    <updated>2026-09-24T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/1qayb-w6z38</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/09/24/green-open-access-where-is-the-index.html">
      <![CDATA[ <p><a href="https://legacy.earlham.edu/~peters/fos/overview.htm">Gold Open Access</a> is literature that has an explicit open license, like CC-BY.
It optionally has an article processing charge (APC). It optionally charges APC to make profit or to fund other activities, like
some societies do.
<a href="https://legacy.earlham.edu/~peters/fos/overview.htm">Green Open Access</a> is literature that has been made available by
repositories. It optionally has an open license. It optionally has a standardized license, like CC-BY. But it can also
be that no clear license is given or the “license” refers to some (local) law.</p>

<p>Many universities have green Open Access repositories, like <a href="https://cris.maastrichtuniversity.nl/">Maastricht University</a>
and <a href="https://repository.ubn.ru.nl/">Radboud University</a>. These repositories are scattered and contrary to FAIR principles,
metadata is not shared widely.
Of course, prominently, scholarly publishers could provide that information. Any paywalled journal article could have a link to
a legal green open access version. It could. It would make total sense if spreading scientific knowledge is your goal.
But we live in an alternate universe.</p>

<p>We are relying on third-party indexes. I here briefly describe two options, but love to read blog posts about other
alternatives! I am not looking for routes like <a href="https://pmc.ncbi.nlm.nih.gov/">PubMed Central</a> or
<a href="https://europepmc.org/">Europe PMC</a> that come with huge collections of open-licensed content, including
<a href="https://chem-bla-ics.linkedchemistry.info/2024/09/16/publishing.html">in the FAIR JATS format</a></p>

<p>It’s really the non-OA-licensed green Open Access that we need to get indexed better.</p>

<p>Oh, and, of course, <a href="https://chem-bla-ics.linkedchemistry.info/2026/08/07/scientias-oudheidkunde-wetenschap-hoe-dan.html">all Dutch literature must become green Open Access</a>.</p>

<h2 id="openalex">OpenAlex</h2>

<p><a href="https://unpaywall.org/">Unpaywall</a> (see also <a href="https://chem-bla-ics.linkedchemistry.info/2025/01/04/isaac-browser-extension.html">this post</a>)
has been collecting open access versions but is <a href="https://help.openalex.org/access/unpaywall/#unpaywall-and-openalex">now including in OpenAlex</a>.
The <a href="https://help.openalex.org/data/works/open-access/">annotation is quite rich</a> and here the question is more,
how can the open science community enrich this OpenAlex content.</p>

<h2 id="wikidata-and-wikicite">Wikidata and WikiCite</h2>

<p><a href="https://www.wikidata.org/">Wikidata</a> and <a href="https://www.wikidata.org/wiki/Wikidata:WikiCite">WikiCite</a> are projects aligned with
Wikipedia, and <em>[citation needed]</em> is an
essential part of that. We have <a href="https://chem-bla-ics.linkedchemistry.info/tag/wikidata">used it in our research</a>
in multiple occassions. The curation process is transparent, providing the essential provenance
needed for scientific research.</p>

<p>It provides the <a href="https://www.wikidata.org/wiki/Property:P953">work available at URL</a> property and it
has been used to link to green Open Access versions. The extend, however, is less clear (to me). But another
problem is that Wikidata does not have the ambition to be a generic solution. That said, all extra links
help.</p>

<h2 id="schemaorg-and-web-search-indexes">Schema.org and web search indexes?</h2>

<p>That leaves me, for now, with the role of generic web searching. Doesn’t that help? I can just search for
the article title, right? Well, yes. But the process of how to get your green open access article indexed
is not clear. There are many metadata standards that your repository needs to support (e.g.
<a href="https://help.openalex.org/access/unpaywall/#unpaywall-and-openalex">OpenAlex lists 8</a> and that does not include schema.org)
and that does not guarantee you get indexed. Worse, commercial companies are know to remove content in a opague
process, like with <a href="https://mastodon.social/@Roelmaalderink/117319021973126519">this video about the Meta gluurbril</a>.
We cannot trust that green open access metadata gets preserved.</p>

<p>Maybe <a href="https://motherduck.com/blog/querying-the-entire-internet-100-billion-rows-with-motherduck/">open web indexes</a>
will make a difference, but then we still need a simple API to integrate into our tools that just
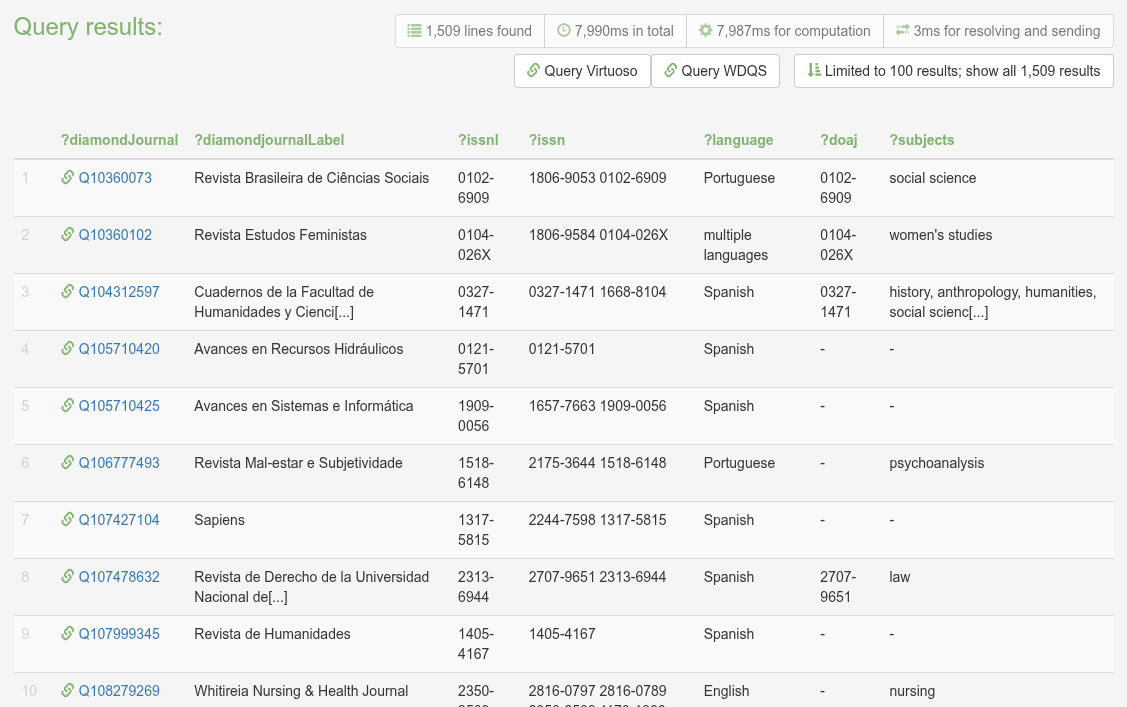
returns the information. I had a go at this last weekend. It would look
<a href="https://mastodon.social/@egonw/117302574373386172">something like this</a>:</p>

<p><img src="/assets/images/greenOA_URLs.png" alt="" /></p>

<p>But things go slowly, and FAIR metadata most certainly. But if we consistently take steps, things do change.
For example, after 20+ years, CrossRef now supports <a href="https://www.crossref.org/blog/schema-5.5-now-available-adding-credit-new-record-types-for-blogs-and-posters-and-more/">blog as research output type</a>.</p>

<p>I like to stress, metadata is being shared by repositories, but we should support this a bit more. We should
reuse that data, support that, curate that, etc. Let’s support our fellow open science community members!
And that starts by sharing our knowledge on how all this works, does not work, could work, and
what small steps we can take today and tomorrow. Looking foward to your ideas!</p>

      
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="publishing"/><category term="openaccess"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/09/24/green-open-access-where-is-the-index.html">
      <![CDATA[ Gold Open Access is literature that has an explicit open license, like CC-BY. It optionally has an article processing charge (APC). It optionally charges APC to make profit or to fund other activities, like some societies do. Green Open Access is literature that has been made available by repositories. It optionally has an open license. It optionally has a standardized license, like CC-BY. But it can also be that no clear license is given or the “license” refers to some (local) law. ]]>
    </summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/greenOA_URLs.png"/>
    <media:content xmlns:media="http://search.yahoo.com/mrss/" medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/greenOA_URLs.png"/></entry>
  
  <entry>
    <title type="html">WikiPathways: biological pathways across the species</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/09/09/wikipathways-biological-pathways-across-the-species.html" rel="alternate" type="text/html" title="WikiPathways: biological pathways across the species"/>
    <published>2026-09-09T00:00:00+00:00</published>
    <updated>2026-09-09T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/pgq2r-6xj29</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/09/09/wikipathways-biological-pathways-across-the-species.html">
      <![CDATA[ <p>I was not there. I only joined the <a href="https://wikipathways.org/">WikiPathways</a> project in late 2011, just as a contributor.
And it was just before joining the
<a href="https://www.maastrichtuniversity.nl/research/bioinformatics">BiGCaT research team</a> of Prof. Chris Evelo in January 2012,
where I started a project in the <a href="https://en.wikipedia.org/wiki/OpenPHACTS">Open PHACTS</a> project, not really about WikiPathways,
but the open science WikiPathways was the main reason for me to join the group. Open PHACTS was close to my research and
just created that opportunity.</p>

<p>WikiPathways was already around five years old when I created my account. It was created in January 2007
(doi:<a href="https://doi.org/10.1038/npre.2010.5361.1">10.1038/npre.2010.5361.1</a>). It was first formally published in 2008
(doi:<a href="https://doi.org/10.1371/journal.pbio.0060184">10.1371/journal.pbio.0060184</a>), so the project is about 20 years
old (maybe a new WikiPathways conference next year?). The launch made it to Science
(doi:<a href="https://doi.org/10.1126/science.321.5889.623c">10.1126/science.321.5889.623c</a>):</p>

<blockquote>
  <p>The makers of GenMAPP [..] have launched a site for
sharing findings on metabolic pathways. [..]
WikiPathways (wikipathways.org) offers a way to integrate
information on these complex networks [..]
The site has more than 300 registered users and contains
information on 500 metabolic pathways in seven species,
including humans.</p>
</blockquote>

<p>And Nature (doi:<a href="https://doi.org/10.1038/455022A">10.1038/455022A</a>):</p>

<blockquote>
  <p>Alexander Pico remembers just when the idea hit him. In January 2007, he and his boss, Bruce Conklin, were discussing
how to push their software tool for visualizing intracellular signalling pathways to the next level of interactivity —
when Pico blurted out, “What we really need is a wiki!”</p>
</blockquote>

<p>Just like review article curate and put primary literature in context, so that WikiPathways.
They pitched it at the time as modelled after Wikipedia, but surely it is also just as well modelled
after traditional knowledge dissemination approaches. One can easily argue that the wiki approach is
essential: anyone can create an account. And this has been held against WikiPathways. But if you look
at the who actually edits WikiPathways, these are only people working in an academic research
environment.</p>

<p>WikiPathways is, of course, used as a reference knowledgebase, and the use in pathway enrichment and
networking approaches are perhaps the best known. Another aspect of a wiki, however, is the community approach:
a community can work out a collection of machine-readable (FAIR) pathway models, even when the discovery is in full swing.
WikiPathways is also a platform to exchange knowledge, discuss literature, do research. The use to of
this feature turned out <a href="https://chem-bla-ics.linkedchemistry.info/2020/05/07/new-project-covid-19-disease-maps.html">really useful at the start of the COVID-19 pandemic</a>.</p>

<h2 id="genomes-species-and-pathways">Genomes, species, and pathways</h2>

<p>The set of full genome assemblies was not that large; in 2021 there were 3278 genome assemblies for animal species
(doi:<a href="https://doi.org/10.1073/pnas.2109019118">10.1073/pnas.2109019118</a> and the <em>Genomes on a Tree</em>
(doi:<a href="https://doi.org/10.12688/wellcomeopenres.18658.1">10.12688/wellcomeopenres.18658.1</a>) reports 27883 assemblies
for <a href="https://goat.genomehubs.org/search?result=taxon&amp;taxonomy=ncbi&amp;includeEstimates=true&amp;report=histogram&amp;x=assembly_date&amp;rank=species&amp;cat=assembly_level%5B4%5D%3Dscaffold%2Cchromosome%2Ccontig%2Ccomplete%20genome&amp;stacked=true&amp;excludeAncestral%5B0%5D=assembly_span&amp;excludeMissing%5B0%5D=assembly_span&amp;caption=Progress%20of%20genome%20assemblies%20published%20on%20INSDC%20over%20time%2C%20by%20assembly%20level&amp;offset=0&amp;xOpts=&amp;fields=assembly_date%2Cgenome_size%2Cassembly_level%2Cassembly_span%2Cchromosome_number%2Chaploid_number&amp;includeDescendants=false&amp;emptyColumns=false&amp;query=tax_rank%28species%29%20AND%20assembly_date%3E%3D1925-01-01%20AND%20assembly_date%3C2027-01-01%20AND%20assembly_level%3Dcomplete%20genome#tax_rank(species)%20AND%20assembly_date%3E%3D1925-01-01%20AND%20assembly_date%3C2027-01-01%20AND%20assembly_level%3Dcomplete%20genome">664 complete genomes</a>.</p>

<p>For WikiPathways, seven species in 2008 grew to <a href="https://www.wikipathways.org/browse/organisms">39 species today</a> today,
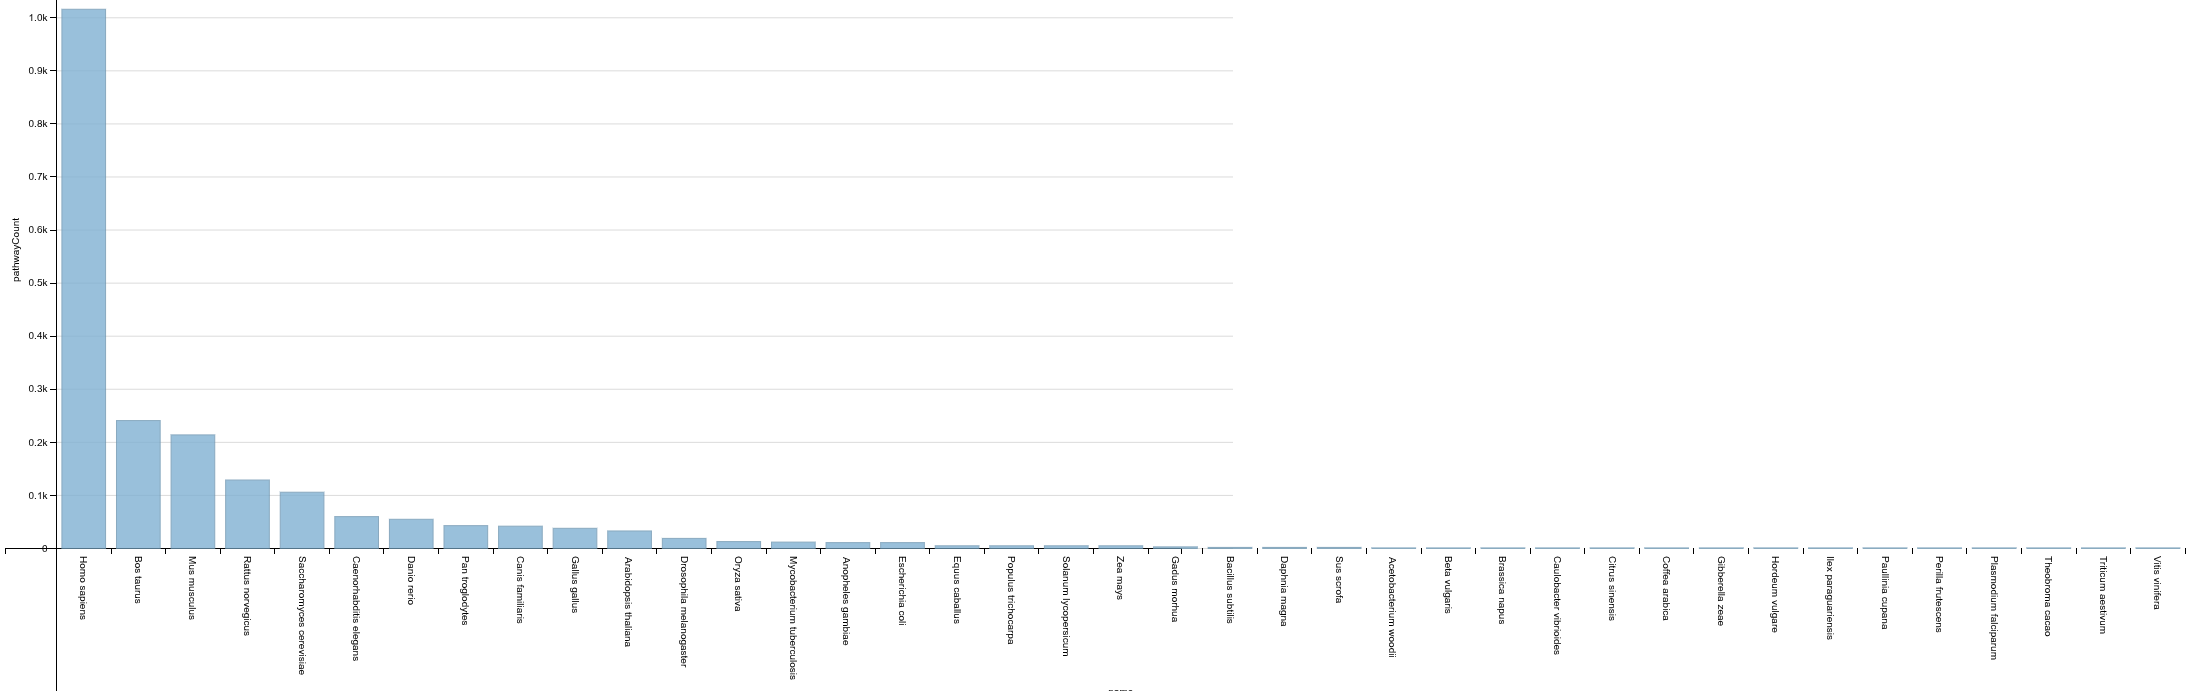
though many of them only have a few curated pathways. Indeed, human is still the predominent species, in number of
pathways (visualized with <a href="https://edu.nl/8644d">this SPARQL query</a>).</p>

<p><a href="https://query.wikidata.org/#%23defaultView%3ABarChart%0APREFIX%20dc%3A%20%3Chttp%3A%2F%2Fpurl.org%2Fdc%2Felements%2F1.1%2F%3E%0APREFIX%20wp%3A%20%3Chttp%3A%2F%2Fvocabularies.wikipathways.org%2Fwp%23%3E%0A%0ASELECT%20%2a%20WHERE%20%7B%0A%20%20SELECT%20DISTINCT%20%28str%28%3Flabel%29%20as%20%3Fname%29%20%3Forganism%20%28count%28%3Fpw%29%20as%20%3FpathwayCount%29%0A%20%20WHERE%20%7B%0A%20%20%20%20SERVICE%20%3Chttps%3A%2F%2Fsparql.wikipathways.org%2Fsparql%3E%20%7B%0A%20%20%20%20%20%20%3Fpw%20dc%3Atitle%20%3Ftitle%20%3B%0A%20%20%20%20%20%20%20%20wp%3Aorganism%20%3Forganism%20%3B%0A%20%20%20%20%20%20%20%20wp%3AorganismName%20%3Flabel%20.%0A%20%20%20%20%7D%0A%20%20%7D%20GROUP%20BY%20%3Flabel%20%3Forganism%0A%7D%0AORDER%20BY%20DESC%28%3FpathwayCount%29"><img src="/assets/images/wp_pws_per_species.png" alt="" /></a></p>

<p>That said, several communities have worked in the past to create
<a href="https://chem-bla-ics.linkedchemistry.info/2026/02/22/where-do-the-wikipathways-come-from.html">sets of pathways</a>
around specific species. In that post, I already mentioned Wormbase, but we also have a collection of pathways
from <a href="https://pathway.yeastgenome.org/">YeastPathways</a> (doi:<a href="https://doi.org/10.1093/genetics/iyae185">10.1093/genetics/iyae185</a>),
for example <a href="https://www.wikipathways.org/pathways/WP137">wikipathways:WP137</a>.
Now, the yeast pathways are not in sync with the upstream SDG YeastPathways, I think, so there is some
curation to do on our side (from the 2025 Genetics paper):</p>

<blockquote>
  <p>As the first major update since 2012, we updated 62 pathways with expert summaries on
pathway genetics, biochemistry, regulation, and more. Thirty-three new pathways with
specificity for yeast biochemistry were propagated from MetaCyc at SRI (Caspi et al. 2018),
and 105 existing pathways were edited for proper enzymatic classification, reaction
connectivity, and gene attribution. Compounds that were previously missing a chemical
structure have also now been updated, along with the stoichiometry and scheme of many
pathway reactions.</p>
</blockquote>

<p>In similar style, WikiPathways has had similar project around setting up a pathway collection
for a new species, like cow in a project by <a href="https://www.wikipathways.org/authors/Zari.html">Zahra Roudbari</a>
(doi:<a href="https://doi.org/10.3389/fgene.2019.01370">10.3389/fgene.2019.01370</a>).
And more recently <a href="https://www.wikipathways.org/organisms/cod">atlantic cod</a>
(ongoing research by <a href="https://www.wikipathways.org/authors/MadhushriMSV.html">Madhushri S. Varunjikar</a>
from the Norwegian <a href="https://www.hi.no/">Institute of Marine Research</a>).</p>

<h2 id="homology-converted-pathways">Homology converted pathways</h2>

<p>But WikiPathays also has a feature to convert pathways from one species to another. With more and
more whole genome assemblies becoming available, so are mappings of genes between one species and
another. This is the basis of that cow project (from <a href="https://doi.org/10.3389/fgene.2019.01370">the article</a>):</p>

<blockquote>
  <p>The online biological pathway repository, WikiPathways (Slenter et al., 2017), contains pathways
of different species, however a B. taurus collection was missing.</p>
</blockquote>

<p>And:</p>

<blockquote>
  <p>Second, the WikiPathways homology based the homology mapper which is available at GitHub
(https://github.com/PathVisio/homology.mapper) was updated to improve homology coverage for gene
products that were annotated with different data sources. The pathways were converted from human
pathways, with a required minimum successful conversion of at least 50% of the original human genes.</p>
</blockquote>

<p>The question is, of course, what is the best model species to use. That decision can be based on
multiple aspect, including the use case. There is freedom.</p>

<p>So, when this week the book chapter <em>Xenbase: A Guide to the Xenopus Genetics and Genomics Knowledgebase</em>
was published (doi:<a href="https://doi.org/10.1007/978-1-0716-5360-9_3">10.1007/978-1-0716-5360-9_3</a>), and
I was pinged WikiPathways was cited, I started reading.</p>

<blockquote>
  <p>WikiPathways are linked via gene symbol (Fig. 6A, black arrow) link redirects to a pre-set gene
symbol search on this community-curated open science resource [20].</p>
</blockquote>

<p>The linking via gene symbol made me write up this post. If they have the mappings, then with
the <a href="https://github.com/PathVisio/homology.mapper">GPML Homology Mapper</a> we can create pathways
for the two frog species (<em>X. laevis</em> and <em>X. tropicalis</em>).</p>

<h2 id="species-specific-curation">Species specific curation</h2>

<p>And there are reasons to do that. WikiPathways allows you to cite literature, at a pathway level,
for a gene, protein, or metabolite, and even at the level of an interaction. That literature is
species specific. The curation can also work out what to do with those parts of pathways for
which no genes were mapped. Having this is machine-readable knowledge has shown to be of
great usability, at the very least making the knowledge much, much easier to find.</p>

<p>And that brings us back to another role of review articles, of book chapters giving expert overviews,
but also of wiki’s: put knowledge in perspective of the literature from which it is derived.
I wish pathways database, generally, are used to communicate and get peer reviewed the fruits
of the work studying the biological processes on all these species.</p>

<p>With more than 600 full genomes and 39 species in WikiPathays, we have an exciting and growing seed.</p>

      
<h4>References</h4>
<div class="csl-bib-body">
    <div class="csl-entry">Challis, R., Kumar, S., Sotero-Caio, C., Brown, M., &#38; Blaxter, M. (2023). Genomes on a Tree (GoaT): A versatile, scalable search engine for genomic and sequencing project metadata across the eukaryotic tree of life. <i>Wellcome Open Research</i>, <i>8</i>, 24. https://doi.org/10.12688/wellcomeopenres.18658.1 <a href="https://doi.org/10.12688/wellcomeopenres.18658.1">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.12688/wellcomeopenres.18658.1">Scholia</a></div>
    <div class="csl-entry">Engel, S. R., Aleksander, S., Nash, R. S., Wong, E. D., Weng, S., Miyasato, S. R., Sherlock, G., &#38; Cherry, J. M. (2024). <i>Saccharomyces</i>                     Genome Database: advances in genome annotation, expanded biochemical pathways, and other key enhancements. <i>GENETICS</i>, <i>229</i>(3). https://doi.org/10.1093/genetics/iyae185 <a href="https://doi.org/10.1093/genetics/iyae185">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1093/genetics/iyae185">Scholia</a></div>
    <div class="csl-entry">Hotaling, S., Kelley, J. L., &#38; Frandsen, P. B. (2021). Toward a genome sequence for every animal: Where are we now? <i>Proceedings of the National Academy of Sciences</i>, <i>118</i>(52). https://doi.org/10.1073/pnas.2109019118 <a href="https://doi.org/10.1073/pnas.2109019118">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1073/pnas.2109019118">Scholia</a></div>
    <div class="csl-entry">James-Zorn, C., Ponferrada, V. G., &#38; Zorn, A. (2026). Xenbase: A Guide to the Xenopus Genetics and Genomics Knowledgebase. In <i>Methods in Molecular Biology</i> (pp. 57–122). Springer US. https://doi.org/10.1007/978-1-0716-5360-9_3 <a href="https://doi.org/10.1007/978-1-0716-5360-9_3">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1007/978-1-0716-5360-9_3">Scholia</a></div>
    <div class="csl-entry">Pico, A. R., Kelder, T., van Iersel, M. P., Hanspers, K., Conklin, B. R., &#38; Evelo, C. (2008). WikiPathways: Pathway Editing for the People. <i>PLoS Biology</i>, <i>6</i>(7), e184. https://doi.org/10.1371/journal.pbio.0060184 <a href="https://doi.org/10.1371/journal.pbio.0060184">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1371/journal.pbio.0060184">Scholia</a></div>
    <div class="csl-entry">Pico, A., &#38; Pico, A. (2010). WikiPathways: Community Curation of Biological Pathways. <i>Nature Precedings</i>. https://doi.org/10.1038/npre.2010.5361 <a href="https://doi.org/10.1038/npre.2010.5361.1">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1038/npre.2010.5361.1">Scholia</a></div>
    <div class="csl-entry">Roudbari, Z., Coort, S. L., Kutmon, M., Eijssen, L., Melius, J., Sadkowski, T., &#38; Evelo, C. T. (2020). Identification of Biological Pathways Contributing to Marbling in Skeletal Muscle to Improve Beef Cattle Breeding. <i>Frontiers in Genetics</i>, <i>10</i>. https://doi.org/10.3389/fgene.2019.01370 <a href="https://doi.org/10.3389/fgene.2019.01370">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.3389/fgene.2019.01370">Scholia</a></div>
    <div class="csl-entry">Waldrop, M. (2008). Big data: Wikiomics. <i>Nature</i>, <i>455</i>(7209), 22–25. https://doi.org/10.1038/455022a <a href="https://doi.org/10.1038/455022A">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1038/455022A">Scholia</a></div>
    <div class="csl-entry">WikiPathways Debuts. (2008). <i>Science</i>, <i>321</i>(5889), 623–623. https://doi.org/10.1126/science.321.5889.623c <a href="https://doi.org/10.1126/science.321.5889.623c">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1126/science.321.5889.623c">Scholia</a></div>
  </div>
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="wikipathways"/><category term="openscience"/><category term="justdoi:10.1371/journal.pbio.0060184"/><category term="justdoi:10.1126/science.321.5889.623c"/><category term="justdoi:10.12688/wellcomeopenres.18658.1"/><category term="justdoi:10.1073/pnas.2109019118"/><category term="justdoi:10.1093/genetics/iyae185"/><category term="justdoi:10.1038/npre.2010.5361.1"/><category term="justdoi:10.1038/455022A"/><category term="justdoi:10.3389/fgene.2019.01370"/><category term="justdoi:10.1007/978-1-0716-5360-9_3"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/09/09/wikipathways-biological-pathways-across-the-species.html">
      <![CDATA[ I was not there. I only joined the WikiPathways project in late 2011, just as a contributor. And it was just before joining the BiGCaT research team of Prof. Chris Evelo in January 2012, where I started a project in the Open PHACTS project, not really about WikiPathways, but the open science WikiPathways was the main reason for me to join the group. Open PHACTS was close to my research and just created that opportunity. ]]>
    </summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/wp_pws_per_species_thumbnail.png"/>
    <media:content xmlns:media="http://search.yahoo.com/mrss/" medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/wp_pws_per_species_thumbnail.png"/></entry>
  
  <entry>
    <title type="html">Crossref, how do I get old blog post URLs linked to the new DOIs?</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/08/31/crossref-how-do-i-get-old-blog-post-urls-linked-to-the-new-dois.html" rel="alternate" type="text/html" title="Crossref, how do I get old blog post URLs linked to the new DOIs?"/>
    <published>2026-08-31T00:00:00+00:00</published>
    <updated>2026-09-27T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/f33zw-5ry04</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/08/31/crossref-how-do-i-get-old-blog-post-urls-linked-to-the-new-dois.html">
      <![CDATA[ <p>Now that <a href="https://rogue-scholar.org/">Rogue Scholar</a> is getting <a href="https://doi.org/10.53731/zyg15-qv911">serious about citations to blog posts</a>
and <a href="https://chem-bla-ics.linkedchemistry.info/2026/08/23/rogue-scholar-keeps-challenging-the-functionality-of-my-blog.html">how complex this is</a>,
I have been wondering how this works.</p>

<p>I already knew that <a href="https://www.crossref.org/">Crossref</a> tracks citations (see e.g. <a href="https://api.crossref.org/works/10.59787/2413-5488-2025-49-1-83-92">this API call</a>
for a paper where <a href="https://jmol.org/">Jmol</a> is used, doi:<a href="https://doi.org/10.59787/2413-5488-2025-49-1-83-92">10.59787/2413-5488-2025-49-1-83-92</a>),
and I learned that apparently Crossref also does an good job at finding citations when blog post URLs are used instead of the DOIs of the blog posts.</p>

<p>But how does it know? When Rogue Scholar registers a DOI, I assume it passes on the URL to redirect too. But what if the URL changed over time?
For example, I used blogger.com for many years (with satisfaction) and <a href="https://chem-bla-ics.linkedchemistry.info/2023/08/18/last-post-here-freebie-model-online.html">the URLs of the posts have changed</a>!</p>

<p>Crossref, how do I get the old blog post URLs also linked to the DOI?</p>

<p>For example, the doi <a href="https://doi.org/10.59350/65nqr-3w351">10.59350/65nqr-3w351</a> links now to
<a href="https://chem-bla-ics.linkedchemistry.info/2023/08/18/last-post-here-freebie-model-online.html">https://chem-bla-ics.linkedchemistry.info/2023/08/18/last-post-here-freebie-model-online.html</a>
but originally the URL was <a href="https://chem-bla-ics.linkedchemistry.info/2023/08/18/last-post-here-freebie-model-online.html">https://chem-bla-ics.blogspot.com/2023/08/last-post-here-freebie-model-online.html <i class="fa-solid fa-recycle fa-xs"></i></a>.</p>

      
<h4>References</h4>
<div class="csl-bib-body">
    <div class="csl-entry">Akatyev, N. (2025). TEACHING THE FUNDAMENTALS OF MOLECULAR SYMMETRY IN HIGH SCHOOL THROUGH THE USE OF THE INTERACTIVE ONLINE RESOURCE SYMOTTER. <i>National Center for Higher Education Development</i>, <i>49</i>(1). https://doi.org/10.59787/2413-5488-2025-49-1-83-92 <a href="https://doi.org/10.59787/2413-5488-2025-49-1-83-92">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.59787/2413-5488-2025-49-1-83-92">Scholia</a></div>
    <div class="csl-entry">Fenner, M. (2025). Rogue Scholar citation tracking launches to production. In <i>Front Matter</i>. Front Matter. https://doi.org/10.53731/zyg15-qv911 <a href="https://doi.org/10.53731/zyg15-qv911">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.53731/zyg15-qv911">Scholia</a></div>
    <div class="csl-entry">Willighagen, E. (2023). Last post there / the Freebie model online. In <i>Front Matter</i>. Front Matter. https://doi.org/10.59350/65nqr-3w351 <a href="https://doi.org/10.59350/65nqr-3w351">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.59350/65nqr-3w351">Scholia</a></div>
  </div>
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="blog"/><category term="doi"/><category term="justdoi:10.59787/2413-5488-2025-49-1-83-92"/><category term="justdoi:10.53731/zyg15-qv911"/><category term="justdoi:10.59350/65nqr-3w351"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/08/31/crossref-how-do-i-get-old-blog-post-urls-linked-to-the-new-dois.html">
      <![CDATA[ Now that Rogue Scholar is getting serious about citations to blog posts and how complex this is, I have been wondering how this works. ]]>
    </summary></entry>
  
  <entry>
    <title type="html">Rogue Scholar keeps challenging the functionality of my blog</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/08/23/rogue-scholar-keeps-challenging-the-functionality-of-my-blog.html" rel="alternate" type="text/html" title="Rogue Scholar keeps challenging the functionality of my blog"/>
    <published>2026-08-23T00:00:00+00:00</published>
    <updated>2026-08-23T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/ezrsn-psn52</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/08/23/rogue-scholar-keeps-challenging-the-functionality-of-my-blog.html">
      <![CDATA[ <p><a href="https://rogue-scholar.org/">Rogue Scholar</a> continues to offer <a href="https://chem-bla-ics.linkedchemistry.info/2024/07/21/rogue-scholar-and-more.html">awesome features</a>.
It seems the recent move to InvenioRDM (<a href="https://doi.org/10.63517/kshzw-ay335">14.0 was just released</a>) was a good one. It does require rewrites, but make
things more scalable. One thing that did exist in the InvenioRDM-based Rogue Scholar last year was <a href="https://doi.org/10.53731/zyg15-qv911">citations to blog posts</a>.
But even that was <a href="https://doi.org/10.53731/1jbsg-kqm79">redeveloped and relaunched</a> a few days ago. It does not have yet the same amount of citations to
blog posts as before, but <a href="https://rogue-scholar.org/search?q=citations%3A%2A&amp;l=list&amp;p=1&amp;s=10&amp;sort=newest">more than 1200 can be found again</a>.</p>

<p>Platforms are getting more better at precisely capturing how we communicate science. Rogue Scholar is a great example of that, like the
no longer existing <a href="https://chem-bla-ics.linkedchemistry.info/tag/citeulike">CiteULike</a> before. And Rogue Scholar has been challenging
my Markdown-based blog post to support its functionality. For example, I had to <a href="https://chem-bla-ics.linkedchemistry.info/2025/01/19/blog-updates.html">add a JSON Feed</a>,
but also was happy that <a href="https://doi.org/10.53731/1xbh4-mnt50">Rogue Scholar added CiTO Support</a>.</p>

<p>But capturing all citations between things remains an issue. Platforms like Google Scholar and Web of Science do their best, but their
best is not Open or nor FAIR or neither. Generally, it has taken way too long for
<a href="https://doi.org/10.1045/january2015-brase">DataCite</a> and <a href="https://doi.org/10.7717/peerj-cs.86">Software Citations</a> to be picked up.
However, we can <a href="https://chem-bla-ics.linkedchemistry.info/2024/12/30/fair-blog-to-blog-citations.html">take control ourselves</a> when
solutions do not exist.</p>

<p>And because I want journal-to-blog citations are FAIR too, I hacked up another extension of my blog today. I can now add lines like this
to the metadata of blog post:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">cited-in</span><span class="pi">:</span> <span class="s">cito:discusses:10.1186/1471-2105-8-487</span>
</code></pre></div></div>

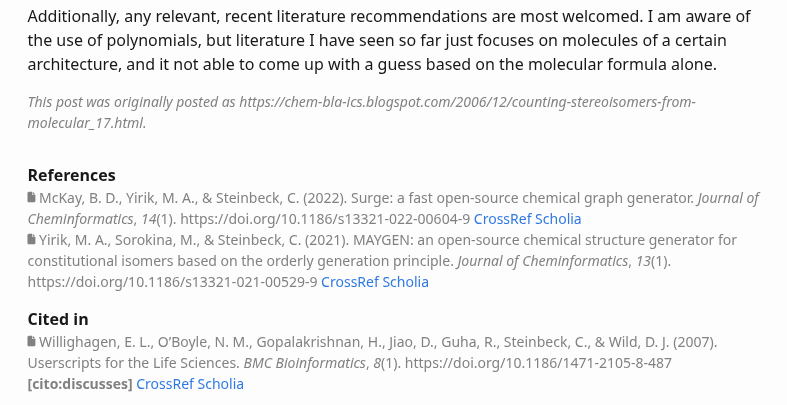
<p>What is encodes is that the article with doi:<a href="https://doi.org/10.1186/1471-2105-8-487">10.1186/1471-2105-8-487</a> (one of my own)
discusses <a href="https://chem-bla-ics.linkedchemistry.info/2006/12/17/counting-stereoisomers-from-molecular_17.html">one of the posts in my blog</a>.</p>

<p>Online, this is rendered with <a href="https://doi.org/10.7717/peerj-cs.214">citation.js</a> like this:</p>

<p><img src="/assets/images/blogs_citedin.png" alt="" /></p>

<p>Here, the <em>References</em> are the things I cite in my blog post, and the <em>Cited in</em> are things citing this blog post.</p>

<h3 id="how-blog-posts-are-cited">How blog posts are cited</h3>

<p>Now, DOIs for blog posts are a new thing: they did not exist when I started blogging. And for the 12 citations I found so far,
they are not using a DOI. I doubt that these citations are easily found in CrossRef or DataCite. Here are two examples, of increasing
complexity. The first one is how many citation styles would do it:</p>

<p><img src="/assets/images/blogs_citing1.png" alt="" /></p>

<p>But they can also look like this:</p>

<p><img src="/assets/images/blogs_citing2.png" alt="" /></p>

<p>And scientific journals sometimes even use URL shorteners and then it may look like this:</p>

<p><img src="/assets/images/blogs_citing3.png" alt="" /></p>

<p>This makes it a challenge for any platform to pick up these citations!</p>

<h3 id="how-about-the-json-feed">How about the JSON Feed</h3>

<p>That leaves me with how I make this information avaiable, a bit towards FAIR, but at least machine readable.
This is done with a <a href="https://egonw.github.io/JSONFeed-extensions/">JSON Feed extension</a> (at the time of writing, I did
not add this proposal yet). My <code class="language-plaintext highlighter-rouge">archive.json</code> feed now contains 12 fragments like this:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nl">"_citations"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
  </span><span class="p">{</span><span class="w">
    </span><span class="nl">"url"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://doi.org/10.1038/nchem.2187"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"doi"</span><span class="p">:</span><span class="w"> </span><span class="s2">"10.1038/nchem.2187"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"cito"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
      </span><span class="s2">"citesForInformation"</span><span class="w">
    </span><span class="p">]</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">]</span><span class="w">
</span></code></pre></div></div>

<p>It matches the structure of the <a href="https://egonw.github.io/JSONFeed-extensions/references.html">_references extension</a>.</p>

<p>Let’s see where this goes :)</p>

      
<h4>References</h4>
<div class="csl-bib-body">
    <div class="csl-entry">Brase, J., Lautenschlager, M., &#38; Sens, I. (2015). The Tenth Anniversary of Assigning DOI Names to Scientific Data and a Five Year History of DataCite. <i>D-Lib Magazine</i>, <i>21</i>(1/2). https://doi.org/10.1045/january2015-brase <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.1045/january2015-brase">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1045/january2015-brase">Scholia</a></div>
    <div class="csl-entry">Fenner, M. (2025). Rogue Scholar citation tracking launches to production. In <i>Front Matter</i>. Front Matter. https://doi.org/10.53731/zyg15-qv911 <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.53731/zyg15-qv911">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.53731/zyg15-qv911">Scholia</a></div>
    <div class="csl-entry">Fenner, M. (2025). Rogue Scholar Newsletter August 2025. In <i>Front Matter</i>. Front Matter. https://doi.org/10.53731/1xbh4-mnt50 <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.53731/1xbh4-mnt50">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.53731/1xbh4-mnt50">Scholia</a></div>
    <div class="csl-entry">Fenner, M. (2026). Rogue Scholar now collects citations with invenio-pidbox. In <i>Front Matter</i>. Front Matter. https://doi.org/10.53731/1jbsg-kqm79 <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.53731/1jbsg-kqm79">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.53731/1jbsg-kqm79">Scholia</a></div>
    <div class="csl-entry">Smith, A. M., Katz, D. S., &#38; Niemeyer, K. E. (2016). Software citation principles. <i>PeerJ Computer Science</i>, <i>2</i>, e86. https://doi.org/10.7717/peerj-cs.86 <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.7717/peerj-cs.86">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.7717/peerj-cs.86">Scholia</a></div>
    <div class="csl-entry">Viger, G. (2026). InvenioRDM v14.0 released. In <i>Front Matter</i>. Front Matter. https://doi.org/10.63517/kshzw-ay335 <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.63517/kshzw-ay335">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.63517/kshzw-ay335">Scholia</a></div>
    <div class="csl-entry">Willighagen, E. L., O’Boyle, N. M., Gopalakrishnan, H., Jiao, D., Guha, R., Steinbeck, C., &#38; Wild, D. J. (2007). Userscripts for the Life Sciences. <i>BMC Bioinformatics</i>, <i>8</i>(1). https://doi.org/10.1186/1471-2105-8-487 <b>[cito:discusses]</b> <a href="https://doi.org/10.1186/1471-2105-8-487">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1186/1471-2105-8-487">Scholia</a></div>
    <div class="csl-entry">Willighagen, L. G. (2019). Citation.js: a format-independent, modular bibliography tool for the browser and command line. <i>PeerJ Computer Science</i>, <i>5</i>, e214. https://doi.org/10.7717/peerj-cs.214 <b>[cito:usesMethodIn]</b> <a href="https://doi.org/10.7717/peerj-cs.214">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.7717/peerj-cs.214">Scholia</a></div>
  </div>
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="cito:citesAsRecommendedReading:10.63517/kshzw-ay335"/><category term="blog"/><category term="cito:citesAsRecommendedReading:10.53731/zyg15-qv911"/><category term="cito"/><category term="cito:citesAsRecommendedReading:10.53731/1jbsg-kqm79"/><category term="cito:citesAsRecommendedReading:10.53731/1xbh4-mnt50"/><category term="mycito:discusses:10.1186/1471-2105-8-487"/><category term="cito:usesMethodIn:10.7717/peerj-cs.214"/><category term="cito:citesAsRecommendedReading:10.7717/peerj-cs.86"/><category term="cito:citesAsRecommendedReading:10.1045/january2015-brase"/><category term="json"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/08/23/rogue-scholar-keeps-challenging-the-functionality-of-my-blog.html">
      <![CDATA[ Rogue Scholar continues to offer awesome features. It seems the recent move to InvenioRDM (14.0 was just released) was a good one. It does require rewrites, but make things more scalable. One thing that did exist in the InvenioRDM-based Rogue Scholar last year was citations to blog posts. But even that was redeveloped and relaunched a few days ago. It does not have yet the same amount of citations to blog posts as before, but more than 1200 can be found again. ]]>
    </summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/blogs_citedin.png"/>
    <media:content xmlns:media="http://search.yahoo.com/mrss/" medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/blogs_citedin.png"/></entry>
  
  <entry>
    <title type="html">Scientias, oudheidkunde, en wetenschap, hoe dan</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/08/07/scientias-oudheidkunde-wetenschap-hoe-dan.html" rel="alternate" type="text/html" title="Scientias, oudheidkunde, en wetenschap, hoe dan"/>
    <published>2026-08-07T00:00:00+00:00</published>
    <updated>2026-08-14T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/jtx6g-4d547</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/08/07/scientias-oudheidkunde-wetenschap-hoe-dan.html">
      <![CDATA[ <p>Communication of science is important to me and it comes in many formats. Educational resources, research articles, text books, popular science magazines, blogs,
TV shows, podcasts, etc (in no particular order). Somewhere during the pandemic, I started listening to podcasts. I had done that, in the early days,
but those early podcasts… well, let’s say, the format had not materialized yet. But also that it can be quite helpful to not play the podcast at the
normal speeds, but at, say 1.25x. Podcasts, like any of the above format have a style, an audience in mind. Maybe the audience is first year students,
peer in the research field, or the general audience. Or a politician that wants to get credibility. There are several podcasts that I have been listening.
Not as education. The may have episode notes, but not proper scientific references. References is one thing important in the communication. Context is another.</p>

<p>I have many books in my house on these aspects of science. From text books, to primary literature, to links to blog posts. It is not my research field,
and (scientific) communication is very much a research field. “It makes sense”, does not do, but the awareness of some of the things should be basic
academic training. Or probably earlier. Every writing has context. Not a random pointer, but a friend has recently written with several others an
interesting chapter on reading scientific literature (doi:<a href="https://doi.org/10.1515/9783110782844-010">10.1515/9783110782844-010</a>,
<a href="https://uplopen.com/reader/chapters/pdf/10.1515/9783110782844-010">pdf</a>).</p>

<h2 id="scientias">Scientias</h2>

<p>And while I started the <a href="https://scientias.nl/nieuws/video/podcast/">Scientias</a> (with (<em>the</em>) <a href="https://mastodon.nl/@Diederikjekel">Diederik Jekel</a> and
<a href="https://mastodon.nl/@krijnsoeteman">Krijn Soeteman</a>) episode to hear more about
the science behind “history”, there were several topics in the [Over oudheidkunde, nepvondsten en AI: wat weten we écht over het verleden?] episode
about the above things, with <a href="https://mastodon.social/@JonaLendering">Jona Lendering</a> as guest.</p>

<p><img src="/assets/images/scientias_episode.png" alt="" /></p>

<p>The things I heard that I got excited about (enough to sit down and write down these thougths) were small comments, other things were
more prominent. One more obvious discussion was that a lot of science news is focusing on new facts, and not the science behind it. Not just
the methods, but also the stack of assumptions, how they were combined,
valued, etc. As Lendering explains how a researcher does that (translated into English by me, with assumptions on the true intention):</p>

<blockquote>
  <p>This is a hypothesis. Now I stack this hypothesis on the previous hypothesis, and I stack another hypothesis on that, and then I stack
a hypothesis on that.</p>
</blockquote>

<p>Most science news outlets find that too complicated (for their audience). To me it feels they think their audience is too stupid to understand
the full story. Now, the Scientias Podcast made it a unique selling point to explain how those facts were derived from experiments, because they
find the full background and experiments behind our knowledge important, exciting. and relevant. I do.</p>

<p>And if I understood Lendering correctly, he too says there actually is plenty of room of that. The full story is more complicated and I cannot
do this justice. There is a growing body of scientific literature that cannot be captured in a single blog post. I will not even try. It will
likely just <a href="https://mainzerbeobachter.com/2017/07/31/mom-het-backfire-effect/">backfire</a>.</p>

<p>And I agree. That is not relevant to them nor their point, but it does explain I was excited about the post. It is always nice to hear like-minded people.
I do not hear this position about scientific communication a lot, but very, very much agree and try to practice.</p>

<h2 id="stacking">Stacking</h2>

<p>Lendering about the book he described in the above quote:</p>

<blockquote>
  <p>I think the conclusions are absolutely wrong, because it stacked too many uncertainties in a row.</p>
</blockquote>

<p>I love this quote. Lendering is talking here about archeology, but it applies to at least chemistry and the life sciences too.
I once wrote a grant application to the Swedisch national research funder VR, their equivalent of the NWO
on that topic (which got rejected, <em>because the candidate has too many international collaborations</em>,
despite scores in the fundable range).</p>

<p>It also very much resonates with the whole topic of LLMs, where exactly that is happening: the stacking of many uncertainties.
The real problem of AI since the 2000s is not the availability of great machine learning methods, but the facts to learn from,
and how well those methods can put those facts in perspective (think Red Riding Hood). That is why my research focus swifted
from chemometrics (the old name for <em>AI in chemistry</em>) and knowledge representation, to knowledge representation and interoperability.</p>

<h2 id="the-science-behind-archeology-and-history">The science behind archeology and history</h2>

<p>Most of the podcast is about archeology and how history is discovered. And the whole podcast does a wonderful job at explaining
how much has changed in the past 30 years. What I learned as a kid about the Romans has been updated in many ways. The the oldest
known documented genocide, in Belgica that started with a Roman military camp on the hill that I can see from my work office, has
peaked my interest in Roman history. But what fascinates me most are not the narratives but the science behind it. The new
chemical and biological approaches giving new evidence that puts archeological evidence in a richer context. Just listen (or
watch) the podcast. And I haven’t read it, but I understood <a href="https://mainzerbeobachter.com/mijn-boeken/oudheidkunde-is-een-wetenschap/">Oudheidkunde is een wetenschap</a>
covers a good bit of it.</p>

<p>Do I think that Nijmegen is the oldest Dutch city, and not Maastricht? Of course, I lived in Nijmegen for a large part of my life.
The competition between the place I studied before and study now is just great amusement. Bring on the popcorn.
And that aquaduct in Nijmegen? I cycled everyday on a Roman dike used for that aquaduct. As a researcher, I really
do not care the exact dates, or what material that aquaduct was made of. How we could learn those things, well,
yeah, the chemistry of physics behind that is cool too. Bring on the nerdy science.</p>

<h2 id="what-science-should-be-like">What science should be like</h2>

<p>Another topic in the above theme is what science should be. Lendering is negative about the research schools and
research institutes (in the Dutch implementation) and explains that different disciplines should communicate and collaborate
more. Since my field is in between two established research fields, I can painfully confirm that many (Dutch) researchers
are much to focused on their own narrow specialism, that they lost context to put that specialism in a wider context.</p>

<blockquote>
  <p>You only start writing a publication, after you collected and looked at all evidence.</p>
</blockquote>

<p>Lendering then talks about how modern science may have deviated too much from this. For people who have been following
the Open Science news, they have seen a good body of scientific literature that show that this indeed is not always
to case (sic). For example, Lendering states:</p>

<blockquote>
  <p>There is no substantial peer review anymore. Really weird publications happen, that should never have been published.</p>
</blockquote>

<p>Really, bold, perhaps, but sadly too close to reality with enough primary literature that has studied these issues
(some of which you can find convered in my blog posts).
Commercial publishers expect a peer review in 10 working days. They value speed over quality. It is there business model.
But also researchers that simply submit the manuscript as-is to the next journal, when the previous journal clearly outlined
limitations. There are reasons why I had to step down as editor from Springer Nature.</p>

<h2 id="calls-for-action">Calls for Action</h2>

<p>Before I write a blog post that takes you more time than to listen to the podcast, there are two more quotes I like to cover:</p>

<blockquote>
  <p>I could not resist the opportunity to mention paywalls. And what has been behind paywalls is not released
as open access. And there are not plans for this.</p>
</blockquote>

<p>Lendering continues with a good example from desinformation on why this must change. Again, I am very excited about
this statement, which I have been arguing for too.</p>

<p>The next quote I shortened a bit, because I want you to listen to the full discussion in the podcast, but here
I do not want to focus on the very convincingly bad urgency of the given example:</p>

<blockquote>
  <p>there is a theory from the 19th century, and that theory has been disproved since then. [..]
But due to digitization projects, old literature is available, with the old disproven theories too.
This is in itself not an issue. However, because the correcting literature from the last 30 years
are hidden behind the paywall, is the disproven theory unchallenged.</p>
</blockquote>

<p>There are many aspects of just this part, and many relate to how knowledge and how we got to knowledge
is spread, reused, etc. Bascially, the FAIR data principles are in that sense just a reformalisation of a much
older and bigger problem. And I think Lendering is spot on with this observation. Translating this to the
bigger issues, the commercial publishers can lecture researchers about FAIR data, but as long as the
with strong determination frustrate scientific progress with paywalls, etc, then we will not make the
progress we deserve and need.</p>

<h3 id="action-1-all-dutch-literature-must-become-green-open-access">Action 1: all Dutch literature must become green Open Access</h3>

<p>While The Netherlands is just a small player, our national effort towards Open Access has made a clear
world wide impact. So has Open Science, and FAIR data, two other (but distinct) movements to improve
knowledge dissemination, and both where The Netherlands has made a significant international contribution.</p>

<p>So, Dutch universities should work harder to make the next step, after CC-BY licensing and the
<a href="https://www.openaccess.nl/nl/beleid/open-access-in-het-nederlandse-auteursrecht-taverne-regeling">Taverne</a>
green Open Access law. Let’s remove that small print of 100% Open Access that says, “but only of new
literature”. Open scientists have been working on this for long enough; it is just policy, laws, and
the mere willingness. Practically, every Dutch university can just tomorrow contact all (emeritus)
professors and make all their literature available under the Taverne rules. Many university libraries
have already started this, but this must have UNL backing with a clear mandate to make 100% of all
Dutch works available, across the full history.</p>

<p>I repeat, this is not a technical question. It is just doing it.</p>

<p>This goes for every Dutch researcher that want to have their research have the impact it can have.
Go to your university library, and send them publisher PDFs of all articles (and book chapters) you
ever published at that university. Yes, you can even email the library where you did your PhD.</p>

<p>Taverne is not the full story. Authors have to give permission, via opt-in or opt-out arrangements
with their universities. That is a problem when the researcher is no longer around. But can
we at least start with all that paywalled literature of which researchers can give that permission,
please, for the <em>full</em> appointments, going back in time? For the rest, well, we have to start
lobbying with our government. That is quite modern and should be trivial.</p>

<p>I think this is essential: you cannot fully understand the impact of an article if you do
not have access to the cited and citing literature because it is behind a paywall.</p>

<h3 id="action-2-make-the-context-of-literature-easier-to-record-and-easier-to-access">Action 2: make the context of literature easier to record and easier to access</h3>

<p>The other point Lendering made is about the self-correcting nature of science (or lack thereof).
The peer review problems were mentioned in the podcast, as well as people not easily finding literature
that disproves earlier literature. It can be a lot simpler to get informed about the status of any
research work. But right now, even something as simple as getting PubPeer and RetractionWatch
information about a References list is non-trivial. The choice of commercial publishers to favor
PDF over (scientific) HTML has been one driven by perverse incentive, not by scientific needs.
Similarly, it is trivial to learn that an article has been disproven, but not simple. University
libraries are not yet equiped correctly or funded appropriately to allow researchers (and the
general local audience who can also enter university libraries to learn stuff).</p>

<p>My gauntlet to Springer Nature about <a href="https://chem-bla-ics.linkedchemistry.info/tag/cito">CiTO citation intent annotations</a>
has yet been underwhelming, despite an in my opinion hopeful and promising pilot. I cannot complain,
and <a href="https://qlever.scholia.wiki/cito/">the interest is there</a>, but it was too difficult for Springer Nature.
And with that we are back with the one of the other main themes of the podcast.</p>

<p>With that, I isolated just a few moments from the podcast. I insist you listen to the full
podcast to get the proper context of the above quotes. If people want to learn more about
the context I see, I invite you to browse my blog (<a href="https://chem-bla-ics.linkedchemistry.info/archive/">newer posts</a>
and <a href="https://chem-bla-ics.blogspot.com/">older posts</a>).</p>

<p>Finally, thank you Krijn, thank you Jona, for this awesome 83 minutes and 16 seconds at 1.25x
speed!</p>

      
<h4>References</h4>
<div class="csl-bib-body">
    <div class="csl-entry">Gonzalez-Marquez, M., Foltz, A., Bye, J. K., Fulsher, A. J., &#38; Wilde, M. (2025). 269What Little Red Riding Hood Can Teach Us about Reading Science. In <i>Narrative and Cognition in Literature and Science</i> (pp. 269–298). De Gruyter. https://doi.org/10.1515/9783110782844-010 <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.1515/9783110782844-010">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1515/9783110782844-010">Scholia</a></div>
  </div>
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="science"/><category term="cito:citesAsRecommendedReading:10.1515/9783110782844-010"/><category term="openscience"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/08/07/scientias-oudheidkunde-wetenschap-hoe-dan.html">
      <![CDATA[ Communication of science is important to me and it comes in many formats. Educational resources, research articles, text books, popular science magazines, blogs, TV shows, podcasts, etc (in no particular order). Somewhere during the pandemic, I started listening to podcasts. I had done that, in the early days, but those early podcasts… well, let’s say, the format had not materialized yet. But also that it can be quite helpful to not play the podcast at the normal speeds, but at, say 1.25x. Podcasts, like any of the above format have a style, an audience in mind. Maybe the audience is first year students, peer in the research field, or the general audience. Or a politician that wants to get credibility. There are several podcasts that I have been listening. Not as education. The may have episode notes, but not proper scientific references. References is one thing important in the communication. Context is another. ]]>
    </summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/scientias_episode.png"/>
    <media:content xmlns:media="http://search.yahoo.com/mrss/" medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/scientias_episode.png"/></entry>
  
  <entry>
    <title type="html">Molecular Inorganics: SMILES, MDL molfile v3000, and InChIs</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/07/26/inorganic-compounds-smiles-mdl-molfile-v3000-and-inchis.html" rel="alternate" type="text/html" title="Molecular Inorganics: SMILES, MDL molfile v3000, and InChIs"/>
    <published>2026-07-26T00:00:00+00:00</published>
    <updated>2026-07-26T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/yhf27-fp921</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/07/26/inorganic-compounds-smiles-mdl-molfile-v3000-and-inchis.html">
      <![CDATA[ <p>Making chemistry more FAIR requires unique identifiers for chemical structures. For organic compounds plenty of solutions exist that
do a great job. Last year and last week, I attended two technical <a href="https://www.inchi-trust.org/">InChI</a> meetings, both with
<a href="https://en.wikipedia.org/wiki/Organometallic_chemistry">organometallic compounds</a> and other molecular inorganics as one of the key topics. Thanks to
<a href="https://bsky.app/profile/herreslab.bsky.social">Sonja</a> (<a href="https://fed.brid.gy/bsky/herreslab.bsky.social">Mastodon bridge</a>)
and <a href="https://www.linkedin.com/in/gerd-blanke-b13115/">Gerd</a> for the invitations. My role includes thinking about what all the
work on the InChI means for the <a href="http://cdk.github.io/">Chemistry Development Kit</a>.</p>

<p>Many things came up. One was testing of new InChI functionality for these organometallic compounds, particularly the stereochemistry.
<a href="https://chem-bla-ics.linkedchemistry.info/2007/08/02/molecules-in-wikipedia.html">Wikipedia has many chemical compounds</a> and could
be a source, but <a href="https://chem-bla-ics.linkedchemistry.info/2022/11/12/wikidata-script-for-smiles-smarts-and.html">so does Wikidata</a>.
Both use the SMILES, but not all SMILES captures all the chemistry we need. And the InChI software needs
<a href="https://en.wikipedia.org/wiki/Chemical_table_file#V3000">an V3000 MDL Molfile</a>. Thanks to John and other CDK developers, there
is good support for recent cheminformatics software, but I was not sure it had what I would need.</p>

<p>This post is the first of a few related posts. This post is about converting SMILES from <a href="https://wikidata.org/">Wikidata</a>
to V3000 files. Take <a href="https://qlever.scholia.wiki/chemical/Q412415">cisplatin</a>: it has four ligands around a platinum atom,
all in a single plane:</p>

<p><img src="/assets/images/cisplatin.png" alt="" /></p>

<p>In this image, in red, is actually an annotation of how the ligands are oriented around the platinum. This is also reflected
in the <em>isomeric SMILES</em> in Wikidata: <code class="language-plaintext highlighter-rouge">Cl[Pt@SP1]([NH3])([NH3])Cl</code>.</p>

<p>The following source code is written in <a href="https://chem-bla-ics.linkedchemistry.info/tag/groovy">Groovy</a> which I have used for many
years because it is less verbose than Java. First, we set up our helper classes:</p>

<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nd">@Grab</span><span class="o">(</span><span class="n">group</span><span class="o">=</span><span class="s1">'org.openscience.cdk'</span><span class="o">,</span> <span class="n">module</span><span class="o">=</span><span class="s1">'cdk-smiles'</span><span class="o">,</span> <span class="n">version</span><span class="o">=</span><span class="s1">'2.12'</span><span class="o">)</span>
<span class="nd">@Grab</span><span class="o">(</span><span class="n">group</span><span class="o">=</span><span class="s1">'org.openscience.cdk'</span><span class="o">,</span> <span class="n">module</span><span class="o">=</span><span class="s1">'cdk-silent'</span><span class="o">,</span> <span class="n">version</span><span class="o">=</span><span class="s1">'2.12'</span><span class="o">)</span>
<span class="nd">@Grab</span><span class="o">(</span><span class="n">group</span><span class="o">=</span><span class="s1">'org.openscience.cdk'</span><span class="o">,</span> <span class="n">module</span><span class="o">=</span><span class="s1">'cdk-ctab'</span><span class="o">,</span> <span class="n">version</span><span class="o">=</span><span class="s1">'2.12'</span><span class="o">)</span>
<span class="nd">@Grab</span><span class="o">(</span><span class="n">group</span><span class="o">=</span><span class="s1">'org.openscience.cdk'</span><span class="o">,</span> <span class="n">module</span><span class="o">=</span><span class="s1">'cdk-sdg'</span><span class="o">,</span> <span class="n">version</span><span class="o">=</span><span class="s1">'2.12'</span><span class="o">)</span>

<span class="kn">import</span> <span class="nn">org.openscience.cdk.smiles.SmilesParser</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">org.openscience.cdk.silent.SilentChemObjectBuilder</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">org.openscience.cdk.io.SDFWriter</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">org.openscience.cdk.layout.StructureDiagramGenerator</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">javax.vecmath.Vector2d</span>

<span class="n">builder</span> <span class="o">=</span> <span class="n">SilentChemObjectBuilder</span><span class="o">.</span><span class="na">getInstance</span><span class="o">()</span>
<span class="n">sp</span> <span class="o">=</span> <span class="k">new</span> <span class="n">SmilesParser</span><span class="o">(</span><span class="n">builder</span><span class="o">)</span>
<span class="n">sdg</span> <span class="o">=</span> <span class="k">new</span> <span class="n">StructureDiagramGenerator</span><span class="o">();</span>
</code></pre></div></div>

<p>With some extra code, I can actually get many compounds from Wikidata to convert to v3000 with a SAPRQL (as I have done
last year with CXSMILES and polymers, unpublished), but let’s go with a single example:</p>

<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">smiles</span> <span class="o">=</span> <span class="s2">"Cl[Pt@SP1]([NH3])([NH3])Cl"</span>
<span class="n">label</span> <span class="o">=</span> <span class="s2">"cisplatin"</span>
<span class="n">wdItem</span> <span class="o">=</span> <span class="s2">"Q412415"</span>
</code></pre></div></div>

<p>I can parse the SMILES and generated 2D coordinates with (which is also the approach by <a href="https://www.simolecule.com/cdkdepict/depict/bow/svg?smi=Cl%5BPt%40SP1%5D(%5BNH3%5D)(%5BNH3%5D)Cl&amp;zoom=2.0&amp;annotate=cip">CDK Depict</a>
which I used for the above 2D diagram of cisplatin):</p>

<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">mol</span> <span class="o">=</span> <span class="n">sp</span><span class="o">.</span><span class="na">parseSmiles</span><span class="o">(</span><span class="n">smiles</span><span class="o">)</span>
<span class="n">sdg</span><span class="o">.</span><span class="na">setMolecule</span><span class="o">(</span><span class="n">mol</span><span class="o">);</span>
<span class="n">sdg</span><span class="o">.</span><span class="na">generateCoordinates</span><span class="o">(</span><span class="k">new</span> <span class="n">Vector2d</span><span class="o">(</span><span class="mi">0</span><span class="o">,</span> <span class="mi">1</span><span class="o">));</span>
<span class="n">mol</span> <span class="o">=</span> <span class="n">sdg</span><span class="o">.</span><span class="na">getMolecule</span><span class="o">();</span>
</code></pre></div></div>

<p>If you have more than one molfile, they can be combined into a <a href="https://en.wikipedia.org/wiki/Chemical_table_file#SDF">SD file</a>,
to which additional properties can be added:</p>

<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">mol</span><span class="o">.</span><span class="na">setTitle</span><span class="o">(</span><span class="n">label</span><span class="o">)</span>
<span class="n">mol</span><span class="o">.</span><span class="na">setProperty</span><span class="o">(</span><span class="s2">"PUBCHEM_SUBSTANCE_SYNONYM"</span><span class="o">,</span> <span class="n">label</span><span class="o">)</span>
<span class="n">mol</span><span class="o">.</span><span class="na">setProperty</span><span class="o">(</span><span class="s2">"PUBCHEM_SUBSTANCE_COMMENT"</span><span class="o">,</span> <span class="n">smiles</span><span class="o">)</span>
<span class="n">mol</span><span class="o">.</span><span class="na">setProperty</span><span class="o">(</span><span class="s2">"PUBCHEM_EXT_DATASOURCE_REGID"</span><span class="o">,</span> <span class="n">wdItem</span><span class="o">)</span>
<span class="n">mol</span><span class="o">.</span><span class="na">setProperty</span><span class="o">(</span><span class="s2">"PUBCHEM_EXT_SUBSTANCE_URL"</span><span class="o">,</span> <span class="s2">"https://qlever.scholia.wiki/"</span> <span class="o">+</span> <span class="n">wdItem</span><span class="o">)</span>
</code></pre></div></div>

<p>And then generate the actual SD file with:</p>

<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">writer</span> <span class="o">=</span> <span class="k">new</span> <span class="n">FileWriter</span><span class="o">(</span><span class="k">new</span> <span class="n">File</span><span class="o">(</span><span class="s2">"demo.sdf"</span><span class="o">))</span>
<span class="n">SDFWriter</span> <span class="n">sdfWriter</span> <span class="o">=</span> <span class="k">new</span> <span class="n">SDFWriter</span><span class="o">(</span><span class="n">writer</span><span class="o">);</span>
<span class="n">sdfWriter</span><span class="o">.</span><span class="na">getSetting</span><span class="o">(</span><span class="n">SDFWriter</span><span class="o">.</span><span class="na">OptAlwaysV3000</span><span class="o">).</span><span class="na">setSetting</span><span class="o">(</span><span class="s2">"true"</span><span class="o">);</span>
<span class="n">sdfWriter</span><span class="o">.</span><span class="na">write</span><span class="o">(</span><span class="n">mol</span><span class="o">);</span>
<span class="n">sdfWriter</span><span class="o">.</span><span class="na">close</span><span class="o">();</span>
<span class="n">writer</span><span class="o">.</span><span class="na">close</span><span class="o">();</span>
</code></pre></div></div>

<p>We then get this v3000 file:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>cisplatin
  CDK     07262618042D

  0  0  0     0  0            999 V3000
M  V30 BEGIN CTAB
M  V30 COUNTS 5 4 0 0 0
M  V30 BEGIN ATOM
M  V30 1 Cl -1.29904 2.25 0 0
M  V30 2 Pt 0 1.5 0 0
M  V30 3 N 1.29904 2.25 0 0 VAL=4
M  V30 4 N 1.29904 0.75 0 0 VAL=4
M  V30 5 Cl -1.29904 0.75 0 0
M  V30 END ATOM
M  V30 BEGIN BOND
M  V30 1 1 2 1 CFG=3
M  V30 2 1 2 3 CFG=3
M  V30 3 1 2 4 CFG=1
M  V30 4 1 2 5 CFG=1
M  V30 END BOND
M  V30 END CTAB
M  END
&gt; &lt;PUBCHEM_SUBSTANCE_COMMENT&gt;
Cl[Pt@SP1]([NH3])([NH3])Cl

&gt; &lt;PUBCHEM_EXT_DATASOURCE_REGID&gt;
Q412415

&gt; &lt;PUBCHEM_SUBSTANCE_SYNONYM&gt;
cisplatin

&gt; &lt;PUBCHEM_EXT_SUBSTANCE_URL&gt;
https://qlever.scholia.wiki/Q412415

$$$$
</code></pre></div></div>

<p>I can copy/paste the resulting v3000 content to the <a href="https://iupac-inchi.github.io/InChI-Web-Demo/">InChI Web Demo</a> to calculate the
Standard InChI:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>InChI=1S/2ClH.2H3N.Pt/h2*1H;2*1H3;/q;;;;+2/p-2
</code></pre></div></div>

<p>And this is what the two technical meetings I attended were about: <em>molecular inorganics</em>. The above InChI does not feel right,
and certainly lost the connectivity of the ligands with the platinum. However, if we add the beta option <code class="language-plaintext highlighter-rouge">-MolecularInorganics</code>,
then we get this InChI (where the <code class="language-plaintext highlighter-rouge">B</code> in <code class="language-plaintext highlighter-rouge">InChI=1B</code> reflects the beta state of this feature):</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>InChI=1B/Cl2H6N2Pt/c1-5(2,3)4/h3-4H3
</code></pre></div></div>

<p>However, this beta version does not distinguish cisplatin from <a href="https://qlever.scholia.wiki/chemical/Q25403157">transplatin</a>. For that,
we need to dive into how to represent the stereochemistry of these inorganics first.</p>

      
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="chemistry"/><category term="inchi"/><category term="wikidata"/><category term="smiles"/><category term="pubchem"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/07/26/inorganic-compounds-smiles-mdl-molfile-v3000-and-inchis.html">
      <![CDATA[ Making chemistry more FAIR requires unique identifiers for chemical structures. For organic compounds plenty of solutions exist that do a great job. Last year and last week, I attended two technical InChI meetings, both with organometallic compounds and other molecular inorganics as one of the key topics. Thanks to Sonja (Mastodon bridge) and Gerd for the invitations. My role includes thinking about what all the work on the InChI means for the Chemistry Development Kit. ]]>
    </summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/cisplatin.png"/>
    <media:content xmlns:media="http://search.yahoo.com/mrss/" medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/cisplatin.png"/></entry>
  
  <entry>
    <title type="html">Carbon beats gold: Diamond Open Access is the future #2</title>
    <link href="https://chem-bla-ics.linkedchemistry.info/2026/07/13/carbon-beats-gold-diamond-open-access-is-the-future2.html" rel="alternate" type="text/html" title="Carbon beats gold: Diamond Open Access is the future #2"/>
    <published>2026-07-13T00:00:00+00:00</published>
    <updated>2026-07-13T00:00:00+00:00</updated>
    <id>https://doi.org/10.59350/gfrxs-bxn43</id>
    <content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/07/13/carbon-beats-gold-diamond-open-access-is-the-future2.html">
      <![CDATA[ <p>We need a lot more than <a href="https://chem-bla-ics.linkedchemistry.info/2026/07/13/carbon-beats-gold-diamond-open-access-is-the-future.html">diamond open access</a>
to really improve the publishing models. That said, but there are <a href="https://chem-bla-ics.linkedchemistry.info/2024/09/16/publishing.html">examples that</a>
<a href="https://chem-bla-ics.linkedchemistry.info/2025/02/13/beiltein-journal-has-bioschemas.html">diamond open access publishers</a> actually want to
improve more just the access to the knowledge dissemination infrastructure.
But infrastructure is not only technologies; it also includes the many social aspects that are involved in adoption.
And we saw <a href="https://chem-bla-ics.linkedchemistry.info/2026/07/13/carbon-beats-gold-diamond-open-access-is-the-future.html">enough of that in the open access transition</a>.</p>

<p>One aspect that limits the uptake of diamond open access models is that the scholarly community needs to change
their trust model. We have seen a transition from societal publishers to commercial publishers, from scholarly-led
to publisher-led. And commercial publishers certainly <a href="https://chem-bla-ics.linkedchemistry.info/2021/06/11/conflict-of-interest-or-why-i-am.html">breached my trust</a>
(see also doi:<a href="http://doi.org/10.5281/ZENODO.4926030">10.5281/zenodo.4926030</a>).</p>

<p>Many scholars prefer the certainty of a scholarly journal where they can trust that the editorial board and
their reviewers take their job seriously. This matters. The notion that peer reviewers may reject your work is an
extrinsic motivation for at least some researchers to do a better job (personal communication). And that feature
works well: there are indications that research published as preprint sees limited change after the formal
peer review process (doi:<a href="https://doi.org/10.1038/d41586-026-02167-3">10.1038/d41586-026-02167-3</a> and
doi:<a href="https://doi.org/10.64898/2026.06.30.735556">10.64898/2026.06.30.735556</a>):</p>

<blockquote>
  <p>“For most scientists, reputation is important, and they would not upload something they would not be comfortable
with publishing in a journal later.”</p>
</blockquote>

<p>In an ideal situation, reputation would not be part of the whole equation: researchers never submit anything they think
is not scientifically sound. Journals would never desk-reject an article that is scientifically sound. The question
is mostly how to reach that. Everyone is busy, and it has not been so long ago that the journal impact factor was
by many as indicator of scientific quality. The reality is far more complex than that.</p>

<h2 id="finding-diamond-open-access-journals">Finding Diamond Open Access journals</h2>

<p>So, let’s assume you are interested in the idea, and want to know what diamond open access journals exist in your
research field, before you can even consider the quality of that journal, you need to know which journal is diamond
open access. Therefore, I <a href="https://mastodon.social/@egonw/116906626546588093">asked yesterday on Mastodon</a> about databases that list
which journal are diamond.</p>

<p>It actually turns out that the <a href="https://doaj.org/">Directory of Open Access Journals</a> (DOAJ) does not indicate
if a journal is diamond. You can filter on zero APC, but that is not the same. In fact, zero APC is routinely used
by big publishers to launch new journals. One they have critical mass, they will start charging non-zero APCs.</p>

<p>I already received some replies about possible options:</p>

<ol>
  <li><a href="https://ddh.edch.eu/en">Diamond Discovery Hub</a>: lists just over 4,000 diamond journals, but seems closed data (thx <a href="https://bsky.app/profile/najko.bsky.social/post/3mqh25otvvk2z">Najko</a>! see also doi:<a href="https://doi.org/10.15291/libellarium.4569">10.15291/libellarium.4569</a>)</li>
  <li><a href="https://wheretopublish.github.io/">wheretopublish.github.io</a>: open data, accepts additions, but lists only 9 diamond journals (thx <a href="https://bsky.app/profile/annecmg.bsky.social/post/3mqj4envqns24">Anne</a>!)</li>
  <li><a href="https://service.tib.eu/bison/">B!SON</a>: a recommender that depends on DOAJ, so also without clear diamond indication (thx <a href="https://degrowth.social/@yala/116906904947384383">Jon</a>!)</li>
</ol>

<p>All pieces of the puzzle.</p>

<p>When I grew up as a scholar, I learned to publish in journals where you respect the research, where you see important
research in your field get published. Nowadays, this is changing. In fact, young researchers (tho many older scholars alike)
fear to publish in predatory journal by accident (really! <code class="language-plaintext highlighter-rouge">[citation_pending]</code>). The big publishers and the new
publishers have been adding so many new journals, and academia has really pushed the “publish as many articles
as you can” model, that it kind of makes sense why things are different now.</p>

<p>And, a central database with trustworthy information about the quality of diamond open access journals
is just needed.</p>

<p>A final note, while I have not been able to create a list of diamond open access journals with OpenAlex,
already in February 2025 I found a way to list <a href="https://edu.nl/q3uf3">articles tagged with a <em>diamond status</em></a>.
This query lists over three thousand of such annoated articles for Maastricht University:</p>

<p><img src="/assets/images/openalex_diamondOA_UM_articles.png" alt="" /></p>

<p>(Interestingly, the journal where the three most cited articles were published turned diamond already in 2004
and was discontinued about half a year go “Due to recent changes in operational resources”,
<a href="https://en.wikipedia.org/wiki/Environmental_Health_Perspectives">according to Wikipedia</a>.)</p>

<h2 id="building-trust">Building trust</h2>

<p>So, while the above solution do allow you to increase your success rate or finding a diamond open access journal
in your field, the next question is: what can you learn about this journal. For example, what does Wikipedia
say about the journal (if anything)? Do you know people that have published in that journal? The OpenAlex
screenshot shows</p>

<p>That make me wonder what <a href="https://www.wikidata.org/">Wikidata</a> has to offer. After all, as one of the largest
linked open data sources, they must have some information.</p>

<p>I am not disappointed. The <em>type</em> <a href="https://www.wikidata.org/wiki/Q108440863">diamond open-access journal</a> is actively
used, and there is plenty of other of useful fields for these journals. I came up with
<a href="https://edu.nl/xh7h9">this SPARQL query</a> (with some QLever sugar for labels):</p>

<div class="language-sparql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">PREFIX</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="w"> </span><span class="nn">&lt;http://www.wikidata.org/prop/direct/&gt;</span><span class="w">
</span><span class="k">PREFIX</span><span class="w"> </span><span class="nn">wd</span><span class="o">:</span><span class="w"> </span><span class="nn">&lt;http://www.wikidata.org/entity/&gt;</span><span class="w">
</span><span class="k">PREFIX</span><span class="w"> </span><span class="nn">rdfs</span><span class="o">:</span><span class="w"> </span><span class="nn">&lt;http://www.w3.org/2000/01/rdf-schema#&gt;</span><span class="w">
</span><span class="k">SELECT</span><span class="w"> </span><span class="k">DISTINCT</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nv">?diamondjournalLabel</span><span class="w">
      </span><span class="c1"># (SAMPLE(?url_) AS ?website)</span><span class="w">
      </span><span class="p">(</span><span class="nb">SAMPLE</span><span class="p">(</span><span class="nv">?issnl_</span><span class="p">)</span><span class="w"> </span><span class="k">AS</span><span class="w"> </span><span class="nv">?issnl</span><span class="p">)</span><span class="w">
      </span><span class="p">(</span><span class="nb">GROUP_CONCAT</span><span class="p">(</span><span class="k">DISTINCT</span><span class="w"> </span><span class="nb">STR</span><span class="p">(</span><span class="nv">?issn_</span><span class="p">))</span><span class="w"> </span><span class="k">AS</span><span class="w"> </span><span class="nv">?issn</span><span class="p">)</span><span class="w">
      </span><span class="p">(</span><span class="nb">SAMPLE</span><span class="p">(</span><span class="nv">?lang_</span><span class="p">)</span><span class="w"> </span><span class="k">AS</span><span class="w"> </span><span class="nv">?language</span><span class="p">)</span><span class="w">
      </span><span class="p">(</span><span class="nb">SAMPLE</span><span class="p">(</span><span class="nv">?doaj_</span><span class="p">)</span><span class="w"> </span><span class="k">AS</span><span class="w"> </span><span class="nv">?doaj</span><span class="p">)</span><span class="w">
      </span><span class="p">(</span><span class="nb">GROUP_CONCAT</span><span class="p">(</span><span class="k">DISTINCT</span><span class="w"> </span><span class="nb">STR</span><span class="p">(</span><span class="nv">?subject</span><span class="p">);</span><span class="nb">separator</span><span class="p">=</span><span class="s2">", "</span><span class="p">)</span><span class="w"> </span><span class="k">AS</span><span class="w"> </span><span class="nv">?subjects</span><span class="p">)</span><span class="w">
</span><span class="k">WHERE</span><span class="w"> </span><span class="p">{</span><span class="w">
  </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="ss">P31</span><span class="w"> </span><span class="nn">wd</span><span class="o">:</span><span class="ss">Q108440863</span><span class="w"> </span><span class="p">.</span><span class="w">
  </span><span class="k">OPTIONAL</span><span class="w"> </span><span class="p">{</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="ss">P236</span><span class="w"> </span><span class="nv">?issn_</span><span class="w"> </span><span class="p">}</span><span class="w">
  </span><span class="k">OPTIONAL</span><span class="w"> </span><span class="p">{</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="ss">P7363</span><span class="w"> </span><span class="nv">?issnl_</span><span class="w"> </span><span class="p">}</span><span class="w">
  </span><span class="k">OPTIONAL</span><span class="w"> </span><span class="p">{</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="ss">P856</span><span class="w"> </span><span class="nv">?url_</span><span class="w"> </span><span class="p">}</span><span class="w">
  </span><span class="k">OPTIONAL</span><span class="w"> </span><span class="p">{</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="ss">P407</span><span class="w"> </span><span class="o">/</span><span class="w"> </span><span class="err">@en@</span><span class="nn">rdfs</span><span class="o">:</span><span class="ss">label</span><span class="w"> </span><span class="nv">?lang_</span><span class="w"> </span><span class="p">}</span><span class="w">
  </span><span class="k">OPTIONAL</span><span class="w"> </span><span class="p">{</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="ss">P5115</span><span class="w"> </span><span class="nv">?doaj_</span><span class="w"> </span><span class="p">}</span><span class="w">
  </span><span class="k">OPTIONAL</span><span class="w"> </span><span class="p">{</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nn">wdt</span><span class="o">:</span><span class="ss">P921</span><span class="w"> </span><span class="o">/</span><span class="w"> </span><span class="err">@en@</span><span class="nn">rdfs</span><span class="o">:</span><span class="ss">label</span><span class="w"> </span><span class="nv">?subject</span><span class="w"> </span><span class="p">}</span><span class="w">
  </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="err">@en@</span><span class="nn">rdfs</span><span class="o">:</span><span class="ss">label</span><span class="w"> </span><span class="nv">?diamondjournalLabel</span><span class="w"> </span><span class="p">.</span><span class="w">
</span><span class="p">}</span><span class="w"> </span><span class="k">GROUP</span><span class="w"> </span><span class="k">BY</span><span class="w"> </span><span class="nv">?diamondJournal</span><span class="w"> </span><span class="nv">?diamondjournalLabel</span><span class="w">
</span></code></pre></div></div>

<p>This lists more than 1,500 diamond open access journals:</p>

<p><img src="/assets/images/wikidata_diamondOA_journals.png" alt="" /></p>

<p>With Wikidata we can then <a href="https://edu.nl/ekbq9">list UM authors that published in diamond journals</a>.
That list is remarkably short, however, if you compare it with the earlier results from OpenAlex. That is because
Wikidata only contains a subset of scientific literature and not all articles are correctly linked to the items
about their authors. But I also spotted journals in the OpenAlex list that are not really diamond.</p>

<h2 id="what-is-next">What is next?</h2>

<p>Clearly, we need better metadata, but things are not looking that bad either! We have something to work with.
What is your favorite diamond open access journal?</p>

      
<h4>References</h4>
<div class="csl-bib-body">
    <div class="csl-entry">Arasteh-Roodsary, S., Bargheer, M., &#38; Rooryck, J. (2026). The Diamond Discovery Hub criteria for diamond open access journals. <i>Libellarium: Časopis Za Istraživanja u Području Informacijskih i Srodnih Znanosti</i>, <i>16</i>(1), 27–38. https://doi.org/10.15291/libellarium.4569 <b>[cito:citesForInformation]</b> <a href="https://doi.org/10.15291/libellarium.4569">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.15291/libellarium.4569">Scholia</a></div>
    <div class="csl-entry">Basu, M. (2026). Think preprints are unreliable? Analysis of 70,000 studies might change your mind. <i>Nature</i>. https://doi.org/10.1038/d41586-026-02167-3 <b>[cito:includesQuotationFrom]</b> <a href="https://doi.org/10.1038/d41586-026-02167-3">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.1038/d41586-026-02167-3">Scholia</a></div>
    <div class="csl-entry">Willighagen, E. (2021). <i>Conflict of Interest. Or why I am stepping down as Editor-in-Chief of the Journal of Cheminformatics.</i> Zenodo. https://doi.org/10.5281/ZENODO.4926030 <b>[cito:citesAsRecommendedReading]</b> <a href="https://doi.org/10.5281/ZENODO.4926030">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.5281/ZENODO.4926030">Scholia</a></div>
    <div class="csl-entry">Yin, H., Ahn, W., Forster, P. M., &#38; Rust, R. (2026). Tracking claim changes from preprint to publication across 72,644 biomedical studies using large language models. In <i>bioRxiv</i>. openRxiv. https://doi.org/10.64898/2026.06.30.735556 <b>[cito:citesAsDatasource]</b> <a href="https://doi.org/10.64898/2026.06.30.735556">CrossRef</a> <a href="https://qlever.scholia.wiki/doi/10.64898/2026.06.30.735556">Scholia</a></div>
  </div>
      ]]>
    </content>
    
    
      <author><name>Egon Willighagen</name><uri>https://orcid.org/0000-0001-7542-0286</uri></author>
    
    <category term="openaccess"/><category term="mycito:citesAsRecommendedReading:10.5281/ZENODO.4926030"/><category term="cito:includesQuotationFrom:10.1038/d41586-026-02167-3"/><category term="cito:citesAsDatasource:10.64898/2026.06.30.735556"/><category term="cito:citesForInformation:10.15291/libellarium.4569"/>
    
    <summary type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/07/13/carbon-beats-gold-diamond-open-access-is-the-future2.html">
      <![CDATA[ We need a lot more than diamond open access to really improve the publishing models. That said, but there are examples that diamond open access publishers actually want to improve more just the access to the knowledge dissemination infrastructure. But infrastructure is not only technologies; it also includes the many social aspects that are involved in adoption. And we saw enough of that in the open access transition. ]]>
    </summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/wikidata_diamondOA_journals.png"/>
    <media:content xmlns:media="http://search.yahoo.com/mrss/" medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/wikidata_diamondOA_journals.png"/></entry>
  
</feed>