<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.3.4">Jekyll</generator><link href="https://chem-bla-ics.linkedchemistry.info/feed/by_tag/nmrshiftdb.xml" rel="self" type="application/atom+xml" /><link href="https://chem-bla-ics.linkedchemistry.info/" rel="alternate" type="text/html" /><updated>2026-08-31T19:33:33+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/feed/by_tag/nmrshiftdb.xml</id><title type="html">chem-bla-ics</title><subtitle>Chemblaics (pronounced chem-bla-ics) is the science that uses open science and computers to solve problems in chemistry, biochemistry and related fields.</subtitle><author><name>Egon Willighagen</name></author><entry><title type="html">Curation is an essential part of doing research</title><link href="https://chem-bla-ics.linkedchemistry.info/2025/06/29/curation-is-an-essential-part-of-doing-research.html" rel="alternate" type="text/html" title="Curation is an essential part of doing research" /><published>2025-06-29T00:00:00+00:00</published><updated>2025-06-29T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2025/06/29/curation-is-an-essential-part-of-doing-research</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2025/06/29/curation-is-an-essential-part-of-doing-research.html"><![CDATA[<p>Depending on your exact definition of doing science, keeping track as precise as possible of your observations
is an essential part of doing science. The precision should be high enough that mistakes are obvious. This pattern is,
of course, not limited to doing science and we see this in open source development too. Unfortunately, in the
modern way of doing science, this is not getting the attention it should get. Worse, with narratives (stories)
about the research, in the form of journal articles, are generally considered more important that a precise
description of the observations.</p>

<p>Is that a big issue? Hell, yes. Where do you think the FAIR ideas came from? And why FAIR in ten years has not
brought about the change it was hoping for?</p>

<p>For me, my fascination for curation started as a student, around 1995, with the <em>Dictionary on Organic Chemistry</em>.
At that time, my interest came from wanting to learn about chemistry and biology. During my M.Sc. and PhD, it was
obvious how essential it was to derivating correct scientific conclusions from your experiment. Data, knowledge,
and software alike, imo. And because curation is expensive, not having to repeat it, I prefer to do it as
Open Science.</p>

<h2 id="curation">Curation</h2>

<p>Of course, curation has been part of doing science, but to a large extens is separate step from doing science.
It is done by database developers, librarians, and chemo- and bioinformaticians. For example, Chemical Abstracts
Service (CAS) <a href="https://en.wikipedia.org/wiki/Chemical_Abstracts_Service">started over 100 years ago</a> and started
indexing chemical structures in 1965. The curation is an ongoing process, <a href="https://chem-bla-ics.linkedchemistry.info/2022/05/22/new-cas-common-chemistry-in-2021.html">also for old records</a>.</p>

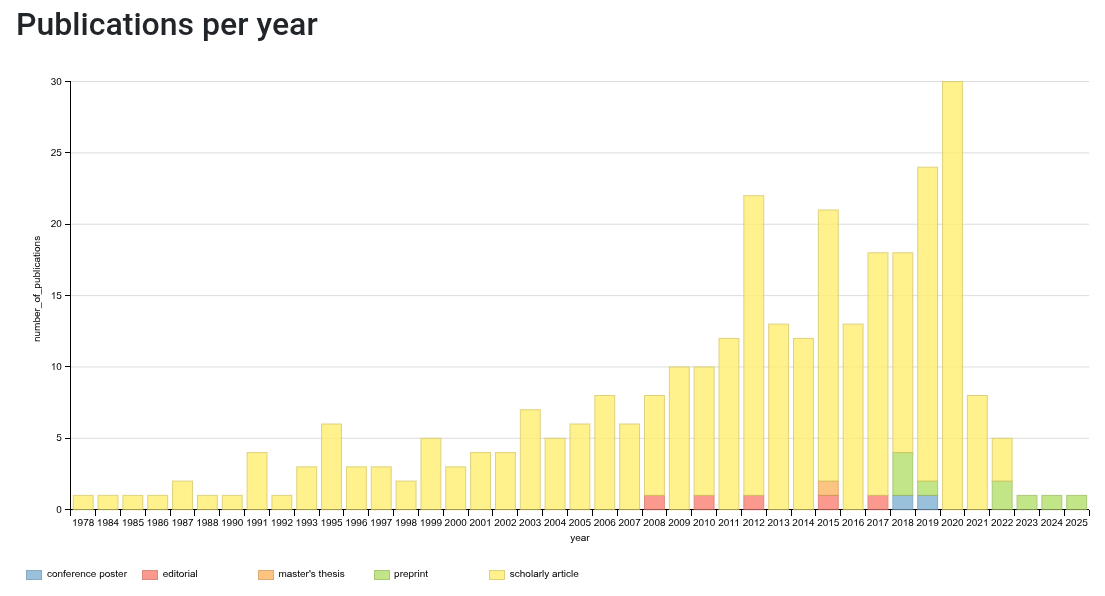
<p><a href="https://www.biocuration.org/dissemination/who-are-we/">Biocuration</a> is getting
<a href="https://scholia.toolforge.org/topic/Q54987878#publications-per-year">more and more attention</a>:</p>

<p><img src="/assets/images/biocuration.png" alt="" /></p>

<p>The recognition and rewarding by having the <a href="https://www.biocuration.org/">International Society for Biocuration</a>
(ISB, <a href="https://scholia.toolforge.org/organization/Q23809291">Scholia page</a>) should not be underestimated
(doi:<a href="https://doi.org/10.1038/455047A">10.1038/455047A</a>). Their <a href="https://scholia.toolforge.org/event-series/Q106486148">Annual International Biocuration Conferences</a>
have been running since <a href="https://scholia.toolforge.org/event/Q109408101">2005</a>. And with their
awards, they give the biocuration work recognition and, literally, rewarding:</p>

<ul>
  <li><a href="https://scholia.toolforge.org/award/Q106045191">Biocuration Career Award</a> (2016-2021)</li>
  <li><a href="https://scholia.toolforge.org/award/Q118947746">Excellence in Biocuration Early Career Award</a> (2022-)</li>
  <li><a href="https://scholia.toolforge.org/award/Q119882229">Excellence in Biocuration Advanced Career Award</a> (2022-)</li>
  <li><a href="https://scholia.toolforge.org/award/Q106045103">Exceptional Contribution to Biocuration Award</a> (2017-)</li>
</ul>

<h2 id="my-curation-curriculum-vitae">My curation Curriculum Vitae</h2>

<p>I don’t have a good <em>curation CV</em>. For a large extend because the curation has been part of a study. The curation
itself does not get recognized, and only the <em>journal article</em> does. With datasets slowly getting more recognition,
so does data curation, but data curation is not really part of how we do FAIR at this moment, and via this route
not getting the attention it gets.</p>

<p>But since I have been updating <a href="https://egonw.github.io/cv/">my CV anyway</a>, I dug up some curation I am proud
of:</p>

<ul>
  <li>the Dictionary on Organic Chemistry, which no longer exists, but it started my Open Science chemistry research</li>
  <li>the <a href="Blue Obelisk Data Repository">Blue Obelisk Data Repositry</a> (BODR), which has been part of various
GNU/Linux distributions (see also doi:<a href="https://doi.org/10.1021/ci050400b">10.1021/ci050400b</a>).
A new version is <a href="https://chem-bla-ics.blogspot.com/2013/08/the-blue-obelisk-data-repositorys-10.html">long overdue</a></li>
  <li>I contributed hundreds of NMR spectra with uncommon nuclei to <a href="https://sourceforge.net/projects/nmrshiftdb2/files/data/">NMRShiftDb</a></li>
  <li>Wikidata, see <a href="https://chem-bla-ics.linkedchemistry.info/2025/05/25/new-preprint-scholia-chemistry-access-to-chemistry-in-wikidata.html">this preprint</a>,
but also many small projects, like adding CXSMILES for polymers, and <a href="https://laurendupuis.github.io/Scholia_tutorial/">main subject annotation in Scholia</a></li>
  <li>WikiPathways (see <a href="https://chem-bla-ics.linkedchemistry.info/tag/wikipathways">these blog posts</a>), where I started
<a href="https://classic.wikipathways.org/index.php?title=Special:Contributions&amp;dir=prev&amp;target=Egonw&amp;month=&amp;year=">curating metabolites in 2012</a>,
set up <a href="https://chem-bla-ics.linkedchemistry.info/2018/10/11/two-presentations-at-wikipathways-2018.html">a computer-assistent curation platform</a>
<a href="https://chem-bla-ics.linkedchemistry.info/2016/07/02/two-apache-jena-sparql-query.html">using SPARQL</a>, and
were an early curator of <a href="https://chem-bla-ics.linkedchemistry.info/2020/10/31/sars-cov-2-covid-19-and-open-science.html">SARS-CoV-2 biological processes</a></li>
  <li>citation intent annotation with the Citation Typing Ontology, see this <a href="https://scholia.toolforge.org/cito/">Scholia overview</a></li>
  <li>nanosafety ontology and data: the <a href="https://github.com/enanomapper/ontologies">eNanoMapper Ontology</a> (ENMO),
<a href="https://figshare.com/search?q=nanowiki">NanoWiki</a>, <a href="https://nanocommons.github.io/specifications/jrc/">JRC nanomaterial index</a> and
<a href="https://nanocommons.github.io/erm-database/">the ERM indentifier database</a></li>
  <li>made RDF for supplementary information (e.g. <a href="http://chem-bla-ics.linkedchemistry.info/2018/09/16/data-curation-5-inspiration-95.html">this NanoE-Tox spreadsheet</a>,
full databases, like <a href="https://chem-bla-ics.linkedchemistry.info/2011/04/21/chembl-09-as-rdf.html">ChEMBL</a> and
<a href="https://chem-bla-ics.linkedchemistry.info/2009/09/04/nmrshiftdb-enters-rdfopenmoleculesnet-2.html">NMRShiftDb <i class="fa-solid fa-recycle fa-xs"></i></a></li>
  <li>organized <a href="https://chem-bla-ics.linkedchemistry.info/2019/10/14/chemcuration-2019-poster-conference.html">an online ChemCuration event</a> (inspired by the ISB annual meetings!)</li>
</ul>

<p>I am also curation my blog, which was <a href="https://chem-bla-ics.linkedchemistry.info/2023/08/18/last-post-here-freebie-model-online.html">originally in blogger.com but being ported to Markdown with extra annotation</a>.
That includes <a href="https://chem-bla-ics.linkedchemistry.info/2023/07/27/archiving-and-updating-my-blog.html">updating URLs</a>
and annotation of blog posts <a href="https://chem-bla-ics.linkedchemistry.info/2005/10/21/viagra-saves-environment.html">with chemicals</a>,
<a href="https://chem-bla-ics.linkedchemistry.info/2024/10/24/vhp4safety.html">grants</a>, and
<a href="https://chem-bla-ics.linkedchemistry.info/2025/02/08/cito-for-blog-citations.html">intention-typed citations</a>.</p>

<h2 id="long-tail">Long tail</h2>

<p>Of course, I have my Wikipedia edits, and contributed to projects like <a href="https://github.com/biopragmatics/bioregistry/commits/main/?author=egonw">Bioregistry.io</a>,
<a href="https://fairsharing.org/users/596">FAIRsharing</a>, regularly submit <a href="https://form.typeform.com/to/SWoxIY?typeform-source=altmetric.typeform.com">missed mentions to Altmetric.com</a>,
etc. There is a long tail in curation. And there is a lot of curation hidden in <a href="https://scholar.google.com/citations?user=u8SjMZ0AAAAJ&amp;hl=en">my literature list</a>.</p>

<p>And that long tail matters to me. I want every researcher to pick up the challenge to curate their own
research output. Put your experimental data in databases, add important provenance, get the details rights.
This is essential to reduce the cost of doing research, and that is more important than ever.</p>

<p>BTW, I must note that our bioinformatics team colleagues too have done a tremendous amount of biocuration,
in WikiPathways (<a href="https://scholia.toolforge.org/author/Q43744369">Denise</a>, <a href="https://scholia.toolforge.org/author/Q28025534">Freddie</a>,
<a href="https://scholia.toolforge.org/author/Q19851164">Susan</a>), in nanosafety (<a href="https://scholia.toolforge.org/author/Q99306396">Jeaphianne</a>,
<a href="https://scholia.toolforge.org/author/Q86442640">Ammar</a>), and in toxicology (<a href="https://scholia.toolforge.org/author/Q42369611">Marvin</a>),
just to name a few. Often together with B.Sc. and M.Sc. students (which <a href="https://europepmc.org/article/med/26557796">can work really well</a>).</p>

<h2 id="award-nomination">Award nomination</h2>

<p>And I hope this makes it clear why I am delighted to was <a href="https://www.biocuration.org/community/biocuration-career-awards/excellence-in-biocuration-advanced-career-award-2025/">nominated last week</a>
for an ISB <em>Excellence in Biocuration Advanced Career Award</em>. The list of past awardees is impressive,
as are the other nominations:
<a href="https://scholia.toolforge.org/author/Q89869027">Laurel Cooper</a>, Oregon State University/USA,
<a href="https://scholia.toolforge.org/author/Q57227590">Steven Marygold</a>, University of Cambridge/UK,
<a href="https://scholia.toolforge.org/author/Q111430202">Saurabh Raghuvanshi</a>, University of Delhi/India, and
<a href="https://scholia.toolforge.org/author/Q59674797">Kimberly Van Auken</a>, California Institute of Technology/USA.</p>

<p>It’s an honor to be listed along these other nominees and being nominated is a great recognition! With a
<em>thank you</em> to the person who proposed my nomination.</p>]]></content><author><name>Egon Willighagen</name></author><category term="curation" /><category term="openscience" /><category term="justdoi:10.1038/455047A" /><category term="doi:10.1021/CI050400B" /><category term="nmrshiftdb" /><category term="europepmc" /><summary type="html"><![CDATA[Depending on your exact definition of doing science, keeping track as precise as possible of your observations is an essential part of doing science. The precision should be high enough that mistakes are obvious. This pattern is, of course, not limited to doing science and we see this in open source development too. Unfortunately, in the modern way of doing science, this is not getting the attention it should get. Worse, with narratives (stories) about the research, in the form of journal articles, are generally considered more important that a precise description of the observations.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/biocuration.png" /><media:content medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/biocuration.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Open Data: the Panton Principles</title><link href="https://chem-bla-ics.linkedchemistry.info/2010/02/19/open-data-panton-principles.html" rel="alternate" type="text/html" title="Open Data: the Panton Principles" /><published>2010-02-19T00:00:00+00:00</published><updated>2010-02-19T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2010/02/19/open-data-panton-principles</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2010/02/19/open-data-panton-principles.html"><![CDATA[<p>The <a href="http://blog.okfn.org/2010/02/19/launch-of-the-panton-principles-for-open-data-in-science/">announcement</a> of the
<a href="http://web.archive.org/web/20100222213041/http://pantonprinciples.org/">Panton Principles <i class="fa-solid fa-box-archive fa-xs"></i></a>
<a href="http://opendotdotdot.blogspot.com/2010/02/open-data-question-of-panton-principles.html">is</a>
<a href="http://web.archive.org/web/20100223064514/http://scienceblogs.com/commonknowledge/2010/02/reaching_agreement_on_the_publ.php">the <i class="fa-solid fa-box-archive fa-xs"></i></a>
<a href="http://usefulchem.blogspot.com/2010/02/support-open-data-by-endorsing-panton.html">big</a>
<a href="http://www.sennoma.net/main/archives/2010/02/panton_principles_for_open_dat.php">news</a>
<a href="http://www.nextgenerationscience.com/open-access/the-panton-principles-for-open-data-in-science/">today</a>,
though Peter already spoke about them
<a href="https://blogs.ch.cam.ac.uk/pmr/2009/05/16/the-panton-principles-a-breakthrough-on-data-licensing-for-public-science/">in May last year <i class="fa-solid fa-recycle fa-xs"></i></a> (see coverage on
<a href="http://friendfeed.com/search?q=panton+principles">FriendFeed</a> and
<a href="http://search.twitter.com/search?q=panton+principles">Twitter</a>). The four principles list in their short versions:</p>

<ul>
  <li>When publishing data make an explicit and robust statement of your wishes.</li>
  <li>Use a recognized waiver or license that is appropriate for data.</li>
  <li>If you want your data to be effectively used and added to by others it should be open as defined by the Open Knowledge/Data Definition – in particular non-commercial and other restrictive clauses should not be used.</li>
  <li>Explicit dedication of data underlying published science into the public domain via PDDL or CCZero is strongly recommended and ensures compliance with both the Science Commons Protocol for Implementing Open Access Data and the Open Knowledge/Data Definition.</li>
</ul>

<p>I think these are very workable next steps in Open Date, perhaps even worthy end goals.
<a href="http://web.archive.org/web/20100222084119/http://pantonprinciples.org/endorse">I endorse them <i class="fa-solid fa-box-archive fa-xs"></i></a>.</p>

<p><img src="/assets/images/panton.png" alt="Sort of logo for the Panton Principles, showing this name and the text &quot;Principles for Open Data in Science&quot;." /></p>

<p><strong>Principle 1: an explicit and robust statement</strong> <br />
This is in my opinion the most important principle. Too often you find a database with really useful data, but without
any clue about what you are allowed to do with this data. Of course, I can contact the authors, get their permission, etc.
They probably like it that way, and I can even understand that. However, it does not scale, and it is slow. Even worse is
the situation when the original composer gets missing in action. Both are equally valid, but explicit statements just make
things easier.</p>

<p><strong>Principle 2: use a waiver or license appropriate for data</strong> <br />
This principle is debatable. Very much like the BSD-vs-GPL flamewars, some like copylefting, others do not. There is an
important difference though. Software has the concept of interfaces, allowing to more easily share incompatible licenses
cleanly separated by these interfaces. This, for example, allows you to run proprietary software on a Linux kernel.
However, data sets do not have such a concept. There is not such thing as an interface between two numbers.</p>

<p>This makes the concept of mixing data sets different: because there is no such interface, any mixing can only happen
between compatible licenses. This is one reason behind the choice of very liberal licenses like
<a href="http://creativecommons.org/license/zero">CC0</a>. This license, or waiver really, allows you to do anything, and most
certainly, mix data sets.</p>

<p>And that makes things a lot easier. But then again, while these are nobel goals, I rather see people use a copylefting
licenses than no license at all.</p>

<p><strong>Principle 3: non-commercial and other restrictive clauses should not be used</strong> <br />
I think again making things easier is the goal. The non-commercial clause is interesting, and actually likely an important
one. Consider course material, a course book. Those are commercial. Some even argued that many universities themselves are
actually commercial entities.</p>

<p><strong>Principle 4: the public domain via PDDL or CCZero is strongly recommended</strong> <br />
I second these choices over a mere claim claim that the data is public domain. The PD concept has many meanings and not
the same in every jurisdiction. In particular, differences between USA and EU law. Waiving these right, which is just
the same as claiming public domain, works in any jurisdiction, again, making things a lot easier.</p>

<p><strong>Open Data, Open Source, Open Standards are not goals</strong> <br />
The underlying pattern of my comments must be clear: the principles make life easier. This is all what Open Source and Open Standards
(<a href="http://blueobelisk.stackexchange.com/questions/231/what-formats-fall-into-open-specification">whatever</a>
<a href="http://blueobelisk.stackexchange.com/questions/106/which-formats-fall-into-open-data-open-source-and-open-standards">those</a>
<a href="http://sourceforge.net/mailarchive/forum.php?thread_name=6aeb064b1002162228qcc0603eo8f363a13f7d46805@mail.gmail.com&amp;forum_name=blueobelisk-discuss">are</a>).</p>

<ul>
<i><b>The three pillars of the ODOSOS mantra is not goals, but merely the means of making life easier.</b></i>
</ul>

<p>The Panton Principles certainly make life easier in Open Data, and initiative like the
<a href="http://esw.w3.org/topic/HCLSIG/LODD/">Linking Open Drug Data</a> in which I participate will greatly benefit
from people adopting them.</p>

<p>The Principles do not solve all problems. There is still a lot of ‘Open Data’ licensed with unrecommended licenses.
For example, the <a href="http://chem-bla-ics.blogspot.com/2009/09/open-chemical-data-1-nmrshiftdb.html">NMRShiftDB</a> uses a
GNU FDL license, and data from supplementary material of Open Access journal articles is like Creative Commons.</p>

<p><img src="/assets/images/panton_is_it_open_data.png" alt="Screenshot of the &quot;Is it Open Data?&quot; website, showing starting points like the &quot;How Does It Work?&quot; button." /></p>

<p>Another related initiative should certainly not go unnoticed either: <a href="http://www.isitopendata.org/">Is it Open Data?</a>
is a service where you can try to resolve what the license is for one of those databases which is not quite
Panton Principles compatible yet.</p>

<p>OK, one last thing. The <a href="http://www.volkskrant.nl/binnenland/article1351058.ece/Krachtmeting_in_kabinet_om_Uruzgan">Dutch government is bursting</a>,
and I want to listen to the music. With permission, I have been hacking the Panton Principles endorsement page,
and injected some extra span elements, to make it easier to machine process (again, to make things easier), so
you can use the following one-liner to calculate the number of people endorsing the principles:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span>wget <span class="nt">-O</span> endorsed.html http://pantonprinciples.org/endorsed.html <span class="p">;</span> xpath <span class="nt">-q</span> <span class="nt">-e</span> <span class="s2">"//span[@class='signature']/span[@class='Country']/text()"</span> endorsed.html | <span class="nb">sort</span> | <span class="nb">uniq</span> <span class="nt">-c</span>
</code></pre></div></div>

<p>The current count is <a href="http://pantonprinciples.org/endorse/">hitting 44 now</a>, and has not quite reached the
<a href="http://friendfeed.com/openchemicaldata/e6236e5a/panton-principles-endorse-open-data-go-visit">500 I had hoped for</a> yet:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>1 Australia
1 Canada
1 Catalonia
2 Espana
2 France
6 Germany
1 Greece
1 Italy
1 Netherlands
1 New Zealand
1 Norway
1 Poland
1 Slovenia
1 Sweden
1 Switzerland
1 The Netherlands
9 UK
1 U.K.
1 United Kingdom
1 United States of America
9 USA
</code></pre></div></div>

<p>Anyone knows how we can convert this into some nice world map graphics with a few lines of code?</p>

<p>Now, I am looking for a bar in Uppsala to write up some ideas about what specifications are :)</p>]]></content><author><name>Egon Willighagen</name></author><category term="opendata" /><category term="nmrshiftdb" /><summary type="html"><![CDATA[The announcement of the Panton Principles is the big news today, though Peter already spoke about them in May last year (see coverage on FriendFeed and Twitter). The four principles list in their short versions:]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/panton_is_it_open_data.png" /><media:content medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/panton_is_it_open_data.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">ChemPedia RDF #1: the SPARQL end point</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/11/19/chempedia-rdf-1-sparql-end-point.html" rel="alternate" type="text/html" title="ChemPedia RDF #1: the SPARQL end point" /><published>2009-11-19T00:00:00+00:00</published><updated>2009-11-19T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/11/19/chempedia-rdf-1-sparql-end-point</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/11/19/chempedia-rdf-1-sparql-end-point.html"><![CDATA[<p>Well, you might spot a pattern here; yes, another chemical <a href="http://pele.farmbio.uu.se/cc0/sparql">SPARQL end point</a>
(actually, it shares the end point with the <a href="https://chem-bla-ics.linkedchemistry.info/2009/11/19/open-notebook-science-solubility-sparql.html">Solubility data <i class="fa-solid fa-recycle fa-xs"></i></a>).
This time around <a href="http://depth-first.com/">Rich</a>’s <a href="http://chempedia.com/substances">ChemPedia</a>. Taking advantage of the
<a href="https://doi.org/10.59350/kprj3-gyg97">CC0-licensed downloads <i class="fa-solid fa-recycle fa-xs"></i></a>,
I have created a small <a href="http://groovy.codehaus.org/">Groovy</a> script (using this <a href="http://json-lib.sourceforge.net/">JSON library</a>)
to convert the ChemPedia <a href="http://en.wikipedia.org/wiki/Json">JSON</a> into
<a href="http://en.wikipedia.org/wiki/Notation3">Notation3</a>:</p>

<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">net.sf.json.groovy.JsonSlurper</span><span class="o">;</span>

<span class="n">input</span> <span class="o">=</span> <span class="k">new</span> <span class="n">File</span><span class="o">(</span><span class="s2">"substances.json"</span><span class="o">)</span>
<span class="n">json</span> <span class="o">=</span> <span class="k">new</span> <span class="n">JsonSlurper</span><span class="o">().</span><span class="na">parse</span><span class="o">(</span><span class="n">input</span><span class="o">);</span>

<span class="n">println</span> <span class="s2">"@prefix dc: &lt;http://purl.org/dc/elements/1.1/&gt;"</span><span class="o">;</span>
<span class="n">println</span> <span class="s2">"@prefix cp: &lt;http://rdf.openmolecules.net/chempedia/onto#&gt;"</span><span class="o">;</span>
<span class="n">json</span><span class="o">.</span><span class="na">each</span> <span class="o">{</span> <span class="n">it</span> <span class="o">-&gt;</span>
  <span class="n">println</span> <span class="s2">"&lt;"</span> <span class="o">+</span> <span class="n">it</span><span class="o">.</span><span class="na">uri</span> <span class="o">+</span> <span class="s2">"&gt; dc:identifier \""</span> <span class="o">+</span> <span class="n">it</span><span class="o">.</span><span class="na">gsid</span> <span class="o">+</span> <span class="s2">"\";"</span><span class="o">;</span>
  <span class="n">println</span> <span class="s2">" &lt;http://www.w3.org/2002/07/owl#sameAs&gt; &lt;http://rdf.openmolecules.net/?"</span> <span class="o">+</span> <span class="n">it</span><span class="o">.</span><span class="na">inchi</span> <span class="o">+</span> <span class="s2">"&gt;;"</span><span class="o">;</span>
  <span class="n">println</span> <span class="s2">"  &lt;http://www.iupac.org/inchi&gt; \""</span> <span class="o">+</span> <span class="n">it</span><span class="o">.</span><span class="na">inchi</span> <span class="o">+</span> <span class="s2">"\"."</span><span class="o">;</span>
  <span class="k">if</span> <span class="o">(</span><span class="n">it</span><span class="o">.</span><span class="na">namings</span><span class="o">.</span><span class="na">size</span><span class="o">()</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">for</span> <span class="o">(</span><span class="kt">int</span> <span class="n">i</span> <span class="o">=</span> <span class="mi">0</span><span class="o">;</span> <span class="n">i</span><span class="o">&lt;</span><span class="n">it</span><span class="o">.</span><span class="na">namings</span><span class="o">.</span><span class="na">size</span><span class="o">();</span> <span class="n">i</span><span class="o">++)</span> <span class="o">{</span>
      <span class="n">naming</span> <span class="o">=</span> <span class="n">it</span><span class="o">.</span><span class="na">namings</span><span class="o">.</span><span class="na">get</span><span class="o">(</span><span class="n">i</span><span class="o">);</span>
      <span class="n">namingURI</span> <span class="o">=</span> <span class="n">it</span><span class="o">.</span><span class="na">uri</span> <span class="o">+</span> <span class="s2">"/naming"</span> <span class="o">+</span> <span class="n">i</span><span class="o">;</span>
      <span class="n">println</span> <span class="s2">"&lt;"</span> <span class="o">+</span> <span class="n">it</span><span class="o">.</span><span class="na">uri</span> <span class="o">+</span> <span class="s2">"&gt; cp:hasNaming "</span> <span class="o">+</span>
        <span class="s2">"&lt;"</span> <span class="o">+</span> <span class="n">namingURI</span> <span class="o">+</span> <span class="s2">"&gt;."</span><span class="o">;</span>
      <span class="n">println</span> <span class="s2">"&lt;"</span> <span class="o">+</span> <span class="n">namingURI</span> <span class="o">+</span> <span class="s2">"&gt; a cp:Naming;"</span><span class="o">;</span>
      <span class="n">println</span> <span class="s2">"  cp:hasName \""</span> <span class="o">+</span> <span class="n">naming</span><span class="o">.</span><span class="na">name</span> <span class="o">+</span> <span class="s2">"\";"</span><span class="o">;</span>
      <span class="n">println</span> <span class="s2">"  cp:hasStatus \""</span> <span class="o">+</span> <span class="n">naming</span><span class="o">.</span><span class="na">status</span> <span class="o">+</span> <span class="s2">"\";"</span><span class="o">;</span>
      <span class="n">println</span> <span class="s2">"  cp:hasScore \""</span> <span class="o">+</span> <span class="n">naming</span><span class="o">.</span><span class="na">score</span> <span class="o">+</span> <span class="s2">"\"."</span><span class="o">;</span>
    <span class="o">}</span>
  <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>After uploading it into <a href="http://virtuoso.openlinksw.com/dataspace/dav/wiki/Main/VOSIndex">Virtuoso</a> (now using <code class="language-plaintext highlighter-rouge">DB.DBA.TTLP</code> instead of
<a href="https://chem-bla-ics.linkedchemistry.info/2009/09/04/nmrshiftdb-enters-rdfopenmoleculesnet-2.html">DB.DBA.RDF_LOAD_RDFXML_MT <i class="fa-solid fa-recycle fa-xs"></i></a>), we can now have our
regular SPARQL fun with the data from ChemPedia. For example, list the 10 names with the most votes:</p>

<div class="language-sparql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">prefix</span><span class="w"> </span><span class="nn">dc</span><span class="o">:</span><span class="w"> </span><span class="nn">&lt;http://purl.org/dc/elements/1.1/&gt;</span><span class="w">
</span><span class="k">prefix</span><span class="w"> </span><span class="nn">cp</span><span class="o">:</span><span class="w"> </span><span class="nn">&lt;http://rdf.openmolecules.net/chempedia/onto#&gt;</span><span class="w">

</span><span class="k">select</span><span class="w"> </span><span class="k">distinct</span><span class="w"> </span><span class="nv">?name</span><span class="w"> </span><span class="nv">?score</span><span class="w"> </span><span class="k">where</span><span class="w"> </span><span class="p">{</span><span class="w">
  </span><span class="nv">?s</span><span class="w"> </span><span class="k">a</span><span class="w"> </span><span class="nn">cp</span><span class="o">:</span><span class="ss">Naming</span><span class="w"> </span><span class="p">;</span><span class="w">
     </span><span class="nn">cp</span><span class="o">:</span><span class="ss">hasName</span><span class="w"> </span><span class="nv">?name</span><span class="w"> </span><span class="p">;</span><span class="w">
     </span><span class="nn">cp</span><span class="o">:</span><span class="ss">hasScore</span><span class="w"> </span><span class="nv">?score</span><span class="w"> </span><span class="p">.</span><span class="w">
</span><span class="p">}</span><span class="w"> </span><span class="k">ORDER</span><span class="w"> </span><span class="k">BY</span><span class="w"> </span><span class="k">DESC</span><span class="p">(</span><span class="nv">?score</span><span class="p">)</span><span class="w"> </span><span class="k">LIMIT</span><span class="w"> </span><span class="mi">10</span><span class="w">
</span></code></pre></div></div>]]></content><author><name>Egon Willighagen</name></author><category term="rdf" /><category term="sparql" /><category term="chempedia" /><category term="justdoi:10.59350/kprj3-gyg97" /><category term="nmrshiftdb" /><summary type="html"><![CDATA[Well, you might spot a pattern here; yes, another chemical SPARQL end point (actually, it shares the end point with the Solubility data ). This time around Rich’s ChemPedia. Taking advantage of the CC0-licensed downloads , I have created a small Groovy script (using this JSON library) to convert the ChemPedia JSON into Notation3:]]></summary></entry><entry><title type="html">NMRShiftDB RDF #3: Bio2RDF</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/10/09/nmrshiftdb-rdf-3-bio2rdf.html" rel="alternate" type="text/html" title="NMRShiftDB RDF #3: Bio2RDF" /><published>2009-10-09T00:00:00+00:00</published><updated>2009-10-09T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/10/09/nmrshiftdb-rdf-3-bio2rdf</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/10/09/nmrshiftdb-rdf-3-bio2rdf.html"><![CDATA[<p>My might have seen my efforts to convert the <a href="http://www.nmrshiftdb.org/">NMRShiftDB</a> data into RDF:</p>

<ul>
  <li><a href="https://chem-bla-ics.linkedchemistry.info/2009/09/05/nmrshiftdb-rdf-2-some-statistics.html">NMRShiftDB RDF #2: Some statistics <i class="fa-solid fa-recycle fa-xs"></i></a></li>
  <li><a href="http://chem-bla-ics.blogspot.com/2009/09/nmrshiftdb-rdf-1-spectra-by-inchi.html">NMRShiftDB RDF #1: Spectra by InChI </a></li>
  <li><a href="https://chem-bla-ics.linkedchemistry.info/2009/09/04/nmrshiftdb-enters-rdfopenmoleculesnet-2.html">NMRShiftDB enters rdf.openmolecules.net #2: SPARQL end point with Virtuoso <i class="fa-solid fa-recycle fa-xs"></i></a></li>
</ul>

<p><a href="http://bio2rdf.blogspot.com/">Peter Ansell</a> has shortly after that copied the data into <a href="http://bio2rdf.org/">Bio2RDF</a>,
but I had not blogged about that yet. So, here goes. If you have not looked at Bio2RDF yet, this is a good time to do that.
The structure of the exposed triples is not perfect, and I just realized I made a beginners mistake, to use a domain name
in a namespace I have not control over (bad me). The Virtuoso6 faceted browser allows you to navigate the data in Bio2RDF
by molecule (e.g. <a href="http://cu.bio2rdf.org/page/nmrshiftdb_molecule:234">molecule 234</a>):</p>

<p><img src="/assets/images/nmrRDF1.png" alt="" /></p>

<p>And by spectrum too (e.g. <a href="http://cu.bio2rdf.org/page/nmrshiftdb_spectrum:4735">spectrum 4735</a>):</p>

<p><img src="/assets/images/nmrRDF2.png" alt="" /></p>]]></content><author><name>Egon Willighagen</name></author><category term="nmrshiftdb" /><category term="rdf" /><category term="bio2rdf" /><summary type="html"><![CDATA[My might have seen my efforts to convert the NMRShiftDB data into RDF:]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/nmrRDF1.png" /><media:content medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/nmrRDF1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">NMRShiftDB RDF #1: Spectra by InChI</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/09/05/nmrshiftdb-rdf-1-spectra-by-inchi.html" rel="alternate" type="text/html" title="NMRShiftDB RDF #1: Spectra by InChI" /><published>2009-09-05T00:00:00+00:00</published><updated>2009-09-05T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/09/05/nmrshiftdb-rdf-1-spectra-by-inchi</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/09/05/nmrshiftdb-rdf-1-spectra-by-inchi.html"><![CDATA[<p>Originally, I wanted to include a SPARQL query in <a href="https://chem-bla-ics.linkedchemistry.info/2009/09/04/nmrshiftdb-enters-rdfopenmoleculesnet-2.html">my yesterdays blog <i class="fa-solid fa-recycle fa-xs"></i></a>
showing how to retrieve <a href="http://www.nmrshiftdb.org/">NMRShiftDB</a> spectra based on an InChIKey, but it horribly failed. I have yet to discover why. This
morning I discovered that it is specific for that field, and that using the same thing with InChI is no problem:</p>

<script src="https://gist.github.com/181307.js"></script>]]></content><author><name>Egon Willighagen</name></author><category term="nmrshiftdb" /><category term="sparql" /><summary type="html"><![CDATA[Originally, I wanted to include a SPARQL query in my yesterdays blog showing how to retrieve NMRShiftDB spectra based on an InChIKey, but it horribly failed. I have yet to discover why. This morning I discovered that it is specific for that field, and that using the same thing with InChI is no problem:]]></summary></entry><entry><title type="html">NMRShiftDB RDF #2: Some statistics</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/09/05/nmrshiftdb-rdf-2-some-statistics.html" rel="alternate" type="text/html" title="NMRShiftDB RDF #2: Some statistics" /><published>2009-09-05T00:00:00+00:00</published><updated>2009-09-05T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/09/05/nmrshiftdb-rdf-2-some-statistics</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/09/05/nmrshiftdb-rdf-2-some-statistics.html"><![CDATA[<p>This morning I had some more fun, and since the <a href="http://www.ebi.ac.uk/nmrshiftdb/nmrshiftdbhtml/statistics.html">statistics</a> view on the
<a href="http://www.nmrshiftdb.org/">NMRShiftDB</a> server is down, I though I could recalculate the statistics myself. Because the current RDF
version of the data does not include all information yet, I cannot reproduce all of them. On the other hand, I can determine some other
interesting statistics.</p>

<h2 id="spectra-per-spectrum-type">Spectra per spectrum type</h2>

<p>One of the statistics given in the aforementioned page is the number of spectra per nuclei. This can be recalculated with the following SPARQL:</p>

<script src="https://gist.github.com/181315.js"></script>

<p>The results for the 1.3.3 release are:</p>

<table>
  <thead>
    <tr>
      <th>nucleus</th>
      <th>count</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>13C</td>
      <td>21958</td>
    </tr>
    <tr>
      <td>1H</td>
      <td>3031</td>
    </tr>
    <tr>
      <td>11B</td>
      <td>326</td>
    </tr>
    <tr>
      <td>17O</td>
      <td>131</td>
    </tr>
    <tr>
      <td>15N</td>
      <td>79</td>
    </tr>
    <tr>
      <td>195Pt</td>
      <td>68</td>
    </tr>
    <tr>
      <td>19F</td>
      <td>50</td>
    </tr>
    <tr>
      <td>31P</td>
      <td>38</td>
    </tr>
    <tr>
      <td>73Ge</td>
      <td>18</td>
    </tr>
    <tr>
      <td>33S</td>
      <td>8</td>
    </tr>
    <tr>
      <td>29Si</td>
      <td>5</td>
    </tr>
  </tbody>
</table>

<p>I am a bit surprised by the count for the silicon NMR spectra, as I would have thought I alone had entered more than just five.</p>

<h2 id="molecules-with-the-most-spectra">Molecules with the most spectra</h2>

<p>It turns out that the molecules have in the 1.3.3 NMRShiftDB release at most 7 spectra, as I can calculate with:</p>

<script src="https://gist.github.com/181324.js"></script>

<p>That is going to change, as the paper I am digitizing now (doi:<a href="http://dx.doi.org/10.1021/jo971176v">10.1021/jo971176v</a>) has carbon and
hydrogen NMR spectra for 7 solvents for each compound :) It should be possible to summarize the number of molecules for each number of
spectra per molecule, but did not manage to get this SPARQL to work out well.</p>

<p>BTW, did you know you can find reprint PDFs of a paper (if any; this one happens to have a <a href="http://ccc.chem.pitt.edu/wipf/Web/4505.pdf">PDF copy</a>)
with Google using the title in quotes and <code class="language-plaintext highlighter-rouge">filetype:pdf</code>? Try <a href="http://www.google.com/search?hl=en&amp;&amp;as_epq=NMR+Chemical+Shifts+of+Common+Laboratory+Solvents+as+Trace+Impurities+&amp;as_oq=&amp;as_eq=&amp;num=10&amp;lr=&amp;as_filetype=pdf&amp;ft=i&amp;as_sitesearch=&amp;as_qdr=all&amp;as_rights=&amp;as_occt=any&amp;cr=&amp;as_nlo=&amp;as_nhi=&amp;safe=images">this query</a>.
The top hit was molecule 10016314 (<a href="http://pele.farmbio.uu.se/nmrshiftdb/?moleculeId=10016314">RDF</a>), which has 4 <sup>13</sup>C
spectra, one <sup>15</sup>N and two proton NMR spectra.</p>

<h2 id="molecules-with-the-most-different-nuclei">Molecules with the most different nuclei</h2>

<p>In the first query, we already save saw in the first SPARQL, there are 11 different nuclei in the database, though carbon and
hydrogen are by far the most abundant spectra. I like diversity, so one statistic I find interesting, is the molecules which
have spectra with the most different nuclei. This is done with the query:</p>

<script src="https://gist.github.com/181326.js"></script>

<p>It shows that molecule 10023801 (<a href="http://pele.farmbio.uu.se/nmrshiftdb/?moleculeId=10023801">RDF</a>) has 5 different NMR types:
<sup>13</sup>C spectra, one <sup>15</sup>N, <sup>29</sup>Si spectra, one <sup>17</sup>O, and <sup>1</sup>H spectra. Unfortunately,
the compound also has chlorines, so it disqualifies as molecule for which NMR spectra are available for all its elements.</p>]]></content><author><name>Egon Willighagen</name></author><category term="nmrshiftdb" /><category term="sparql" /><category term="justdoi:10.1021/jo971176v" /><summary type="html"><![CDATA[This morning I had some more fun, and since the statistics view on the NMRShiftDB server is down, I though I could recalculate the statistics myself. Because the current RDF version of the data does not include all information yet, I cannot reproduce all of them. On the other hand, I can determine some other interesting statistics.]]></summary></entry><entry><title type="html">NMRShiftDB enters rdf.openmolecules.net #2: SPARQL end point with Virtuoso</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/09/04/nmrshiftdb-enters-rdfopenmoleculesnet-2.html" rel="alternate" type="text/html" title="NMRShiftDB enters rdf.openmolecules.net #2: SPARQL end point with Virtuoso" /><published>2009-09-04T00:00:00+00:00</published><updated>2009-09-04T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/09/04/nmrshiftdb-enters-rdfopenmoleculesnet-2</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/09/04/nmrshiftdb-enters-rdfopenmoleculesnet-2.html"><![CDATA[<p>About 6 months ago I <a href="http://chem-bla-ics.blogspot.com/2009/03/nmrshiftdb-enters-rdfopenmoleculesnet.html">reported</a> about my efforts to RDF-ize the data from the
<a href="http://www.nmrshiftdb.org/">NMRShiftDB</a>. Since then, time was consumed by many other things, but now that <a href="http://www.bioclipse.net/">Bioclipse</a> can query
<a href="http://en.wikipedia.org/wiki/SPARQL">SPARQL</a> end points, that I want to contribute the triple set (it is <a href="http://www.gnu.org/copyleft/fdl.html">GNU FDL</a>-licensed)
to <a href="http://www.bio2rdf.org/">Bio2RDF</a>, that a student started working in my group (now larger than just me :) on reasoning on life sciences data, and that I
recently contributed my <a href="http://egonw.posterous.com/nmrshiftdb-1006-contributions-and-counting">1000th NMR spectrum</a> to the database, I thought it was time to
finally reinstall <a href="http://www.openlinksw.com/wiki/main/Main/VOSDownload">Virtuoso</a>.</p>

<p>There are precompiled binaries for <a href="https://launchpad.net/~wdaniels/+archive/ppa">Ubuntu</a> and <a href="http://bugs.debian.org/cgi-bin/bugreport.cgi?bug=508048">Debian</a>,
but Michel encouraged me to use version 6 when <a href="https://chem-bla-ics.linkedchemistry.info/2009/06/26/michel-dumontier-at-uppsala-university.html">he visited us <i class="fa-solid fa-recycle fa-xs"></i></a>.
And so I compiled and install <a href="https://sourceforge.net/projects/virtuoso/files/virtuoso-devel/6.0.0-TP1/">6.0.0.TP1</a> on the public server, while I do have the
binary debs for 5.0.12 on my laptop. With some basic Apache magic, I hooked up the SPARQL end point of the server to the web:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nt">&lt;Proxy</span> <span class="err">/nmrshiftdb/sparql</span><span class="nt">&gt;</span>
  RewriteEngine On
  Allow from all
  ProxyPass        http://localhost:8890/sparql
  ProxyPassReverse http://localhost:8890/sparql
<span class="nt">&lt;/Proxy&gt;</span>
</code></pre></div></div>

<p>Nice thing about this is, that I can set up multiple servers, allowing me to keep incompatibly licensed data sets apart (see
<a href="https://chem-bla-ics.linkedchemistry.info/2009/05/18/open-data-license-rights-aggregation.html">Open Data: license, rights, aggregation, clean interfaces? <i class="fa-solid fa-recycle fa-xs"></i></a>), which is
the same approach Bio2RDF is taking.</p>

<p>The <a href="http://pele.farmbio.uu.se/nmrshiftdb/sparql">end point</a> now offers about <a href="http://pele.farmbio.uu.se/nmrshiftdb/sparql?default-graph-uri=&amp;query=SELECT+count%28*%29+WHERE+{\%0D%0A++%3Fs+%3Fp+%3Fo+.%0D%0A}&amp;format=text%2Fhtml&amp;debug=on">278887</a>
triples, but this will soon rise as I make more content from the database available in the original SQL database. The data is from the
<a href="https://sourceforge.net/projects/nmrshiftdb/files/nmrshiftdb/1.3.3/">1.3.3 release</a> by <a href="http://www.steinbeck-molecular.de/steinblog/">Chris</a>’
team, and does not include my 1000th spectrum.</p>

<p>Getting the data into the database was not trivial either. The documentation suggests WebDAV, and that indeed worked for me once, after
using the <a href="http://www.snee.com/bobdc.blog/2009/02/getting-started-using-virtuoso.html">curl approach suggested here</a>. But upon a second upload, it
did again not enter the store. The ultimate solution was to use the iSQL interface, with the following SQL</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>DB.DBA.RDF_LOAD_RDFXML_MT(
  file_to_string_output('/tmp/nmrshiftdb.rdf'), '',
  'http://pele.farmbio.uu.se/nmrshiftdb'
);
</code></pre></div></div>

<p>Scientifically, this progress is not overly interesting, although it makes it very clear that you really should not have to be happy with proprietary
and non-semantic formats for anything. But, to me, this is mostly a technological success of great importance: I can now share really large sets of
RDF data.</p>

<p>Querying this data is a simple with SPARQL, and the results are available in various formats, such as JSON, which makes it easy to integrate in
third-party applications or <a href="https://chem-bla-ics.linkedchemistry.info/2009/09/02/google-wave-robot-for-cdk-functionality.html">Google Wave robots <i class="fa-solid fa-recycle fa-xs"></i></a>
(did I hear someone say <a href="http://nmrshifty.appspot.com/">NMRShifty</a>?). As I have <a href="http://chem-bla-ics.blogspot.com/search?q=sparql">blogged before</a>,
SPARQL is an excellent tool to aggregate scientific data prior to data analysis. And I will demo more interesting queries later this month.</p>]]></content><author><name>Egon Willighagen</name></author><category term="rdf" /><category term="sparql" /><category term="nmrshiftdb" /><category term="cheminf" /><summary type="html"><![CDATA[About 6 months ago I reported about my efforts to RDF-ize the data from the NMRShiftDB. Since then, time was consumed by many other things, but now that Bioclipse can query SPARQL end points, that I want to contribute the triple set (it is GNU FDL-licensed) to Bio2RDF, that a student started working in my group (now larger than just me :) on reasoning on life sciences data, and that I recently contributed my 1000th NMR spectrum to the database, I thought it was time to finally reinstall Virtuoso.]]></summary></entry><entry><title type="html">Open Data: license, rights, aggregation, clean interfaces?</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/05/18/open-data-license-rights-aggregation.html" rel="alternate" type="text/html" title="Open Data: license, rights, aggregation, clean interfaces?" /><published>2009-05-18T00:00:00+00:00</published><updated>2009-05-18T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/05/18/open-data-license-rights-aggregation</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/05/18/open-data-license-rights-aggregation.html"><![CDATA[<p>A <a href="http://blog.openwetware.org/scienceintheopen/2009/05/15/a-breakthrough-on-data-licensing-for-public-science/">recent post</a> by
<a href="http://blog.openwetware.org/scienceintheopen/">Cameron</a> on his visit last week with <a href="http://wwmm.ch.cam.ac.uk/blogs/adams/">Nico</a>,
<a href="http://wwmm.ch.cam.ac.uk/blogs/murrayrust/">Peter</a> and <a href="http://wwmm.ch.cam.ac.uk/blogs/downing/">Jim</a>, discussed
<a href="http://en.wikipedia.org/wiki/Open_data">Open Data</a> licensing. This lead to an interesting discussion on these matters, and
questions by me on why people care so much about only public domain data (or licensed with
<a href="http://www.opendatacommons.org/licenses/pddl/1.0/">PDDL</a> or <a href="http://wiki.creativecommons.org/CC0">CC0</a>).</p>

<p>Open licensing for data has not as much matured as for software, and international law seems to be more confusing about the
issues. I guess that is because data aggregation has been around for way before the computer era. The PDDL and CC0 both try to
overcome this fuzziness. But there is another issue we need to keep in mind. A lot of useful Data was aggregated and made Open
<em>before</em> these licenses came about, and use, for example, the <a href="http://www.gnu.org/copyleft/fdl.html">GNU FDL</a> license, such as
the <a href="http://www.nmrshiftdb.org/">NMRShiftDB</a>.</p>

<h2 id="rights">Rights</h2>

<p>Right now, there are two Open Data camps, much like the BSD-vs-GPL wars in Open Source: one that believes in waiving any rights
on the Data, indicating that facts are free; others that believe that data must be protected to not be eaten by big companies
and lost to the community (e.g. <a href="http://friendfeed.com/onssolubility/cf6afd52/should-we-contribute-solubility-data-to">the WolframAlpha arragnements are suspect</a>).</p>

<p>Of course, both camps are not that far apart, and both believe Open is important. Interestingly, there are some noteworthy
differences with the Open Source wars. I see parallels between the two, which details an important difference: Open Source has
algorithms (uncopyrightable) and implementations (copyrightable); Open Data has Data (uncopyrightable) and aggregation
(copyrightable). Open Source talks mostly about the implementation, not the algorithm; it’s Open Source, not Open Algorithms
after all. In cheminformatics it is even often the case that the algorithms are not even specified and that there only truly
is source.</p>

<p>However, Open Data in title does not make distinction. Data is fairly cheap and acquisition can be automated and computerized;
Aggregation, on the other hand, requires human involvement: curation and thinking about data models, etc. This is where added
value is. Consider an assigned NMR spectrum or the raw data returned from the spectrometer.</p>

<p>It is this added value that people want to protect, not the data itself. I think.</p>

<h2 id="aggregation">Aggregation</h2>

<p>One important argument that tend to show up when people argument for PDDL and CC0 is that it makes data aggregation easier.
This is most certainly true: if you can do whatever you like with a blob of data, that also means aggregate with any other
blob of data. However, copyleft licenses, like the GNU FDL, require the aggregation to have a compatible license too. It is
the license incompatibilities that make this impossible. Or … ?</p>

<p>Open Source has matured to such a point that it is fairly clear what the intended behaviour is, regarding derivatives. An
aggregation of software (typically refered to as a distribution) is only a derivative under certain conditions. This makes
it possible to run proprietary software on top of GNU/Linux, which uses the GNU GPL but does not require software to run on
top of it to be GPL too. Unless… unless, not a clear well-defined interface has been used, indicating a strong dependency.
Now, surely, these things have not been confirmed to match actual law in court, but the intentions are clear.</p>

<h2 id="clean-data-interfaces">Clean Data Interfaces?</h2>

<p>Now, if we would translate this to Open Data, would there be the equivalent of a clean interface? Can we build a data
distribution with data of various licenses? I think we can! I am not a lawyer and please consider this an invitation
to discuss these matters…</p>

<p>Let’s start simlpe… if I put a GNU FDL image in this blog, by linking to it with a open, free, clean HTML interface
(<code class="language-plaintext highlighter-rouge">&lt;img src=""/&gt;</code>), would that make my blog GNU FDL too? I don’t think so. Surely, I would need to list copyright owner,
and actually would be required to put the GNU FDL in my blog too, but hope linking to the license text would suffice too.
(Let’s skip fair use at this moment, and assume the use goes beyond fair use). Question: am I not using a clean interface,
and would this not make the image’s license no infect my blog?</p>

<p>A more difficult example, consider <a href="http://rdf.openmolecules.net/">rdf.openmolecules.net</a>, which surely aggregated facts,
including data from the NMRShiftDB and <a href="http://dbpedia.org/">DBPedia</a>. I am using a unique identifiers here, the NMRShiftDB
compound ID, and the DBPedia URL, which surely is GNU FDL, and use this to make a <code class="language-plaintext highlighter-rouge">&lt;owl:sameAs&gt;</code> statement. Again, please do
not consider fair use, which this certainly is. But, let’s say I put in some more DBPedia and NMRShiftDB data in this
aggregation. The GNU FDL data on rdf.openmolecules.net would be separate RDF blocks, with proper dc:license, dc:author
annotation. But the block would be part of a larger aggregation. The clean interface here is
<a href="http://en.wikipedia.org/wiki/Resource_description_framework">Resource Description Framework</a>.</p>

<p>This second case does not only affect my rdf.openmolecules.net website, but, for example, <a href="http://bio2rdf.org/">bio2rdf.org</a>
is also in the same situation and aggregated and distribute DBPedia’s GNU FDL data (e.g.
<a href="http://bio2rdf.org/searchns/dbpedia/hexokinase">hexinanose</a>. Does that make the
whole of bio2rdf database GNU FDL. They too use RDF as clean interface.</p>

<h2 id="call-for-discussion">Call for Discussion</h2>

<p>Despite what one of the two camps like to see, the mere fact of added value when making data aggregations will keep
copyleft license stay around, and instead of trying to convince everyone of the virtues of PDDL- and CC0-like licenses,
we should think about to what extend it really matters.</p>

<p>I can do my data analysis with data sources of various licenses. I can search and retrieve data from various sources
with various licenses. What obstacles are really there that disallow us to do science? Do the data interfaces we have
now not provide enough technical means to address the license incompatibilities? They have in Open Source, why would
that not apply to Open Data too?</p>]]></content><author><name>Egon Willighagen</name></author><category term="opendata" /><category term="nmrshiftdb" /><category term="rdf" /><category term="dbpedia" /><category term="bio2rdf" /><summary type="html"><![CDATA[A recent post by Cameron on his visit last week with Nico, Peter and Jim, discussed Open Data licensing. This lead to an interesting discussion on these matters, and questions by me on why people care so much about only public domain data (or licensed with PDDL or CC0).]]></summary></entry><entry><title type="html">NMRShiftDB enters rdf.openmolecules.net</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/03/18/nmrshiftdb-enters-rdfopenmoleculesnet.html" rel="alternate" type="text/html" title="NMRShiftDB enters rdf.openmolecules.net" /><published>2009-03-18T00:00:00+00:00</published><updated>2009-03-18T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/03/18/nmrshiftdb-enters-rdfopenmoleculesnet</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/03/18/nmrshiftdb-enters-rdfopenmoleculesnet.html"><![CDATA[<p>This morning I finished setting up a <a href="http://en.wikipedia.org/wiki/RDF">RDF</a> interface to the <a href="http://www.nmrshiftdb.org/">NMRShiftDB</a> data
(see <a href="http://pele.farmbio.uu.se/nmrshiftdb/?moleculeId=234">nmr:234</a>):</p>

<p><img src="/assets/images/nmrRDF.png" alt="" /></p>

<p>And made links between the new frontend and <a href="http://rdf.openmolecules.net/">rdf.openmolecules.net</a>, make the
<em>Linked Open Chemistry Data</em> (LOCD) network grow (naming following <a href="http://esw.w3.org/topic/HCLSIG/LODD">Linked Open Drug Data</a>).
In comparison with the previous depiction, I added arrows to indicate the direction of the linking. Green nodes still indicate
sources with an RDF interface; therefore, the LOCD network consists really only of those green nodes:</p>

<p><img src="/assets/images/ons2.png" alt="" /></p>

<p>The link with DBPedia is discussed in <a href="https://chem-bla-ics.linkedchemistry.info/2009/02/17/dbpedia-enters-rdfopenmoleculesnet.html">DBPedia enters rdf.openmolecules.net <i class="fa-solid fa-recycle fa-xs"></i></a>.
The <a href="http://github.com/egonw/nmrshiftdb-rdf/tree/master">source code for the NMRShiftDB-RDF frontend</a> can be found at
<a href="http://www.github.com/">GitHub</a>.</p>]]></content><author><name>Egon Willighagen</name></author><category term="nmrshiftdb" /><category term="rdf" /><category term="opendata" /><category term="nmrshiftdb" /><summary type="html"><![CDATA[This morning I finished setting up a RDF interface to the NMRShiftDB data (see nmr:234):]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/nmrRDF.png" /><media:content medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/nmrRDF.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">NMRShiftDB enters rdf.openmolecules.net</title><link href="https://chem-bla-ics.linkedchemistry.info/2009/03/18/nmrshiftdb-enters-rdfopenmoleculesnet.html" rel="alternate" type="text/html" title="NMRShiftDB enters rdf.openmolecules.net" /><published>2009-03-18T00:00:00+00:00</published><updated>2009-03-18T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2009/03/18/nmrshiftdb-enters-rdfopenmoleculesnet</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2009/03/18/nmrshiftdb-enters-rdfopenmoleculesnet.html"><![CDATA[<p>This morning I finished setting up a <a href="http://en.wikipedia.org/wiki/RDF">RDF</a> interface to the <a href="http://www.nmrshiftdb.org/">NMRShiftDB</a> data
(see <a href="http://pele.farmbio.uu.se/nmrshiftdb/?moleculeId=234">nmr:234</a>):</p>

<p><img src="/assets/images/nmrRDF.png" alt="" /></p>

<p>And made links between the new frontend and <a href="http://rdf.openmolecules.net/">rdf.openmolecules.net</a>, make the
<em>Linked Open Chemistry Data</em> (LOCD) network grow (naming following <a href="http://esw.w3.org/topic/HCLSIG/LODD">Linked Open Drug Data</a>).
In comparison with the previous depiction, I added arrows to indicate the direction of the linking. Green nodes still indicate
sources with an RDF interface; therefore, the LOCD network consists really only of those green nodes:</p>

<p><img src="/assets/images/ons2.png" alt="" /></p>

<p>The link with DBPedia is discussed in <a href="https://chem-bla-ics.linkedchemistry.info/2009/02/17/dbpedia-enters-rdfopenmoleculesnet.html">DBPedia enters rdf.openmolecules.net <i class="fa-solid fa-recycle fa-xs"></i></a>.
The <a href="http://github.com/egonw/nmrshiftdb-rdf/tree/master">source code for the NMRShiftDB-RDF frontend</a> can be found at
<a href="http://www.github.com/">GitHub</a>.</p>]]></content><author><name>Egon Willighagen</name></author><category term="nmrshiftdb" /><category term="rdf" /><category term="opendata" /><category term="nmrshiftdb" /><summary type="html"><![CDATA[This morning I finished setting up a RDF interface to the NMRShiftDB data (see nmr:234):]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/nmrRDF.png" /><media:content medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/nmrRDF.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>