<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.3.4">Jekyll</generator><link href="https://chem-bla-ics.linkedchemistry.info/feed/by_tag/json.xml" rel="self" type="application/atom+xml" /><link href="https://chem-bla-ics.linkedchemistry.info/" rel="alternate" type="text/html" /><updated>2026-11-22T12:40:33+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/feed/by_tag/json.xml</id><title type="html">chem-bla-ics</title><subtitle>Chemblaics (pronounced chem-bla-ics) is the science that uses open science and computers to solve problems in chemistry, biochemistry and related fields.</subtitle><author><name>Egon Willighagen</name></author><entry><title type="html">Rogue Scholar keeps challenging the functionality of my blog</title><link href="https://chem-bla-ics.linkedchemistry.info/2026/08/23/rogue-scholar-keeps-challenging-the-functionality-of-my-blog.html" rel="alternate" type="text/html" title="Rogue Scholar keeps challenging the functionality of my blog" /><published>2026-08-23T00:00:00+00:00</published><updated>2026-08-23T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2026/08/23/rogue-scholar-keeps-challenging-the-functionality-of-my-blog</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2026/08/23/rogue-scholar-keeps-challenging-the-functionality-of-my-blog.html"><![CDATA[<p><a href="https://rogue-scholar.org/">Rogue Scholar</a> continues to offer <a href="https://chem-bla-ics.linkedchemistry.info/2024/07/21/rogue-scholar-and-more.html">awesome features</a>.
It seems the recent move to InvenioRDM (<a href="https://doi.org/10.63517/kshzw-ay335">14.0 was just released</a>) was a good one. It does require rewrites, but make
things more scalable. One thing that did exist in the InvenioRDM-based Rogue Scholar last year was <a href="https://doi.org/10.53731/zyg15-qv911">citations to blog posts</a>.
But even that was <a href="https://doi.org/10.53731/1jbsg-kqm79">redeveloped and relaunched</a> a few days ago. It does not have yet the same amount of citations to
blog posts as before, but <a href="https://rogue-scholar.org/search?q=citations%3A%2A&amp;l=list&amp;p=1&amp;s=10&amp;sort=newest">more than 1200 can be found again</a>.</p>

<p>Platforms are getting more better at precisely capturing how we communicate science. Rogue Scholar is a great example of that, like the
no longer existing <a href="https://chem-bla-ics.linkedchemistry.info/tag/citeulike">CiteULike</a> before. And Rogue Scholar has been challenging
my Markdown-based blog post to support its functionality. For example, I had to <a href="https://chem-bla-ics.linkedchemistry.info/2025/01/19/blog-updates.html">add a JSON Feed</a>,
but also was happy that <a href="https://doi.org/10.53731/1xbh4-mnt50">Rogue Scholar added CiTO Support</a>.</p>

<p>But capturing all citations between things remains an issue. Platforms like Google Scholar and Web of Science do their best, but their
best is not Open or nor FAIR or neither. Generally, it has taken way too long for
<a href="https://doi.org/10.1045/january2015-brase">DataCite</a> and <a href="https://doi.org/10.7717/peerj-cs.86">Software Citations</a> to be picked up.
However, we can <a href="https://chem-bla-ics.linkedchemistry.info/2024/12/30/fair-blog-to-blog-citations.html">take control ourselves</a> when
solutions do not exist.</p>

<p>And because I want journal-to-blog citations are FAIR too, I hacked up another extension of my blog today. I can now add lines like this
to the metadata of blog post:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">cited-in</span><span class="pi">:</span> <span class="s">cito:discusses:10.1186/1471-2105-8-487</span>
</code></pre></div></div>

<p>What is encodes is that the article with doi:<a href="https://doi.org/10.1186/1471-2105-8-487">10.1186/1471-2105-8-487</a> (one of my own)
discusses <a href="https://chem-bla-ics.linkedchemistry.info/2006/12/17/counting-stereoisomers-from-molecular_17.html">one of the posts in my blog</a>.</p>

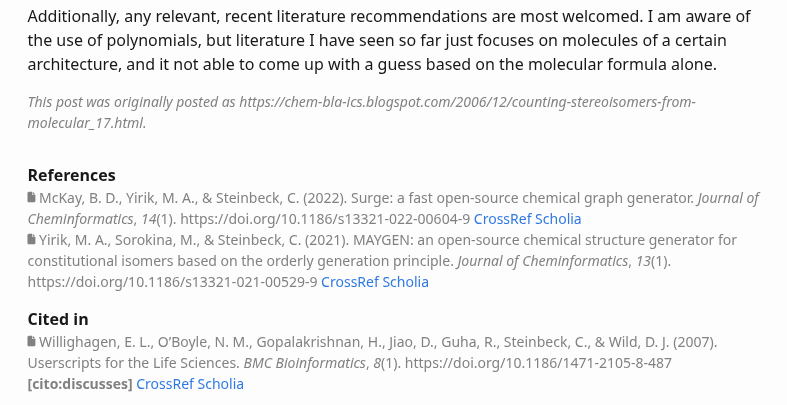
<p>Online, this is rendered with <a href="https://doi.org/10.7717/peerj-cs.214">citation.js</a> like this:</p>

<p><img src="/assets/images/blogs_citedin.png" alt="" /></p>

<p>Here, the <em>References</em> are the things I cite in my blog post, and the <em>Cited in</em> are things citing this blog post.</p>

<h3 id="how-blog-posts-are-cited">How blog posts are cited</h3>

<p>Now, DOIs for blog posts are a new thing: they did not exist when I started blogging. And for the 12 citations I found so far,
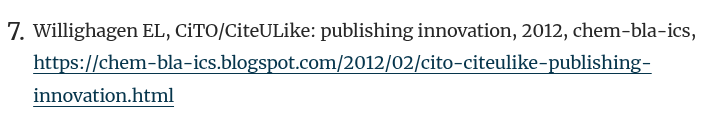
they are not using a DOI. I doubt that these citations are easily found in CrossRef or DataCite. Here are two examples, of increasing
complexity. The first one is how many citation styles would do it:</p>

<p><img src="/assets/images/blogs_citing1.png" alt="" /></p>

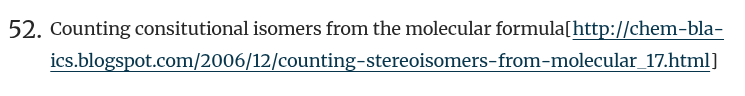
<p>But they can also look like this:</p>

<p><img src="/assets/images/blogs_citing2.png" alt="" /></p>

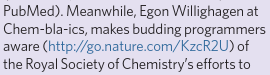
<p>And scientific journals sometimes even use URL shorteners and then it may look like this:</p>

<p><img src="/assets/images/blogs_citing3.png" alt="" /></p>

<p>This makes it a challenge for any platform to pick up these citations!</p>

<h3 id="how-about-the-json-feed">How about the JSON Feed</h3>

<p>That leaves me with how I make this information avaiable, a bit towards FAIR, but at least machine readable.
This is done with a <a href="https://egonw.github.io/JSONFeed-extensions/">JSON Feed extension</a> (at the time of writing, I did
not add this proposal yet). My <code class="language-plaintext highlighter-rouge">archive.json</code> feed now contains 12 fragments like this:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nl">"_citations"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
  </span><span class="p">{</span><span class="w">
    </span><span class="nl">"url"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://doi.org/10.1038/nchem.2187"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"doi"</span><span class="p">:</span><span class="w"> </span><span class="s2">"10.1038/nchem.2187"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"cito"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
      </span><span class="s2">"citesForInformation"</span><span class="w">
    </span><span class="p">]</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">]</span><span class="w">
</span></code></pre></div></div>

<p>It matches the structure of the <a href="https://egonw.github.io/JSONFeed-extensions/references.html">_references extension</a>.</p>

<p>Let’s see where this goes :)</p>]]></content><author><name>Egon Willighagen</name></author><category term="cito:citesAsRecommendedReading:10.63517/kshzw-ay335" /><category term="blog" /><category term="cito:citesAsRecommendedReading:10.53731/zyg15-qv911" /><category term="cito" /><category term="cito:citesAsRecommendedReading:10.53731/1jbsg-kqm79" /><category term="cito:citesAsRecommendedReading:10.53731/1xbh4-mnt50" /><category term="mycito:discusses:10.1186/1471-2105-8-487" /><category term="cito:usesMethodIn:10.7717/peerj-cs.214" /><category term="cito:citesAsRecommendedReading:10.7717/peerj-cs.86" /><category term="cito:citesAsRecommendedReading:10.1045/january2015-brase" /><category term="json" /><summary type="html"><![CDATA[Rogue Scholar continues to offer awesome features. It seems the recent move to InvenioRDM (14.0 was just released) was a good one. It does require rewrites, but make things more scalable. One thing that did exist in the InvenioRDM-based Rogue Scholar last year was citations to blog posts. But even that was redeveloped and relaunched a few days ago. It does not have yet the same amount of citations to blog posts as before, but more than 1200 can be found again.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/blogs_citedin.png" /><media:content medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/blogs_citedin.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">CiTO for blog citations</title><link href="https://chem-bla-ics.linkedchemistry.info/2025/02/08/cito-for-blog-citations.html" rel="alternate" type="text/html" title="CiTO for blog citations" /><published>2025-02-08T00:00:00+00:00</published><updated>2025-02-08T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2025/02/08/cito-for-blog-citations</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2025/02/08/cito-for-blog-citations.html"><![CDATA[<p>This is mostly a test, but if it turns out the way I hope it will, likely after a few iterations, it adds
support in my blog for CiTO intent annotations to the DOIs I cite. I
<a href="https://chem-bla-ics.linkedchemistry.info/2024/12/30/fair-blog-to-blog-citations.html">pondered about the earlier</a>.
In the <a href="https://www.jsonfeed.org/version/1.1/">JSON Feed</a> it should, at least for now, show up like this:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nl">"_references"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
  </span><span class="p">{</span><span class="w">
    </span><span class="nl">"url"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://doi.org/10.59350/er1mn-m5q69"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"doi"</span><span class="p">:</span><span class="w"> </span><span class="s2">"10.59350/er1mn-m5q69"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"cito"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w"> </span><span class="s2">"extends"</span><span class="w"> </span><span class="p">]</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">]</span><span class="w">
</span></code></pre></div></div>]]></content><author><name>Egon Willighagen</name></author><category term="cito" /><category term="blog" /><category term="cito:extends:10.59350/er1mn-m5q69" /><category term="json" /><summary type="html"><![CDATA[This is mostly a test, but if it turns out the way I hope it will, likely after a few iterations, it adds support in my blog for CiTO intent annotations to the DOIs I cite. I pondered about the earlier. In the JSON Feed it should, at least for now, show up like this:]]></summary></entry><entry><title type="html">Downloading all currently released BridgeDb identifier mapping databases</title><link href="https://chem-bla-ics.linkedchemistry.info/2021/02/16/downloading-all-currently-released.html" rel="alternate" type="text/html" title="Downloading all currently released BridgeDb identifier mapping databases" /><published>2021-02-16T00:00:00+00:00</published><updated>2021-02-16T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2021/02/16/downloading-all-currently-released</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2021/02/16/downloading-all-currently-released.html"><![CDATA[<p>The <a href="https://bridgedb.github.io/">BridgeDb</a> project (doi:<a href="https://doi.org/10.1186/1471-2105-11-5">10.1186/1471-2105-11-5</a>)
(and <a href="https://elixir-europe.org/platforms/interoperability/rirs">ELIXIR recommended interoperability resource</a>) has several
aims, all around identifier mapping:</p>

<ul>
  <li>provide a Java API for identifier mapping</li>
  <li>provide ID mappings (two flavors: with and without semantic meaning)</li>
  <li>provide services (<a href="https://www.bioconductor.org/packages/release/bioc/html/BridgeDbR.html">R package</a>,
<a href="http://webservice.bridgedb.org/">OpenAPI webservice</a>)</li>
  <li>track the history of identifiers</li>
</ul>

<p>The last one is more recent and two aspects are under development here: secondary identifiers and dead identifiers. More
about that in some future post. About the first and the third I am also not going to tell much in this post. Just follow the
above links.</p>

<p>I do want to say something in this post about the actually identifier mapping databases, in particular those we distribute as
Apache Derby files, the storage format used by the Java libraries. These are the files you download if you want mapping databases
for <a href="https://pathvisio.github.io/">PathVisio</a> (doi:<a href="https://doi.org/10.1371/journal.pcbi.1004085">10.1371/journal.pcbi.1004085</a>).
BridgeDb has mapping files for various things and some example databases the data it maps between:</p>

<ol>
  <li>genes and proteins: Ensembl, UniProt, NCBI Gene</li>
  <li>metabolites; HMDB, ChEBI, LIPID MAPS, Wikidata, CAS</li>
  <li>publications: DOI, PubMed</li>
  <li>macromolecular complexes: Complex Portal, Wikidata</li>
</ol>

<p>The BridgeDb API is agnostic to the things it can map identifiers for.</p>

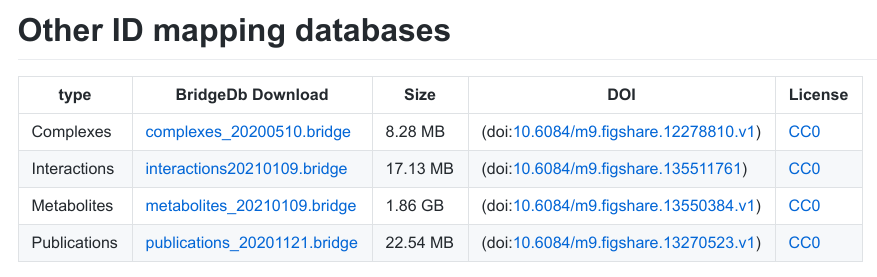
<p><strong>Downloading mapping files</strong>:
BridgeDb has an <a href="https://bioschemas.org/">BioSchemas</a>-powered
<a href="https://bridgedb.github.io/data/gene_database/">web page with an overview of the latest released mapping files</a>.
It looks like this:</p>

<p><img src="/assets/images/bridgedbDownloadsImage.png" alt="" /></p>

<p>This webpage is the result from the cyber attack in late 2019, disrupting a good bit of the infrastructure. This is why we
renewed the website, including the download page. The new page actually is hosted <a href="https://github.com/bridgedb/data">on GitHub as a Markdown file</a>,
but this is where things get interesting. The Markdown file is actually autogenerated from a JSON file with all the info. Everything,
including the BioSchemas annotation is created from that. Basically, JSON gets converted into Markdown (with a custom script), which
gets converted into HTML by a GitHub Action/Pages. So, when someone releases a new mapping file on Zenodo or Figshare, they only have
to send me a pull request with updated JSON file.</p>

<p>Now, previously, downloading all released mapping files, for example for the BridgeDb webservice, was a bit complicated. The
information was a HTML file generated by the webserver for a folder. No metadata. Nuno wrote code to extract the relevant info
and download all the files. However, since the information is now available in a public JSON file, it is a lot easier. The
following code uses wget and jq, two tools readily available on the popular operating systems. Have fun!</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">!</span>/bin/bash

wget <span class="nt">-nc</span> https://bridgedb.github.io/data/gene.json
wget <span class="nt">-nc</span> https://bridgedb.github.io/data/corona.json
wget <span class="nt">-nc</span> https://bridgedb.github.io/data/other.json

jq <span class="nt">-r</span> <span class="s1">'.mappingFiles | .[] | "\(.file)=\(.downloadURL)"'</span> gene.json <span class="o">&gt;</span> files.txt
jq <span class="nt">-r</span> <span class="s1">'.mappingFiles | .[] | "\(.file)=\(.downloadURL)"'</span> corona.json <span class="o">&gt;&gt;</span> files.txt
jq <span class="nt">-r</span> <span class="s1">'.mappingFiles | .[] | "\(.file)=\(.downloadURL)"'</span> other.json <span class="o">&gt;&gt;</span> files.txt

<span class="k">for </span>FILE <span class="k">in</span> <span class="si">$(</span><span class="nb">cat </span>files.txt<span class="si">)</span>
<span class="k">do
  </span>readarray <span class="nt">-d</span> <span class="o">=</span> <span class="nt">-t</span> splitFILE<span class="o">&lt;&lt;&lt;</span> <span class="s2">"</span><span class="nv">$FILE</span><span class="s2">"</span>
  <span class="nb">echo</span> <span class="k">${</span><span class="nv">splitFILE</span><span class="p">[0]</span><span class="k">}</span>
  wget <span class="nt">-nc</span> <span class="nt">-O</span> <span class="k">${</span><span class="nv">splitFILE</span><span class="p">[0]</span><span class="k">}</span> <span class="k">${</span><span class="nv">splitFILE</span><span class="p">[1]</span><span class="k">}</span>
<span class="k">done</span>
</code></pre></div></div>

<p>Actually, while writing this blog post, I notice the code can be further simplified.</p>]]></content><author><name>Egon Willighagen</name></author><category term="bridgedb" /><category term="json" /><category term="justdoi:10.1186/1471-2105-11-5" /><category term="justdoi:10.1371/journal.pcbi.1004085" /><summary type="html"><![CDATA[The BridgeDb project (doi:10.1186/1471-2105-11-5) (and ELIXIR recommended interoperability resource) has several aims, all around identifier mapping:]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://chem-bla-ics.linkedchemistry.info/assets/images/bridgedbDownloadsImage.png" /><media:content medium="image" url="https://chem-bla-ics.linkedchemistry.info/assets/images/bridgedbDownloadsImage.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Programming in the Life Sciences #10: JavaScript Object Notation (JSON)</title><link href="https://chem-bla-ics.linkedchemistry.info/2013/10/30/programming-in-life-sciences-10.html" rel="alternate" type="text/html" title="Programming in the Life Sciences #10: JavaScript Object Notation (JSON)" /><published>2013-10-30T00:10:00+00:00</published><updated>2013-10-30T00:10:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2013/10/30/programming-in-life-sciences-10</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2013/10/30/programming-in-life-sciences-10.html"><![CDATA[<p>As said, <a href="https://en.wikipedia.org/wiki/JSON">JSON</a> is the format we will use as serialization format
for answers given by the <a href="https://dev.openphacts.org/docs">Open PHACTS LDA</a>. The API actually supports
XML, RDF, HTML, and TSV too, but I think JSON is a good balance between expressiveness and compactness.
Moreover, and perhaps a much better argument, JSON works very well in a JavaScript environment: it is
very easy to convert the serialization into a data model:</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">var</span> <span class="nx">jsonData</span> <span class="o">=</span> <span class="nx">JSON</span><span class="p">.</span><span class="nf">parse</span><span class="p">(</span><span class="nx">jsonString</span><span class="p">);</span>
</code></pre></div></div>

<p>Now, we previously covered maps. Maps have keys and values: the keys unlock a particular value.
For example, take this JavaScript:</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">var</span> <span class="nx">map</span> <span class="o">=</span> <span class="p">{</span> <span class="dl">"</span><span class="s2">key</span><span class="dl">"</span><span class="p">:</span> <span class="dl">"</span><span class="s2">value</span><span class="dl">"</span><span class="p">,</span> <span class="dl">"</span><span class="s2">key2</span><span class="dl">"</span><span class="p">:</span> <span class="dl">"</span><span class="s2">value2</span><span class="dl">"</span> <span class="p">};</span>
</code></pre></div></div>

<p>We define here a key-value object, and we can access the two values with the two keys:</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nx">map</span><span class="p">[</span><span class="dl">"</span><span class="s2">key2</span><span class="dl">"</span><span class="p">];</span> <span class="c1">// == value2</span>
</code></pre></div></div>

<p>These examples are JavaScript source code. Not a string. The content of the map variable is a data
structure. But when we communicate with a web service, we need a (string) serialization of the data
model, because we cannot send around memory pointers (which a variable is) because they are only
valid on a single machine.</p>

<p>This is where the JSON format comes in. We can convert the content of the above map variable into a
string representation with this code:</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">var</span> <span class="nx">mapStringified</span> <span class="o">=</span> <span class="nx">JSON</span><span class="p">.</span><span class="nf">stringify</span><span class="p">(</span><span class="nx">map</span><span class="p">);</span>
</code></pre></div></div>

<p>which gives us the following output:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="nl">"key"</span><span class="p">:</span><span class="s2">"value"</span><span class="p">,</span><span class="nl">"key2"</span><span class="p">:</span><span class="s2">"value2"</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>This string looks an awful lot like the JavaScript code we wrote earlier.</p>

<p>And, likewise we can convert the JSON string back into a JavaScript data model again, with:</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">var</span> <span class="nx">mapAgain</span> <span class="o">=</span> <span class="nx">JSON</span><span class="p">.</span><span class="nf">parse</span><span class="p">(</span><span class="nx">mapStringified</span><span class="p">);</span>
</code></pre></div></div>

<p>Now, I did warn you earlier that values can be lists and maps itself again, so consider this
JSON example from Wikipedia:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
    </span><span class="nl">"id"</span><span class="p">:</span><span class="w"> </span><span class="mi">1</span><span class="p">,</span><span class="w">
    </span><span class="nl">"name"</span><span class="p">:</span><span class="w"> </span><span class="s2">"Foo"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"price"</span><span class="p">:</span><span class="w"> </span><span class="mi">123</span><span class="p">,</span><span class="w">
    </span><span class="nl">"tags"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w"> </span><span class="s2">"Bar"</span><span class="p">,</span><span class="w"> </span><span class="s2">"Eek"</span><span class="w"> </span><span class="p">],</span><span class="w">
    </span><span class="nl">"stock"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
        </span><span class="nl">"warehouse"</span><span class="p">:</span><span class="w"> </span><span class="mi">300</span><span class="p">,</span><span class="w">
        </span><span class="nl">"retail"</span><span class="p">:</span><span class="w"> </span><span class="mi">20</span><span class="w">
    </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>Here we see that the value behind the stock key is another map, and the value behind the tags
key is a list. This creates a quite flexible serialization format, which is happily used by
Open PHACTS. (And for the semantic web readers, yes, we can make JSON more semantic. The Open
PHACTS LDA supports a “rdfjson” format.)</p>]]></content><author><name>Egon Willighagen</name></author><category term="pra3006" /><category term="json" /><summary type="html"><![CDATA[As said, JSON is the format we will use as serialization format for answers given by the Open PHACTS LDA. The API actually supports XML, RDF, HTML, and TSV too, but I think JSON is a good balance between expressiveness and compactness. Moreover, and perhaps a much better argument, JSON works very well in a JavaScript environment: it is very easy to convert the serialization into a data model:]]></summary></entry><entry><title type="html">Converting JSON to RDF/XML with Groovy</title><link href="https://chem-bla-ics.linkedchemistry.info/2010/12/29/converting-json-to-rdfxml-with-groovy.html" rel="alternate" type="text/html" title="Converting JSON to RDF/XML with Groovy" /><published>2010-12-29T00:00:00+00:00</published><updated>2010-12-29T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2010/12/29/converting-json-to-rdfxml-with-groovy</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2010/12/29/converting-json-to-rdfxml-with-groovy.html"><![CDATA[<p>Mark’s new <a href="http://www.science3point0.com/blog/2010/12/29/cc0-rdf-hosting-for-scientists/">CCO/RDF hosting functionality</a>
(see also <a href="https://chem-bla-ics.linkedchemistry.info/2010/12/27/what-should-free-cc0-rdf-hosting-for.html">my post two days ago <i class="fa-solid fa-recycle fa-xs"></i></a>)
requires <a href="http://www.w3.org/TR/REC-rdf-syntax/">RDF/XML format</a>, so I updated my code to convert the
<a href="http://chempedia.com/substances">Chempedia Substances</a> data into RDF/XML instead of N3 (I have asked
<a href="http://depth-first.com/">Rich</a> to put a new download link online). This is the
<a href="http://groovy.codehaus.org/">Groovy</a> code I used:</p>

<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">groovy.xml.MarkupBuilder</span>
<span class="kn">import</span> <span class="nn">groovy.util.IndentPrinter</span>

<span class="n">input</span> <span class="o">=</span> <span class="k">new</span> <span class="n">File</span><span class="o">(</span><span class="s2">"substances.json"</span><span class="o">)</span>
<span class="n">json</span> <span class="o">=</span> <span class="k">new</span> <span class="n">JsonSlurper</span><span class="o">().</span><span class="na">parse</span><span class="o">(</span><span class="n">input</span><span class="o">);</span>

<span class="kt">def</span> <span class="n">writer</span> <span class="o">=</span> <span class="k">new</span> <span class="n">StringWriter</span><span class="o">()</span>
<span class="kt">def</span> <span class="n">xml</span> <span class="o">=</span> <span class="k">new</span> <span class="n">MarkupBuilder</span><span class="o">(</span>
  <span class="k">new</span> <span class="nf">IndentPrinter</span><span class="o">(</span><span class="k">new</span> <span class="n">PrintWriter</span><span class="o">(</span><span class="n">writer</span><span class="o">))</span>
<span class="o">)</span>
<span class="n">xml</span><span class="o">.</span><span class="s1">'rdf:RDF'</span><span class="o">(</span>
  <span class="s1">'xmlns:rdf'</span><span class="o">:</span>
    <span class="s1">'http://www.w3.org/1999/02/22-rdf-syntax-ns#'</span><span class="o">,</span>
  <span class="s1">'xmlns:dc'</span> <span class="o">:</span>
    <span class="s1">'http://purl.org/dc/elements/1.1/'</span><span class="o">,</span>
  <span class="s1">'xmlns:iupac'</span> <span class="o">:</span>
    <span class="s1">'http://www.iupac.org/'</span><span class="o">,</span>
  <span class="s1">'xmlns:cp'</span> <span class="o">:</span>
    <span class="s1">'http://rdf.openmolecules.net/chempedia/onto#'</span><span class="o">,</span>
  <span class="s1">'xmlns:owl'</span> <span class="o">:</span>
    <span class="s1">'http://www.w3.org/2002/07/owl#'</span>
<span class="o">)</span> <span class="o">{</span>
  <span class="n">json</span><span class="o">.</span><span class="na">each</span> <span class="o">{</span> <span class="n">substance</span> <span class="o">-&gt;</span>
    <span class="n">xml</span><span class="o">.</span><span class="s1">'rdf:Description'</span><span class="o">(</span>
      <span class="s1">'rdf:about'</span><span class="o">:</span> <span class="n">substance</span><span class="o">.</span><span class="na">uri</span>
    <span class="o">)</span> <span class="o">{</span>
      <span class="n">xml</span><span class="o">.</span><span class="s1">'dc:identifier'</span><span class="o">(</span><span class="n">substance</span><span class="o">.</span><span class="na">gsid</span><span class="o">)</span>
      <span class="n">xml</span><span class="o">.</span><span class="s1">'owl:sameAs'</span><span class="o">(</span>
        <span class="s1">'rdf:resource'</span> <span class="o">:</span>
        <span class="s1">'http://rdf.openmolecules.net/?'</span> <span class="o">+</span>
        <span class="n">substance</span><span class="o">.</span><span class="na">inchi</span>
      <span class="o">)</span>
      <span class="n">xml</span><span class="o">.</span><span class="s1">'iupac:inchi'</span><span class="o">(</span>
        <span class="s1">'http://rdf.openmolecules.net/?'</span> <span class="o">+</span>
        <span class="n">substance</span><span class="o">.</span><span class="na">inchi</span>
      <span class="o">)</span>
      <span class="k">for</span> <span class="o">(</span><span class="kt">int</span> <span class="n">i</span> <span class="o">=</span> <span class="mi">0</span><span class="o">;</span> <span class="n">i</span><span class="o">&lt;</span><span class="n">substance</span><span class="o">.</span><span class="na">namings</span><span class="o">.</span><span class="na">size</span><span class="o">();</span> <span class="n">i</span><span class="o">++)</span>
      <span class="o">{</span>
        <span class="n">naming</span> <span class="o">=</span> <span class="n">substance</span><span class="o">.</span><span class="na">namings</span><span class="o">.</span><span class="na">get</span><span class="o">(</span><span class="n">i</span><span class="o">);</span>
        <span class="n">namingURI</span> <span class="o">=</span> <span class="n">substance</span><span class="o">.</span><span class="na">uri</span> <span class="o">+</span> <span class="s2">"/naming"</span> <span class="o">+</span> <span class="n">i</span><span class="o">;</span>
        <span class="n">xml</span><span class="o">.</span><span class="s1">'cp:hasNaming'</span> <span class="o">{</span>
          <span class="n">xml</span><span class="o">.</span><span class="s1">'rdf:Description'</span> <span class="o">{</span>
            <span class="n">xml</span><span class="o">.</span><span class="s1">'cp:hasName'</span><span class="o">(</span><span class="n">naming</span><span class="o">.</span><span class="na">name</span><span class="o">)</span>
            <span class="n">xml</span><span class="o">.</span><span class="s1">'cp:hasStatus'</span><span class="o">(</span><span class="n">naming</span><span class="o">.</span><span class="na">status</span><span class="o">)</span>
            <span class="n">xml</span><span class="o">.</span><span class="s1">'cp:hasScore'</span><span class="o">(</span><span class="n">naming</span><span class="o">.</span><span class="na">score</span><span class="o">)</span>
          <span class="o">}</span>
        <span class="o">}</span>
      <span class="o">}</span>
    <span class="o">}</span>
  <span class="o">}</span>
<span class="o">}</span>
<span class="n">println</span> <span class="n">writer</span><span class="o">.</span><span class="na">toString</span><span class="o">();</span>
</code></pre></div></div>]]></content><author><name>Egon Willighagen</name></author><category term="groovy" /><category term="chemistry" /><category term="rdf" /><category term="json" /><summary type="html"><![CDATA[Mark’s new CCO/RDF hosting functionality (see also my post two days ago ) requires RDF/XML format, so I updated my code to convert the Chempedia Substances data into RDF/XML instead of N3 (I have asked Rich to put a new download link online). This is the Groovy code I used:]]></summary></entry><entry><title type="html">Pulling out data as JSON from XHTML+RDFa</title><link href="https://chem-bla-ics.linkedchemistry.info/2010/09/10/pulling-out-data-as-json-from-xhtmlrdfa.html" rel="alternate" type="text/html" title="Pulling out data as JSON from XHTML+RDFa" /><published>2010-09-10T00:00:00+00:00</published><updated>2010-09-10T00:00:00+00:00</updated><id>https://chem-bla-ics.linkedchemistry.info/2010/09/10/pulling-out-data-as-json-from-xhtmlrdfa</id><content type="html" xml:base="https://chem-bla-ics.linkedchemistry.info/2010/09/10/pulling-out-data-as-json-from-xhtmlrdfa.html"><![CDATA[<p>I am keen on <a href="/blog/tag/rdfa">RDFa</a> and <a href="http://sv.wikipedia.org/wiki/Resource_Description_Framework">RDF <i class="fa-solid fa-recycle fa-xs"></i></a> in general; that should not be a surprise.
RDFa is a serialization of RDF triples embedded in (X)HTML. I recently posted about <a href="https://chem-bla-ics.linkedchemistry.info/2010/08/10/xhtmlrdfa-chemical-examples.html">chemical examples of XHTML+RDFa <i class="fa-solid fa-recycle fa-xs"></i></a>.
Now, the reason for putting data in HTML as RDFa is that we can easily pull it out again, e.g. with <a href="http://www.w3.org/2007/08/pyRdfa/">this distiller</a>.
But the fun goes on, and we can actually also run SPARQL directly on it, for example with RDFaDev which I
<a href="https://chem-bla-ics.linkedchemistry.info/2010/07/19/scripts-logs-as-htmlrdfa-mix-free-text.html">recently blogged about <i class="fa-solid fa-recycle fa-xs"></i></a>.</p>

<p>Now, consider we have all these nice visualization tools written in JavaScript which can visualize data from <a href="http://www.json.org/">JSON</a> sources,
the mashup requires a JSON serialization of that data embedded in HTML pages. Now, I have no experience with the cool JavaScript tools, and hope
someone can help me out here, but the JSON bit I already <a href="http://www.semanticoverflow.com/questions/587/is-there-a-web-service-that-allow-me-to-run-sparql-against-a-xhtmlrdfa-website">got help with before on SemanticOverflow</a>
(thanx to <a href="http://www.semanticoverflow.com/users/148/comment-bot">Comment Bot</a>!). The service mentioned no longer works, but there are plenty of alternatives.</p>

<p>Now, Peter is creating this nice data set about <a href="http://wwmm.ch.cam.ac.uk/blogs/murrayrust/?p=2596">green solvents from patents</a>, and it would be great of that data ends up online as RDFa, so that we can easily visualize the trends in solvent use over the years. But as I do not have this data as XHTML+RDFa yet, you will have to do with another example: boiling points.</p>

<p>So, let’s consider the data on <a href="https://egonw.github.io/cheminformatics.classics/classic1.html">this page <i class="fa-solid fa-recycle fa-xs"></i></a>, relating paraffin molecules to boiling points, and we’ll take a complexity descriptor (<em>w0</em>, Wiener descriptor) and the boilingpoint (<em>t0</em>). so we get this SPARQL query:</p>

<pre>PREFIX cc: &lt;http://github.com/egonw/cheminformatics.classics/1/#&gt;

SELECT * {
    ?mol cc:w0 ?w ;
         cc:p0 ?p .
}
</pre>

<p>Now, we want to run this query on the aforementioned page, so we add a FROM clause:</p>

<pre>PREFIX cc: &lt;http://github.com/egonw/cheminformatics.classics/1/#&gt;

SELECT *
FROM &lt;http://www.w3.org/2007/08/pyRdfa/extract?uri=http%3A%2F%2Fegonw.github.com%2Fcheminformatics.classics%2Fclassic1.html&amp;format=pretty-xml&amp;warnings=false&amp;parser=lax&amp;space-preserve=true&gt;
{
    ?mol cc:w0 ?w ;
         cc:p0 ?p .
}
</pre>

<p>Notice the use of the distiller here. This way, with a service like <a href="http://sparql.org/sparql.html">that on sparql.org</a>, we can get JSON returned. The result is a bit verbose, but that can perhaps be tuned:</p>

<pre>{
  "head": {
    "vars": [ "w" , "p" ]
  } ,
  "results": {
    "bindings": [
      {
        "w": { "datatype": "http://www.w3.org/2001/XMLSchema#integer" , "type": "typed-literal" , "value": "56" } ,
        "p": { "datatype": "http://www.w3.org/2001/XMLSchema#integer" , "type": "typed-literal" , "value": "4" }
      } ,
      {
        "w": { "datatype": "http://www.w3.org/2001/XMLSchema#integer" , "type": "typed-literal" , "value": "35" } ,
        "p": { "datatype": "http://www.w3.org/2001/XMLSchema#integer" , "type": "typed-literal" , "value": "3" }
      }
    ]
  }
}
</pre>

<p>The point is, I am sure at least one of my readers knows how to visualize the data in <a href="http://sparql.org/sparql?query=PREFIX+cc%3A+%3Chttp%3A%2F%2Fgithub.com%2Fegonw%2Fcheminformatics.classics%2F1%2F%23%3E%0D%0A%0D%0ASELECT+%3Fw+%3Fp%0D%0AFROM+%3Chttp%3A%2F%2Fwww.w3.org%2F2007%2F08%2FpyRdfa%2Fextract%3Furi%3Dhttp%253A%252F%252Fegonw.github.com%252Fcheminformatics.classics%252Fclassic1.html%26format%3Dpretty-xml%26warnings%3Dfalse%26parser%3Dlax%26space-preserve%3Dtrue%3E%0D%0A%7B%0D%0A++++%3Fmol+cc%3Aw0+%3Fw+%3B%0D%0A+++++++++cc%3Ap0+%3Fp+.%0D%0A%7D&amp;default-graph-uri=&amp;stylesheet=%2Fxml-to-html.xsl&amp;output=json&amp;force-accept=text%2Fplain">this JSON</a> with, for example, <a href="http://code.google.com/apis/chart/">Google Chart</a>, particularly, because all the mashing up is embedded in the just linked-to, though obscure, URL. And, if it helps, you can otherwise use the <a href="http://sparql.org/sparql?query=PREFIX+cc%3A+%3Chttp%3A%2F%2Fgithub.com%2Fegonw%2Fcheminformatics.classics%2F1%2F%23%3E%0D%0A%0D%0ASELECT+%3Fw+%3Fp%0D%0AFROM+%3Chttp%3A%2F%2Fwww.w3.org%2F2007%2F08%2FpyRdfa%2Fextract%3Furi%3Dhttp%253A%252F%252Fegonw.github.com%252Fcheminformatics.classics%252Fclassic1.html%26format%3Dpretty-xml%26warnings%3Dfalse%26parser%3Dlax%26space-preserve%3Dtrue%3E%0D%0A%7B%0D%0A++++%3Fmol+cc%3Aw0+%3Fw+%3B%0D%0A+++++++++cc%3Ap0+%3Fp+.%0D%0A%7D&amp;default-graph-uri=&amp;stylesheet=%2Fxml-to-html.xsl&amp;output=csv&amp;force-accept=text%2Fplain">CSV</a> or <a href="http://sparql.org/sparql?query=PREFIX+cc%3A+%3Chttp%3A%2F%2Fgithub.com%2Fegonw%2Fcheminformatics.classics%2F1%2F%23%3E%0D%0A%0D%0ASELECT+%3Fw+%3Fp%0D%0AFROM+%3Chttp%3A%2F%2Fwww.w3.org%2F2007%2F08%2FpyRdfa%2Fextract%3Furi%3Dhttp%253A%252F%252Fegonw.github.com%252Fcheminformatics.classics%252Fclassic1.html%26format%3Dpretty-xml%26warnings%3Dfalse%26parser%3Dlax%26space-preserve%3Dtrue%3E%0D%0A%7B%0D%0A++++%3Fmol+cc%3Aw0+%3Fw+%3B%0D%0A+++++++++cc%3Ap0+%3Fp+.%0D%0A%7D&amp;default-graph-uri=&amp;stylesheet=%2Fxml-to-html.xsl&amp;output=tsv&amp;force-accept=text%2Fplain">TSV</a> output. The output of that is even more simple (CSV):</p>

<pre>w,p
56,4
286,9
35,3
220,8
20,2
84,5
10,1
165,7
120,6
</pre>

<p>The first one who can use one of the above URLs to extract the data from that XHTML+RDFa page to create a scatter plot in a HTML page with some JavaScript library, wins a free mention in my blog! ;)</p>]]></content><author><name>Egon Willighagen</name></author><category term="chemistry" /><category term="html" /><category term="rdfa" /><category term="sparql" /><category term="json" /><summary type="html"><![CDATA[I am keen on RDFa and RDF in general; that should not be a surprise. RDFa is a serialization of RDF triples embedded in (X)HTML. I recently posted about chemical examples of XHTML+RDFa . Now, the reason for putting data in HTML as RDFa is that we can easily pull it out again, e.g. with this distiller. But the fun goes on, and we can actually also run SPARQL directly on it, for example with RDFaDev which I recently blogged about .]]></summary></entry></feed>